virc
收藏资源简介:
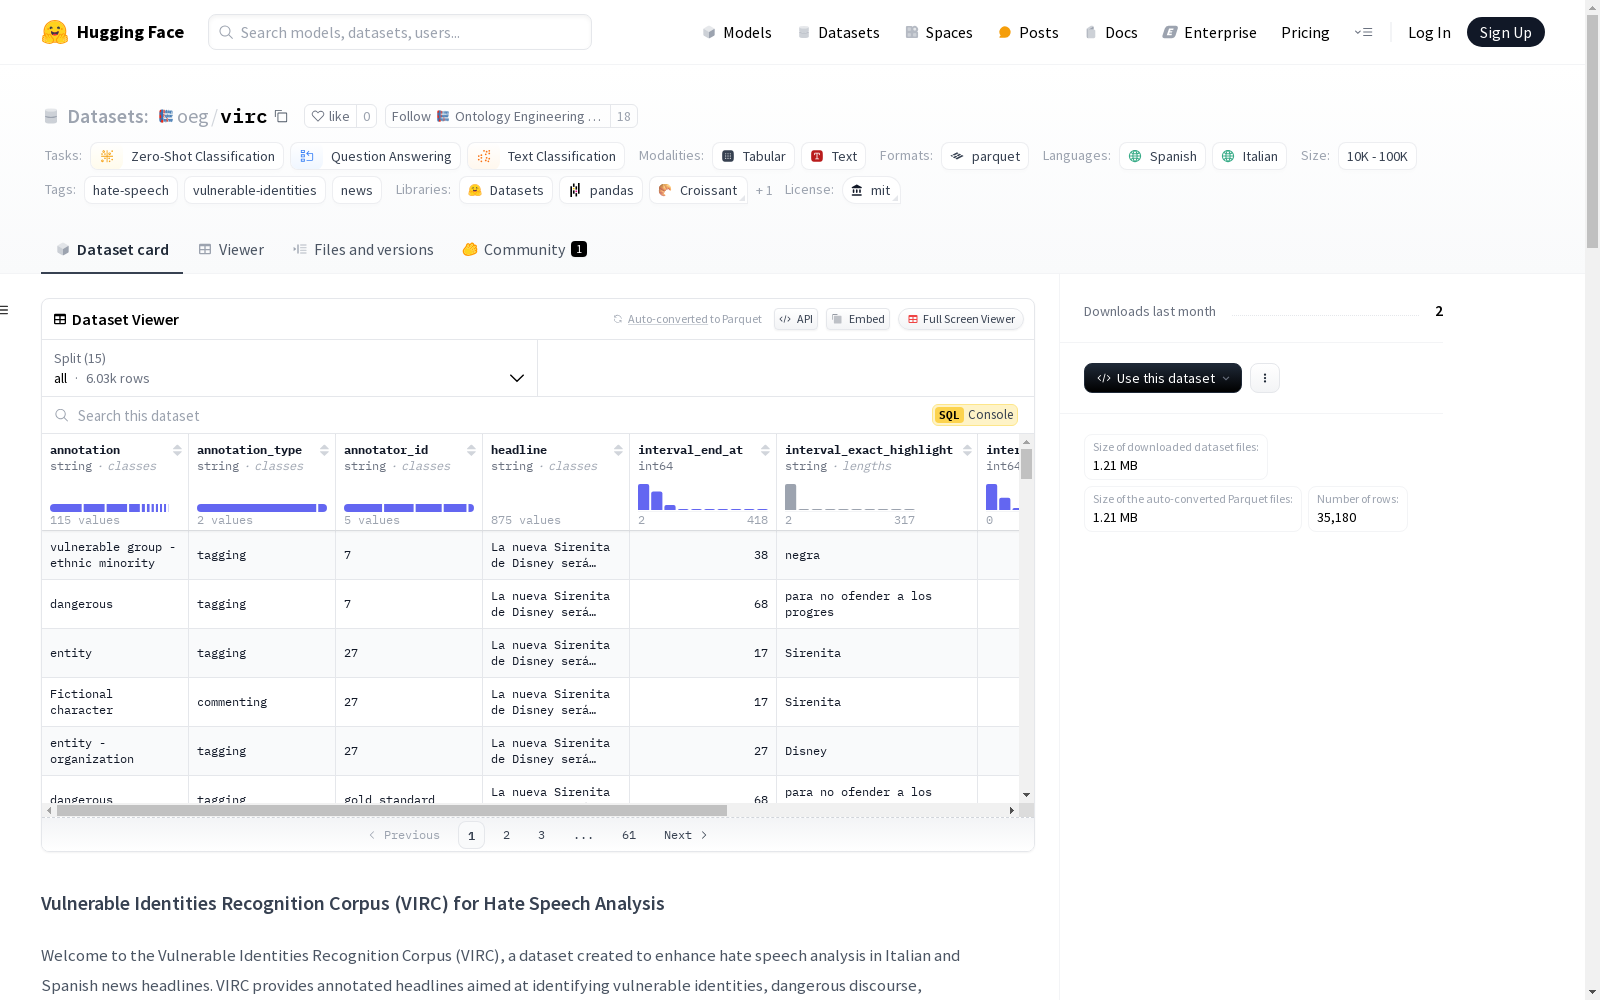
VIRC(Vulnerable Identities Recognition Corpus)是一个用于增强意大利语和西班牙语新闻标题中仇恨言论分析的数据集。该数据集包含880条标题(532条意大利语和348条西班牙语),并标注了命名实体、脆弱身份提及、贬义提及和危险言论等标签。数据集分为多个子集,包括西班牙语和意大利语的注释、黄金标准注释和注释者评论。VIRC旨在支持开发更复杂的仇恨言论检测工具,并为创建更安全的在线环境提供政策支持。
VIRC (Vulnerable Identities Recognition Corpus) is a dataset developed to enhance hate speech analysis for Italian and Spanish news headlines. This dataset contains 880 headlines, with 532 in Italian and 348 in Spanish, and is annotated with labels including named entities, vulnerable identity mentions, derogatory references, and harmful speech. The dataset is divided into multiple subsets, namely annotations for Spanish and Italian content, gold standard annotations, and annotator comments. VIRC aims to support the development of more sophisticated hate speech detection tools, and provide policy support for building safer online environments.