whittle-teacher32-complete-answers
收藏资源简介:
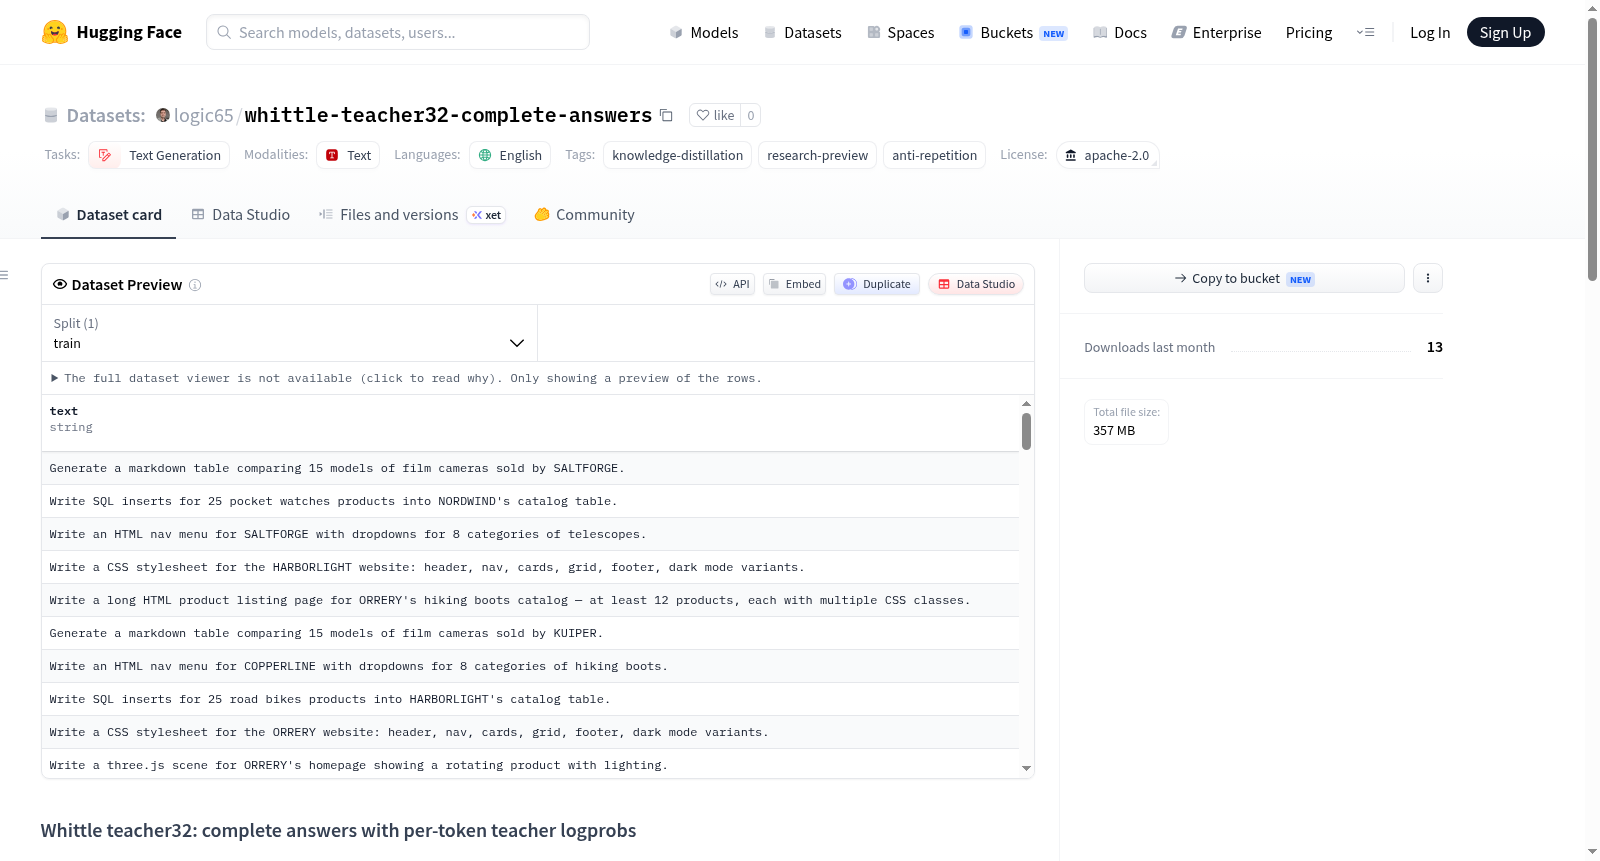
Whittle teacher32: complete answers with per-token teacher logprobs 是一个用于知识蒸馏研究的数据集,作为 Whittle 压缩项目的一部分。该数据集由教师模型 Qwen3.8-27B(通过 llama.cpp 以 UD-Q5_K_XL 量化版本运行)生成的完整答案组成,每个答案在生成每个位置时捕获了教师模型的 top-32 logprobs。数据集的目的是训练学生模型理解答案何时完成,以避免重复并学习内容条件化的停止行为。数据集包含多个家族:enum(25个提示×2个种子,生成编号列表)、short(14个提示×2个种子,单句答案)、medium(8个提示×2个种子,自然长度解释)、code(5个提示×2个种子,代码块答案)、convo(8个脚本×2个种子,5-6轮对话,包含枚举请求)、extra(70个提示×1个种子,结构化输出如SQL、HTML、markdown表格、JSON)。所有提示与评估集不相交。最终计数为245行(enum 44, short 40, medium 12, code 8, extra 45, convo 96),包含178k教师目标token。已知缺陷:3行因写入中断丢失,控制台日志未保存,部分超长结构化提示因超出4096 token预算被跳过。Extra家族中少于400答案token的为教师 stub 模式响应,建议在蒸馏训练前过滤。数据格式包括 JSONL 文件(每行包含 key, family, prompt|convo, seed, input_ids, spans, idx, val),其中 spans 表示助手答案的 token 范围,idx/val 是每个位置 top-32 教师 token ID 和 logprobs。NPZ 文件提供训练缓存。教师模型使用 temperature 0.6, top_p 0.9, top_k 40, 固定种子。许可证为 Apache 2.0。
Whittle teacher32: complete answers with per-token teacher logprobs is a dataset for knowledge distillation research, as part of the Whittle compression project. The dataset consists of complete answers generated by the teacher model Qwen3.8-27B (run via llama.cpp in UD-Q5_K_XL quantization), capturing the top-32 logprobs from the teacher model at each token position. The goal is to train student models to understand when an answer is complete, to avoid repetition and learn content-conditioned stopping behavior. The dataset includes multiple families: enum (25 prompts × 2 seeds, generating numbered lists), short (14 prompts × 2 seeds, single-sentence answers), medium (8 prompts × 2 seeds, natural-length explanations), code (5 prompts × 2 seeds, code block answers), convo (8 scripts × 2 seeds, 5-6 turn dialogues including enumeration requests), and extra (70 prompts × 1 seed, structured outputs like SQL, HTML, markdown tables, JSON). All prompts are disjoint from the evaluation set. The final count is 245 rows (enum 44, short 40, medium 12, code 8, extra 45, convo 96), containing 178k teacher target tokens. Known issues: 3 rows lost due to write interruption, console logs not saved, some very long structured prompts skipped due to exceeding 4096 token budget. Extra family answers with fewer than 400 answer tokens are teacher stub mode responses; it is recommended to filter them before distillation training. Data format includes JSONL files (each line contains key, family, prompt|convo, seed, input_ids, spans, idx, val) where spans indicate token ranges of assistant answers, and idx/val are top-32 teacher token IDs and logprobs at each position. NPZ files provide training cache. The teacher model uses temperature 0.6, top_p 0.9, top_k 40, with fixed seeds. License: Apache 2.0.
Whittle teacher32: 完整答案与逐词元教师对数概率数据集
数据集概览
本数据集属于 Whittle 压缩项目(研究预览版),由个人研究项目自筹资金支持。该数据集旨在解决知识蒸馏中的一个关键问题:压缩学生模型缺少“答案何时完成”的信号。
核心内容
数据集包含由 Qwen3.8-27B(UD-Q5_K_XL 量化版,通过 llama.cpp 推理)生成的完整答案,每个答案均以真实结束词元(EOS)结尾,并记录了每个生成位置的教师模型 top-32 对数概率(logprobs),用于训练学生模型学习何时停止生成。
数据家族
| 家族 | 规模 | 用途 |
|---|---|---|
| enum | 25 提示词 × 2 种子 | 编号列表(以第 N 项结尾) |
| short | 14 × 2 | 单句答案,早期停止锚点 |
| medium | 8 × 2 | 自然长度的解释 |
| code | 5 × 2 | 围栏代码答案 |
| convo | 8 脚本 × 2 种子 | 5-6 轮对话,包含后期轮次枚举请求(已测量的失败场景) |
| extra | 70 × 1 | 结构化输出(SQL、HTML、Markdown 表格、JSON),来自真实失败提示 |
所有提示词均与评估集不重叠。未在 token 预算内以干净 EOS 结束的行被跳过并记录,不会存入数据。
最终统计(2026年8月21日)
- 总行数:245 行(enum 44、short 40、medium 12、code 8、extra 45、convo 96,每行对应一个助手回答轮次)
- 上下文长度:最高 6.4k tokens
- 教师目标 tokens 总数:178k
- 已知瑕疵:3 行因中途写入错误丢失(已从修复的 jsonl 重建 npz);生成控制台日志未存留;少量超长结构化提示在 4096-token 预算内未结束,被跳过而非截断。extra 家族中低于 400 答案 token 的行属于教师 stub 模式响应,应在蒸馏训练前过滤。
文件格式
teacher_complete.jsonl:每行一个答案或对话,包含字段{key, family, prompt|convo, seed, input_ids, spans, idx, val}。spans为助手答案的 [start, end) token 区间;idx/val为每个位置 top-32 教师 token id 和对数概率(位置 p 对应生成 token p+1 的分布;助手区间外的位置为垃圾填充,需掩码)。teacher_complete.npz:训练器缓存(row_ids, lengths, idx, val, topk)gen_teacher_v2.py:精确生成脚本(用于溯源)extra_prompts.json:收集的结构化输出提示
教师模型与生成参数
- 教师模型:Qwen/Qwen3.8-27B(Unsloth UD-Q5_K_XL GGUF),由 llama.cpp 服务,禁用思维链
- 对数概率:全词汇表采样前 softmax,每位置 top-32,在相同生成调用中捕获
- 采样参数:温度 0.6、top_p 0.9、top_k 40,固定种子
许可证
Apache 2.0(与教师模型许可证一致)。提示词为项目原创或为其早期 on-policy 采集生成。