
XGuard v22 内容安全分类数据集
收藏官方服务:
资源简介:
该数据集覆盖多语言(中/英)内容安全场景,包括但不限于:有害内容、欺诈、暴力、色情、仇恨言论等风险类别,以及安全内容的负样本。数据经过多轮清洗、标签校正、对抗样本增强和类别平衡处理。样本量:1,218,808 条,标签体系:33 类(29 标准标签 + 4 个 cn_* 中文动态策略标签),格式:JSONL(对话式 SFT 格式)
This dataset covers multilingual (Chinese/English) content security scenarios, including but not limited to risk categories such as harmful content, fraud, violence, pornography, hate speech, as well as negative samples of safe content. The data has undergone multiple rounds of cleaning, label correction, adversarial sample augmentation, and category balancing. The sample size is 1,218,808 entries, with a label system consisting of 33 categories (29 standard labels + 4 cn_* Chinese dynamic policy labels). The format is JSONL (conversational SFT format).
提供机构:
maas创建时间:
2026-04-28
搜集汇总
数据集介绍
背景与挑战
背景概述
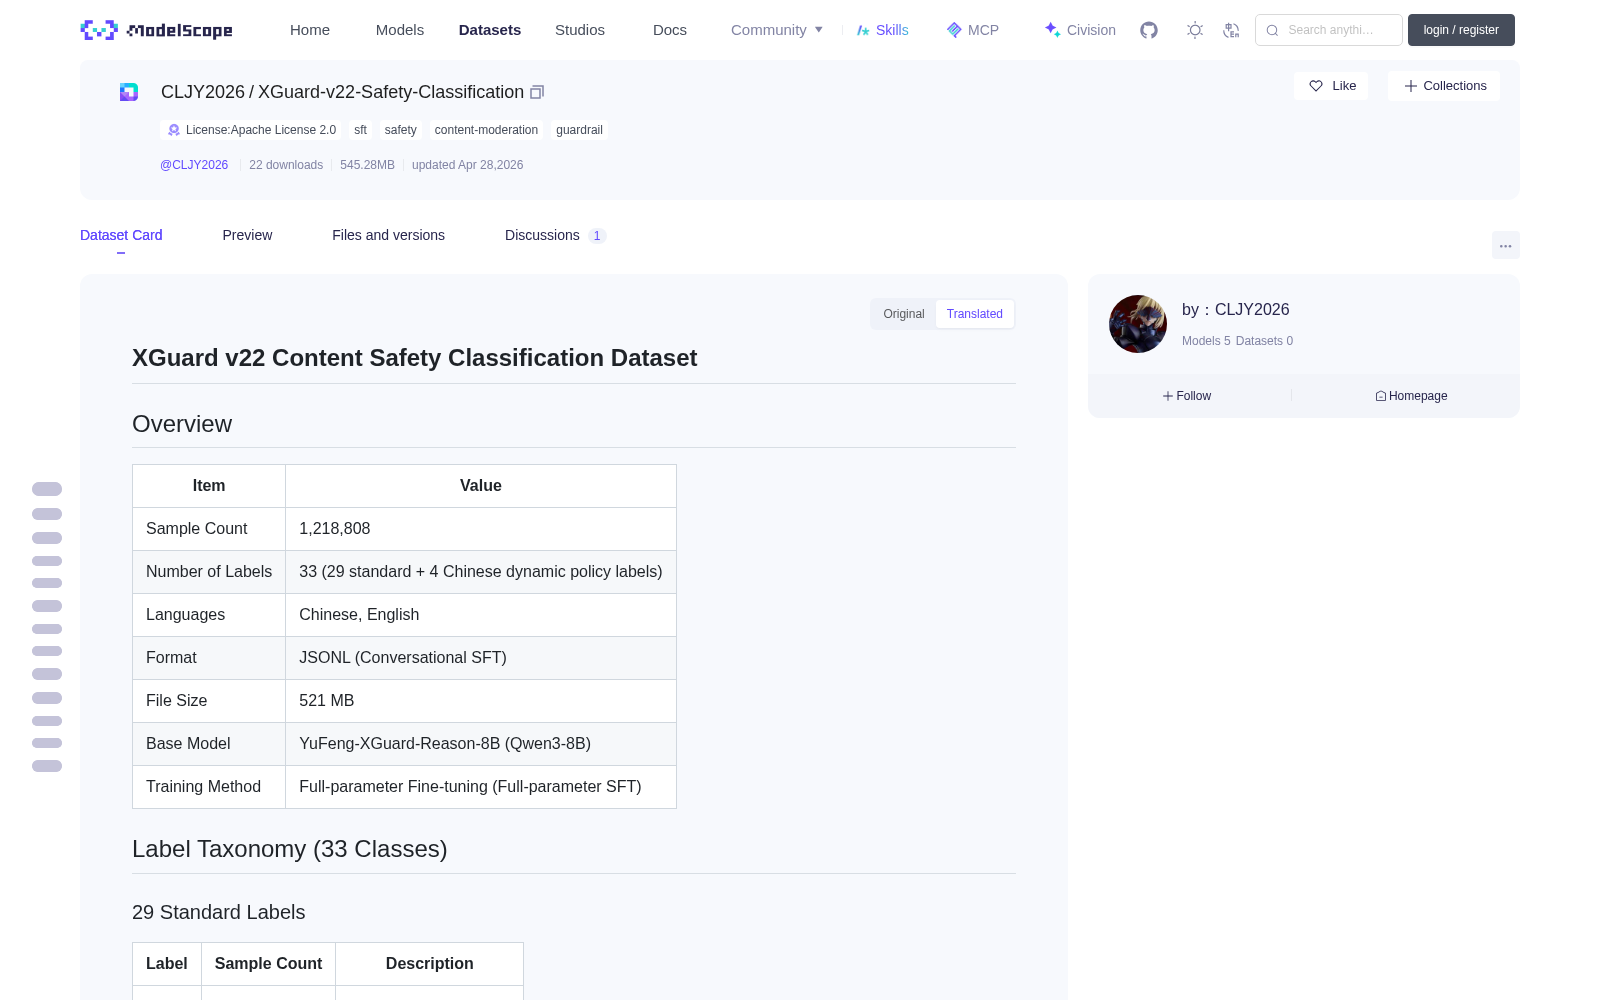
XGuard v22 内容安全分类数据集是一个用于对话式SFT训练的大规模数据集,包含超过121万个样本,涵盖33个安全相关标签,支持中英文。数据以JSONL格式组织,基于YuFeng-XGuard-Reason-8B模型进行全参数微调,适用于内容安全分类任务。
以上内容由遇见数据集搜集并总结生成


