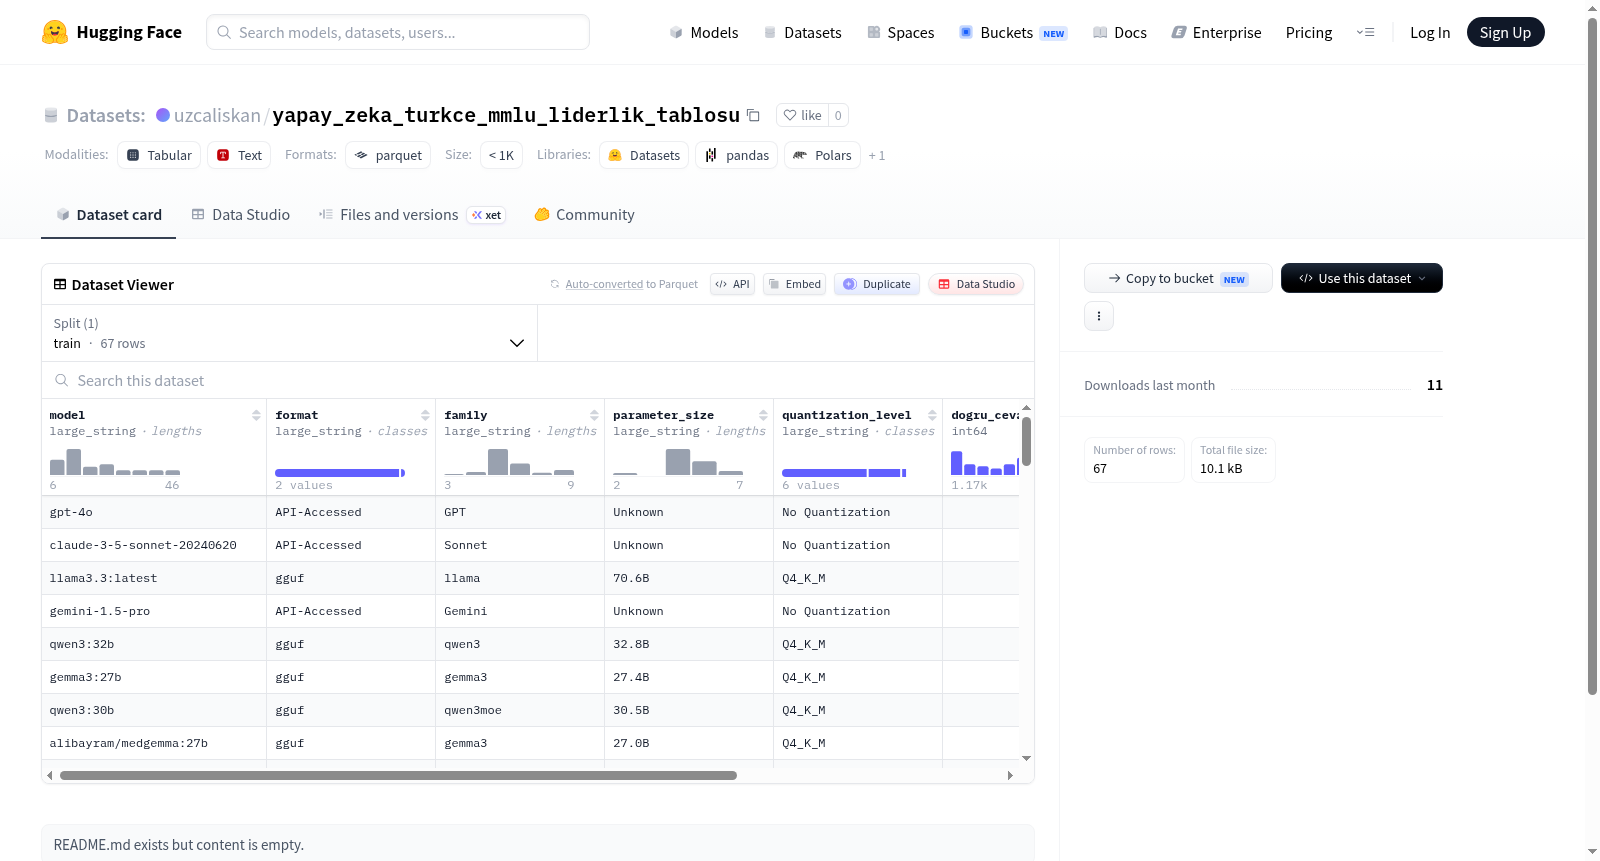
yapay_zeka_turkce_mmlu_liderlik_tablosu
收藏资源简介:
该数据集是一个用于模型评估或基准测试的数据集,包含67个样本,每个样本代表一个特定模型配置及其在某个任务上的性能表现。数据集字段包括模型标识信息(如模型名称、所属系列/家族、参数量、量化级别)和性能指标(如正确回答数量、成功率/准确率、总耗时,其中字段名称为土耳其语)。性能评估基于一个问答或问题解决任务,适用于分析不同模型架构、参数量或量化级别对任务性能(准确率与效率)的影响。
This dataset is designed for model evaluation or benchmarking, containing 67 samples, each representing a specific model configuration and its performance on a task. The dataset fields include model identification information (such as model name, series/family, parameter count, quantization level) and performance metrics (such as correct answer count, success rate/accuracy, total time taken, with field names in Turkish). The performance evaluation is based on a question-answering or problem-solving task, making it suitable for analyzing the impact of different model architectures, parameter counts, or quantization levels on task performance (accuracy and efficiency).
- 数据集名称:yapay_zeka_turkce_mmlu_liderlik_tablosu
- 数据集地址:https://huggingface.co/datasets/uzcaliskan/yapay_zeka_turkce_mmlu_liderlik_tablosu
- 数据集描述:该数据集包含模型在土耳其语MMLU任务上的表现排行榜,记录不同模型的正确回答数量、成功率及总耗时。
- 特征字段:
model:模型名称(字符串类型)format:模型格式(字符串类型)family:模型家族(字符串类型)parameter_size:参数量大小(字符串类型)quantization_level:量化等级(字符串类型)dogru_cevap_sayisi:正确回答数量(整数类型)basari:成功率(浮点数类型)toplam_sure:总耗时(浮点数类型)
- 数据划分:
- 仅包含训练集(
train),共67个样本,数据集大小为7017字节,下载大小为6981字节。
- 仅包含训练集(
- 配置:
- 默认配置(
default),训练数据文件路径为data/train-*。
- 默认配置(