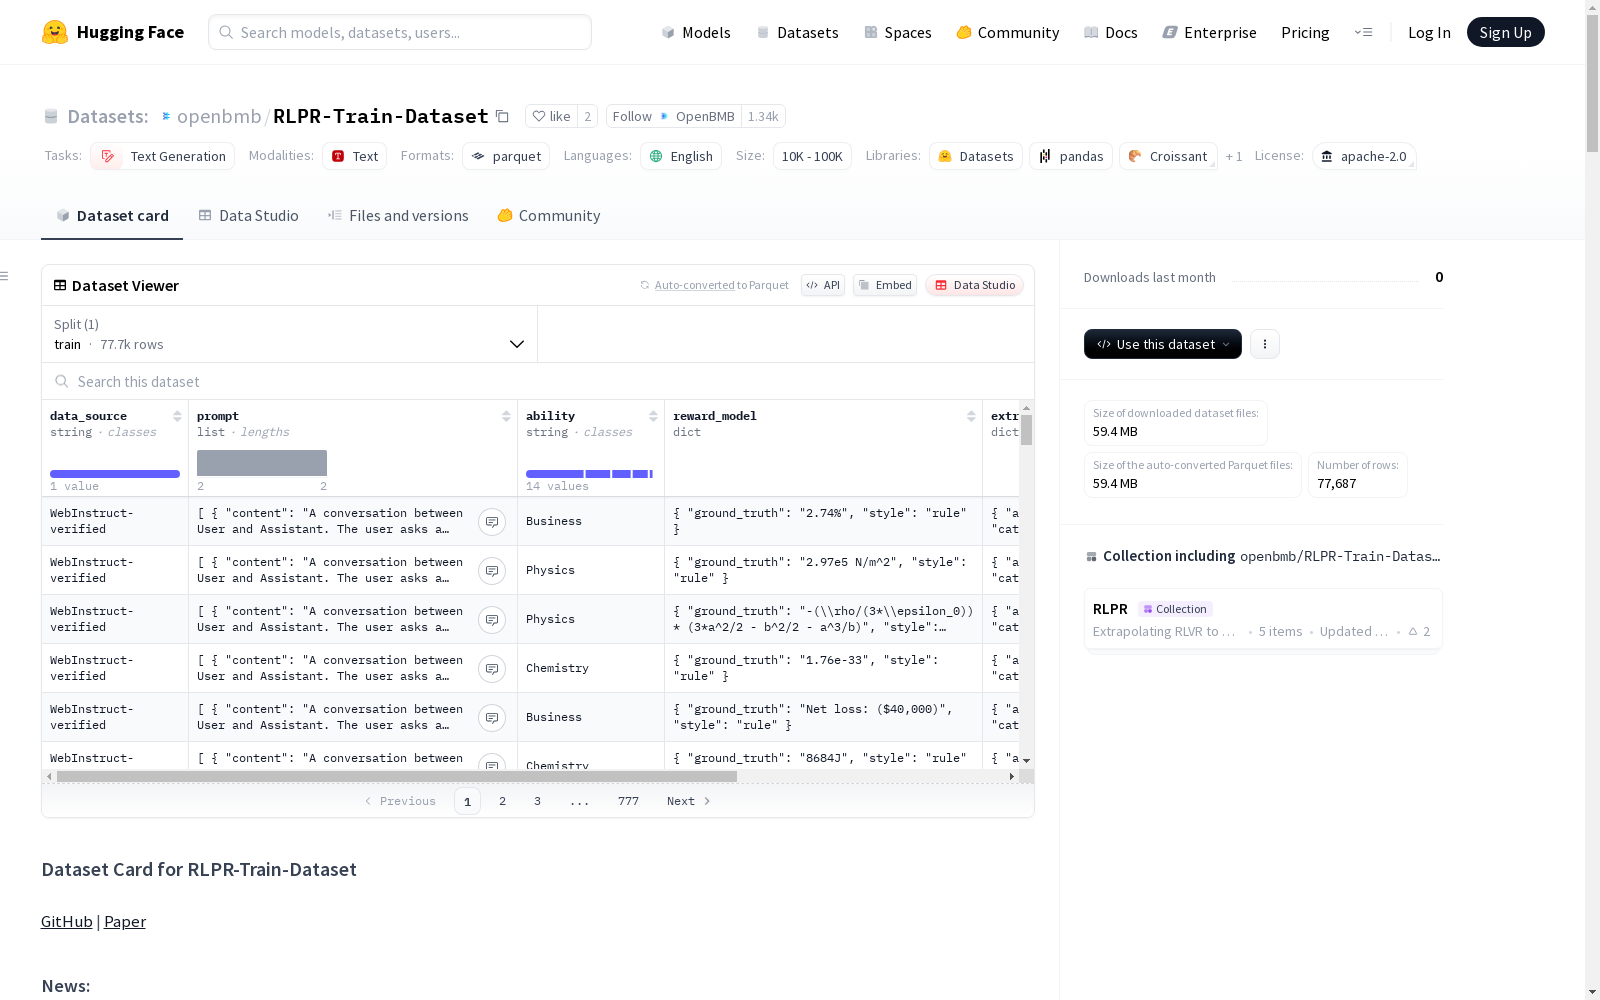
RLPR-Train-Dataset
收藏资源简介:
RLPR-Train-Dataset是一个经过精心策划的数据集,包含77k个高质量的推理提示,专门设计用于增强大型语言模型在通用领域(非数学)的推理能力。该数据集从WebInstruct的全面提示集合中衍生而出,通过选择非数学提示并使用GPT-4.1过滤掉过于简单的提示,确保了训练集的挑战性和有效性。使用RLPR框架和此数据集训练模型,可以显著提高模型在不依赖外部验证器的情况下进行推理的能力。
RLPR-Train-Dataset is a carefully curated dataset containing 77k high-quality reasoning prompts, specifically designed to enhance the reasoning capabilities of large language models (LLMs) in general-domain (non-mathematical) scenarios. Derived from the comprehensive prompt collection of WebInstruct, this dataset ensures the training set is both challenging and effective by selecting non-mathematical prompts and filtering out overly simplistic ones using GPT-4.1. Training a model with the RLPR framework and this dataset can significantly improve the model's ability to perform reasoning without relying on external validators.
RLPR-Train-Dataset 数据集概述
基本信息
- 许可证: Apache-2.0
- 任务类别: 文本生成
- 语言: 英语
- 数据集名称: RLPR-Train-Dataset
- 规模: 10K < n < 100K
数据集摘要
- 内容: 包含77k高质量推理提示,专为增强大型语言模型(LLM)在**通用领域(非数学)**的推理能力而设计。
- 来源: 基于WebInstruct的提示集合,筛选非数学提示,并使用GPT-4.1过滤过于简单的提示。
- 用途: 用于RLPR框架训练,显著提升模型推理能力,无需外部验证器。
关键特点
- 领域: 非数学通用领域
- 挑战性: 提示经过筛选,确保具有适当难度
- 效果: 在MMLU-Pro和TheoremQA等基准测试中表现优异(如Qwen2.5-7B模型达到56.0和55.4分)
数据结构
每个样本包含以下字段:
| 字段名 | 描述 |
|---|---|
data_source |
提示的原始来源 |
prompt |
对话式提示列表,包含系统消息和用户问题 |
ability |
推理任务的类别或领域 |
reward_model |
包含参考答案和样式信息,用于RLPR框架中的奖励计算 |
extra_info |
元数据,包括答案类型、类别、难度、唯一ID、推理分数解释和令牌计数 |
__index_level_0__ |
数据样本的内部索引 |
使用示例
python from datasets import load_dataset dataset = load_dataset("openbmb/RLPR-Train-Dataset")
致谢
- 数据集源自WebInstruct
引用
bibtex @article{yu2025rlpr, title={RLPR: Extrapolating RLVR to General Domains without Verifiers}, author={Yu, Tianyu and Ji, Bo and Wang, Shouli and Yao, Shu and Wang, Zefan and Cui, Ganqu and Yuan, Lifan and Ding, Ning and Yao, Yuan and Liu, Zhiyuan and Sun, Maosong and Chua, Tat-Seng}, journal={arXiv preprint arXiv:2506.xxxxx}, year={2025} }