rebase_vgs_gemma-4-E4B-it_rg_cognition_ns8_md4_bt0_1_seed42_rg_cognition_vgs_2gpu
收藏资源简介:
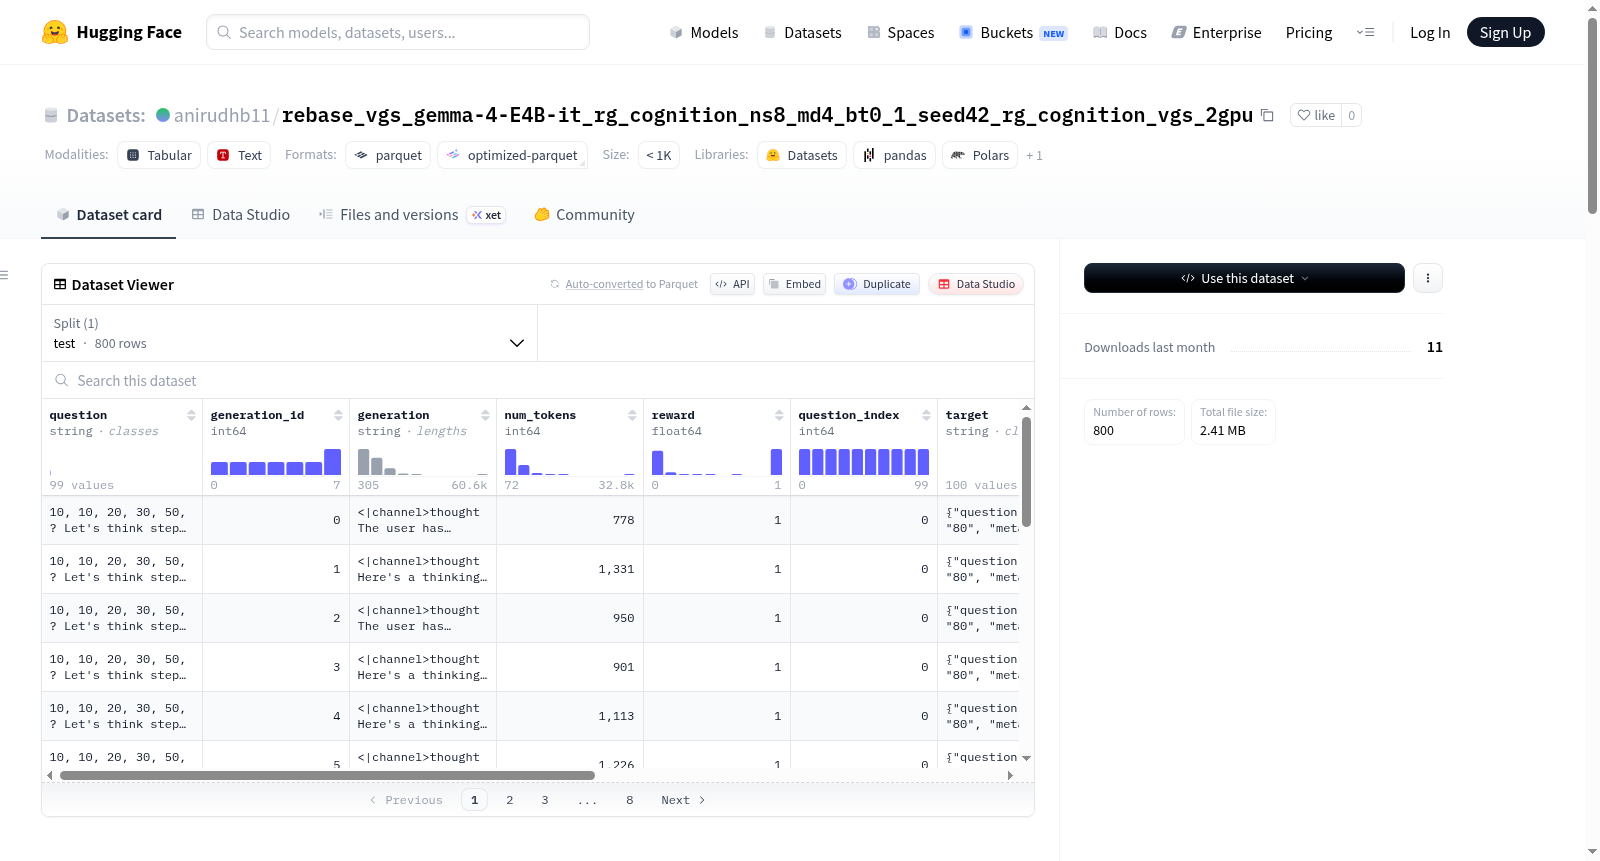
该数据集包含800个测试样本,每个样本包含多个特征字段:问题文本(question)、生成ID(generation_id)、生成内容(generation)、token数量(num_tokens)、奖励值(reward)、问题索引(question_index)、目标文本(target)、任务类型(task)、价值函数预测(vf_prediction)和层级(level)。数据集总大小为8,958,545字节,下载大小为2,396,010字节。聚合指标显示,数据来自10个分片,包含平均响应token数(2749.41)、各层级生成token数(如level_1为181885)、不同评估指标(如pass@1为0.46875)等详细性能数据。虽然缺少明确的背景说明,但从特征字段和评估指标推断,该数据集可能用于评估文本生成模型的性能。
This dataset contains 800 test samples. Each sample includes multiple feature fields: question (question text), generation_id (generation ID), generation (generated content), num_tokens (token count), reward (reward value), question_index (question index), target (target text), task (task type), vf_prediction (value function prediction), and level. The total size of the dataset is 8,958,545 bytes, with a download size of 2,396,010 bytes. Aggregated metrics show that the data is split into 10 shards, and contains detailed performance data including the average number of response tokens (2749.41), the number of generated tokens per level (e.g., 181885 for level_1), and various evaluation metrics (e.g., a pass@1 score of 0.46875). Although no explicit background description is provided, it can be inferred from the feature fields and evaluation metrics that this dataset may be used to evaluate the performance of text generation models.
根据您提供的数据集详情页面README文件内容,以下是对该数据集的概述:
数据集概述
基本信息
- 数据集名称:
rebase_vgs_gemma-4-E4B-it_rg_cognition_ns8_md4_bt0_1_seed42_rg_cognition_vgs_2gpu - 来源:Hugging Face
- 下载大小:2,396,010 字节
- 数据集大小:8,958,545 字节
数据集结构
特征(Features)
数据集包含以下10个字段:
| 字段名称 | 数据类型 | 说明 |
|---|---|---|
question |
string | 问题文本 |
generation_id |
int64 | 生成ID |
generation |
string | 生成的回答内容 |
num_tokens |
int64 | 生成的token数量 |
reward |
float64 | 奖励值 |
question_index |
int64 | 问题索引 |
target |
string | 目标答案 |
task |
string | 任务名称 |
vf_prediction |
float64 | 价值函数预测值 |
level |
int64 | 难度等级 |
数据划分(Splits)
- 测试集(test):包含 800 个样本,占用 8,958,545 字节。
聚合指标(Aggregated Metrics)
该数据集基于 10 个分片(shards)进行聚合,主要指标如下:
生成质量指标
| 指标 | 值 |
|---|---|
maj@1 |
0.4968 |
maj@2 |
0.4907 |
maj@4 |
0.5096 |
maj@8 |
0.5260 |
pass@1 |
0.4688 |
pass@2 |
0.5307 |
pass@4 |
0.5679 |
pass@8 |
0.5900 |
生成效率指标
| 指标 | 值 |
|---|---|
avg_response_tokens |
2,749.41 |
median_response_tokens |
2,013.80 |
total_generated_output_tokens |
219,958 |
total_policy_output_tokens |
219,958 |
时间指标
| 指标 | 值 |
|---|---|
generation_phase_time_s |
235.107 |
total_time_s |
250.256 |
多样性指标
| 指标 | 值 |
|---|---|
num_unique_answers@1 |
0.932 |
num_unique_answers@2 |
1.319 |
num_unique_answers@4 |
1.979 |
num_unique_answers@8 |
3.242 |
配置(Configs)
- 默认配置:
default,数据文件路径为data/test-*(仅包含测试集分片)。