fleurs-en-test
收藏资源简介:
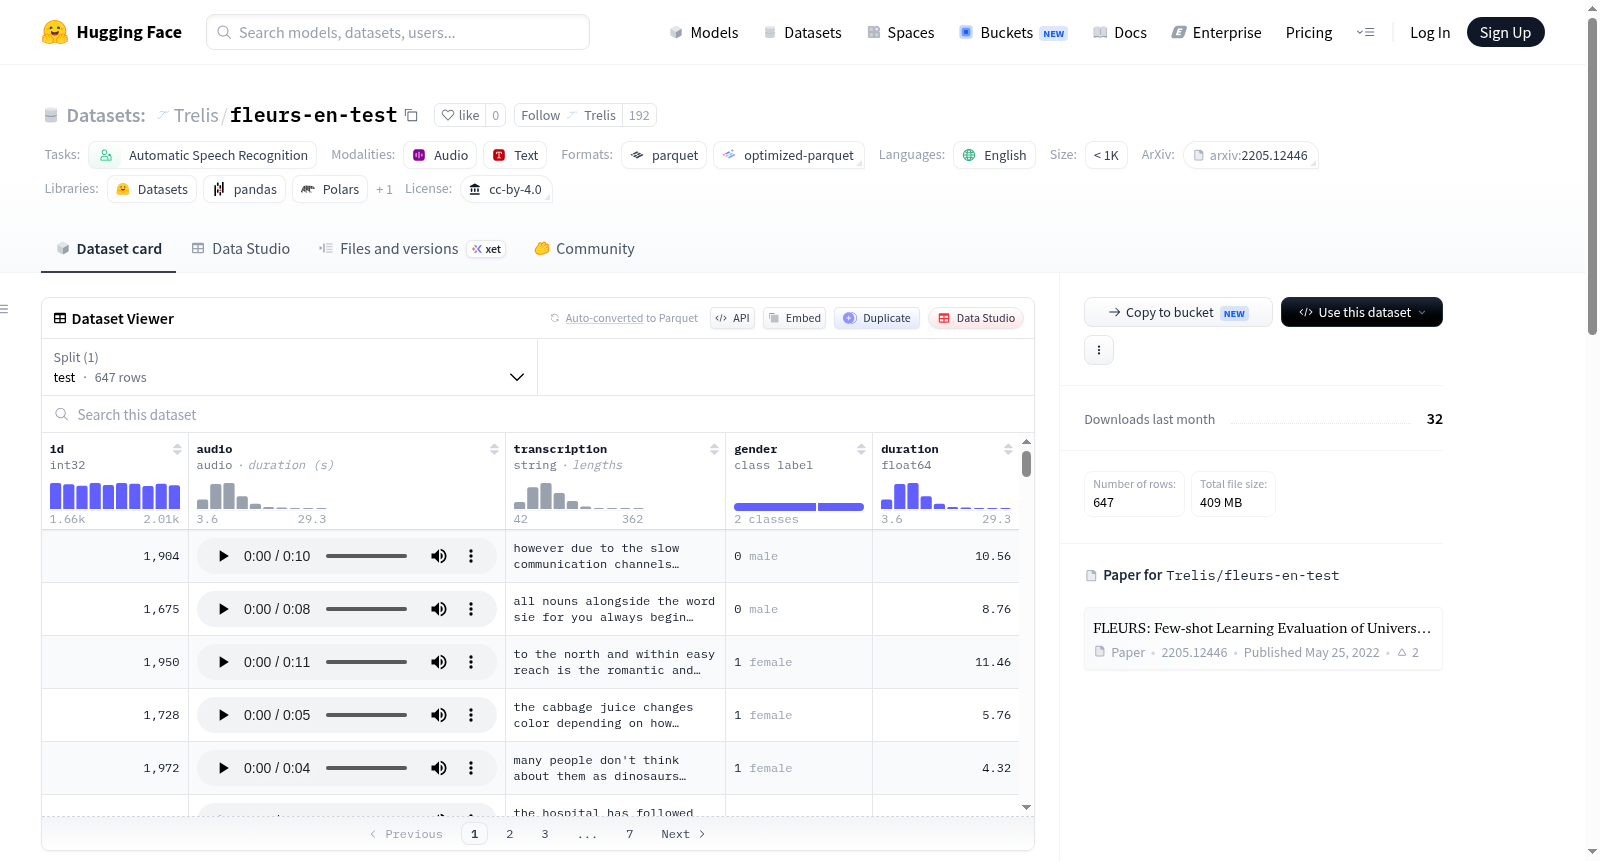
FLEURS英语测试集(Trelis)是一个用于自动语音识别(ASR)基准测试的私有评估数据集。该数据集源自Google的FLEURS(Few-shot Learning Evaluation of Universal Representations of Speech)数据集,具体采用其英语(en_us)配置的测试分割。FLEURS是一个标准的跨语言ASR基准,涵盖102种语言,旨在评估通用语音表示的少样本学习性能。本数据集包含647个语音话语样本,数据构建过程中未进行任何过滤或子采样,完全保留了原始FLEURS en_us测试分割的内容。每个样本包含以下字段:audio(语音录音,以原始字节形式存储以避免编解码器依赖)、transcription(参考文本,由上游字段重命名而来)、id(原始FLEURS话语的唯一标识符)、gender(说话者性别)、duration(语音持续时间,以秒为单位,通过样本数除以16000计算得出)。数据集适用于英语自动语音识别任务的性能评估与基准测试,采用CC-BY-4.0许可证。
The FLEURS English Test Set (Trelis) is a private evaluation dataset for automatic speech recognition (ASR) benchmarking. It is derived from Googles FLEURS (Few-shot Learning Evaluation of Universal Representations of Speech) dataset, specifically using the test split of its English (en_us) configuration. FLEURS is a standard cross-lingual ASR benchmark covering 102 languages, designed to evaluate few-shot learning performance of universal speech representations. This dataset contains 647 speech utterance samples, with no filtering or subsampling applied during data construction, fully preserving the content of the original FLEURS en_us test split. Each sample includes the following fields: audio (speech recordings stored as raw bytes to avoid codec dependencies), transcription (reference text, renamed from upstream fields), id (unique identifier for the original FLEURS utterance), gender (speaker gender), duration (speech duration in seconds, calculated by dividing the number of samples by 16000). The dataset is suitable for performance evaluation and benchmarking of English automatic speech recognition tasks, and is licensed under CC-BY-4.0.
FLEURS English Test Set (Trelis)
数据集概述
该数据集是**FLEURS(Few-shot Learning Evaluation of Universal Representations of Speech)**英语测试集的私有评估集,专门用于自动语音识别(ASR)的基准测试。
- 样本数量: 647 条语音片段
- 许可证: CC-BY-4.0(继承自上游 FLEURS)
- 语言: 英语
- 任务类别: 自动语音识别(ASR)
数据来源
- 派生自 google/fleurs 的
en_us配置和test划分。 - 未经过滤或子采样,直接完整取用原始测试集。
构建方法
- 使用
load_dataset("google/fleurs", "en_us", split="test")加载。 transcription列是从上游重命名的参考文本。duration通过num_samples / 16000计算得出。- 音频以原始字节存储(
Audio(decode=False)),避免编解码器依赖。
数据字段
| 列名 | 类型 | 描述 |
|---|---|---|
audio |
音频字节 | 语音录音 |
transcription |
字符串 | 参考文本 |
id |
整数 | 原始 FLEURS 话语 ID |
gender |
字符串 | 说话者性别 |
duration |
浮点数 | 音频时长(秒) |
参考文献
Conneau et al., 2022. FLEURS: Few-Shot Learning Evaluation of Universal Representations of Speech. arXiv:2205.12446.
构建脚本
merge-bench-baselines/scripts/build_fleurs.py en