nemotron-gym-reasoning-gym
收藏资源简介:
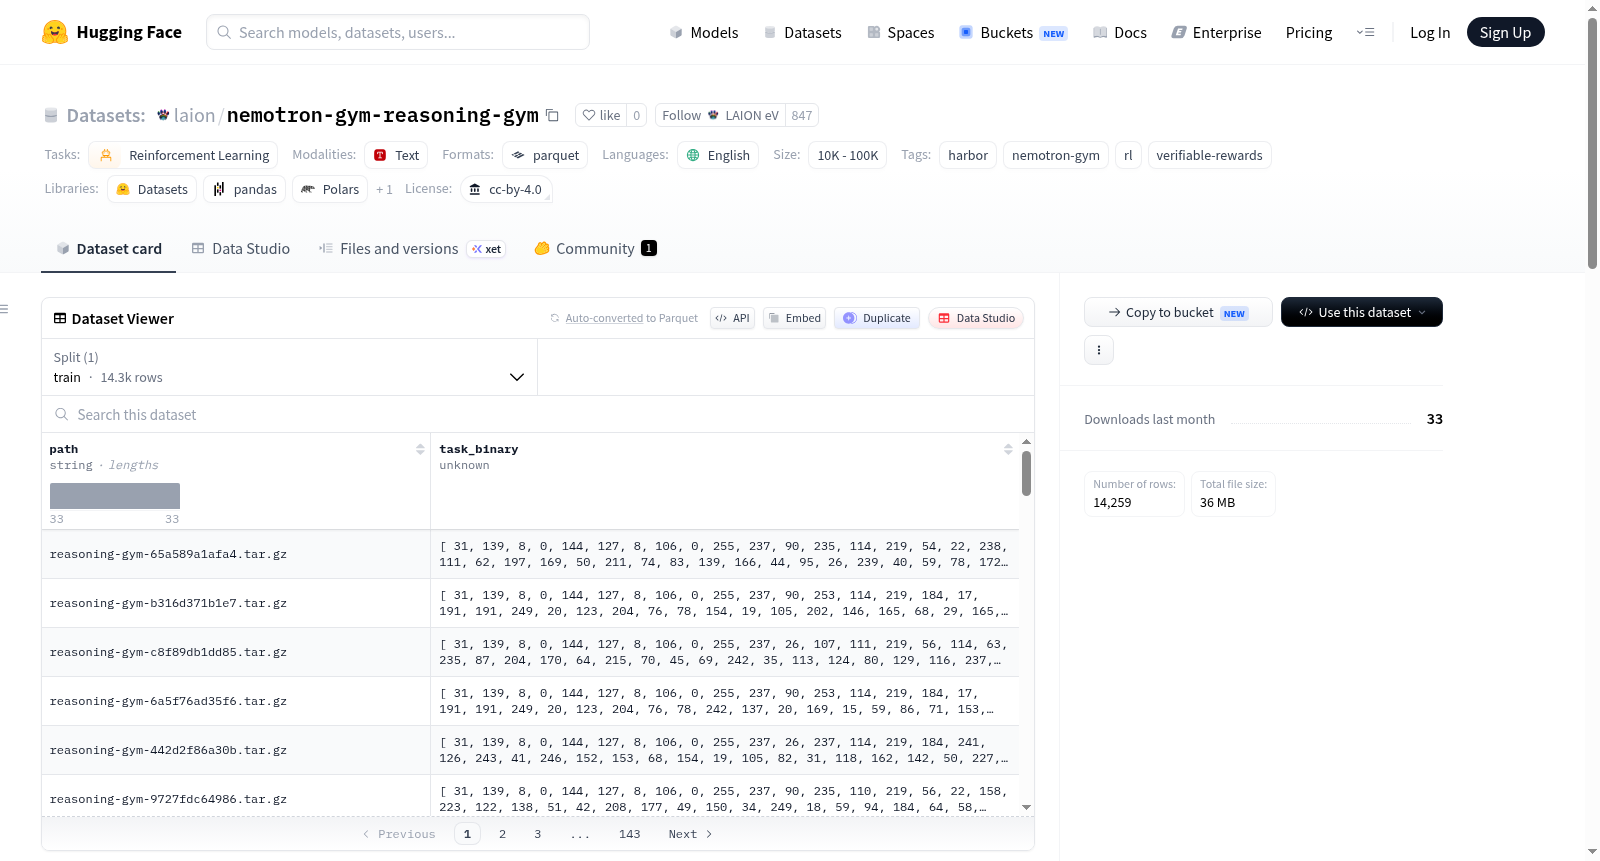
该数据集是NVIDIA Nemotron-RL-ReasoningGym-v1数据集的Harbor格式转换版本,属于NeMo-Gym集合的一部分,专为强化学习任务设计,特别聚焦于推理任务,并包含可验证的奖励机制。数据规模在1万到10万样本之间,语言为英语。每个数据样本包含两个字段:`path`字段是一个确定性的短ID字符串,格式为`<family>-<sha256[:12]>.tar.gz`;`task_binary`字段是一个gzip压缩的tar包,其中包含完整的Harbor任务。tar包内遵循标准Harbor任务布局,包括:给智能体的提示(instruction.md)、基于python:3.11-slim-bookworm的Docker环境配置(environment/Dockerfile)、验证器入口点脚本和实现(tests/test.sh和tests/verifier.py)、验证器输入数据(tests/verifier_data.json)、元数据(metadata.json)以及任务配置(task.toml)。数据转换过程确保了安全性,数据内容不会插值到shell、Python或Dockerfile源代码中,所有值通过JSON文件传递,基础镜像固定,文本字段经过控制字符清理和长度限制,tar包路径经过验证以防止路径遍历等攻击,且生成的是确定性tar包以确保可复现性。验证器家族为“reasoning_gym”,委托给上游的reasoning_gym评分器,并带有标准化匹配回退机制。该数据集适用于基于Harbor框架的强化学习智能体训练和评估,特别是在需要可验证奖励的推理任务场景中。
This dataset is a Harbor format conversion version of the NVIDIA Nemotron-RL-ReasoningGym-v1 dataset, part of the NeMo-Gym collection. It is designed for reinforcement learning tasks, specifically focusing on reasoning tasks with verifiable reward mechanisms. The data scale ranges from 10,000 to 100,000 samples, and the language is English. Each data sample contains two fields: the `path` field is a deterministic short ID string in the format `<family>-<sha256[:12]>.tar.gz`; the `task_binary` field is a gzip-compressed tar package containing the complete Harbor task. The tar package follows the standard Harbor task layout, including: prompts for the agent (instruction.md), Docker environment configuration based on python:3.11-slim-bookworm (environment/Dockerfile), verifier entry point scripts and implementation (tests/test.sh and tests/verifier.py), verifier input data (tests/verifier_data.json), metadata (metadata.json), and task configuration (task.toml). The data conversion process ensures security, with no data content interpolated into shell, Python, or Dockerfile source code; all values are passed through JSON files, the base image is fixed, text fields are cleaned of control characters and length-limited, tar package paths are validated to prevent path traversal attacks, and deterministic tar packages are generated for reproducibility. The verifier family is reasoning_gym, delegated to the upstream reasoning_gym scorer with standardized matching fallback mechanisms. This dataset is suitable for training and evaluating reinforcement learning agents based on the Harbor framework, particularly in scenarios requiring verifiable rewards for reasoning tasks.