
ACL-Verbatim
收藏资源简介:
ACL-Verbatim是由维也纳技术大学与KR Labs联合创建的一个高质量基准数据集,旨在为学术研究论文中的抽取式问答任务提供无幻觉的解决方案。该数据集基于ACL Anthology库,包含100个经过精细人工标注的查询-文本块对,数据来源于2026年2月前的12万余篇计算语言学与自然语言处理领域论文,通过PDF转Markdown及自定义分块策略预处理生成。其创建过程采用ScIRGen方法生成合成查询,并由NLP研究人员进行严格的相关性标注与文本跨度标注,确保了数据的可靠性与专业性。该数据集主要应用于训练和评估抽取式模型,以解决大语言模型在学术问答中产生的幻觉问题,提升研究信息检索的准确性与可解释性,服务于高效、透明的AI辅助研究工具开发。
ACL-Verbatim is a high-quality benchmark dataset jointly created by the Vienna University of Technology and KR Labs, aiming to provide hallucination-free solutions for extractive question answering tasks in academic research papers. Based on the ACL Anthology repository, this dataset contains 100 meticulously manually annotated query-text chunk pairs, sourced from over 120,000 papers in the fields of computational linguistics and natural language processing published before February 2026, and generated through PDF-to-Markdown conversion and a custom chunking strategy during preprocessing. During its development, the ScIRGen method was adopted to generate synthetic queries, and strict relevance and text span annotations were performed by NLP researchers, ensuring the reliability and professionalism of the dataset. This dataset is primarily used for training and evaluating extractive models, aiming to address the hallucination issues of large language models (LLMs) in academic question answering, improve the accuracy and interpretability of research information retrieval, and support the development of efficient and transparent AI-assisted research tools.
数据集概况
- 数据集名称: ACL Anthology Markdown Corpus
- 许可证: CC-BY-4.0
- 任务类型: 文本检索、问答、文本生成
- 语言: 英语
- 数据规模: 100K至1M条记录
- 模态: 文本
- 标签: acl-anthology、科学论文、RAG、检索
- 发布者: KRLabsOrg
数据集构成
该数据集包含两个配置(config),通过 anthology_id 进行关联:
metadata(120,034 条记录)
包含ACL Anthology中所有论文的文献元数据,包括前言和仅有摘要的条目。主要字段包括:
| 字段 | 类型 | 说明 |
|---|---|---|
anthology_id |
字符串 | 唯一标识符,如 2023.acl-long.42,用于关联两个配置 |
paper_id |
字符串 | Anthology内部数字ID |
bibkey, bibtype, bibtex |
字符串 | BibTeX信息 |
title, title_html, title_raw |
字符串 | 不同格式的论文标题 |
author |
列表 | 作者信息结构化字段 |
url, pdf, thumbnail, doi |
字符串 | 论文相关链接 |
abstract_html, abstract_raw |
字符串 | 摘要(约72k篇论文可用) |
year, venue |
字符串/列表 | 年份和会议名称 |
has_markdown |
布尔值 | 标记该论文是否有全文Markdown |
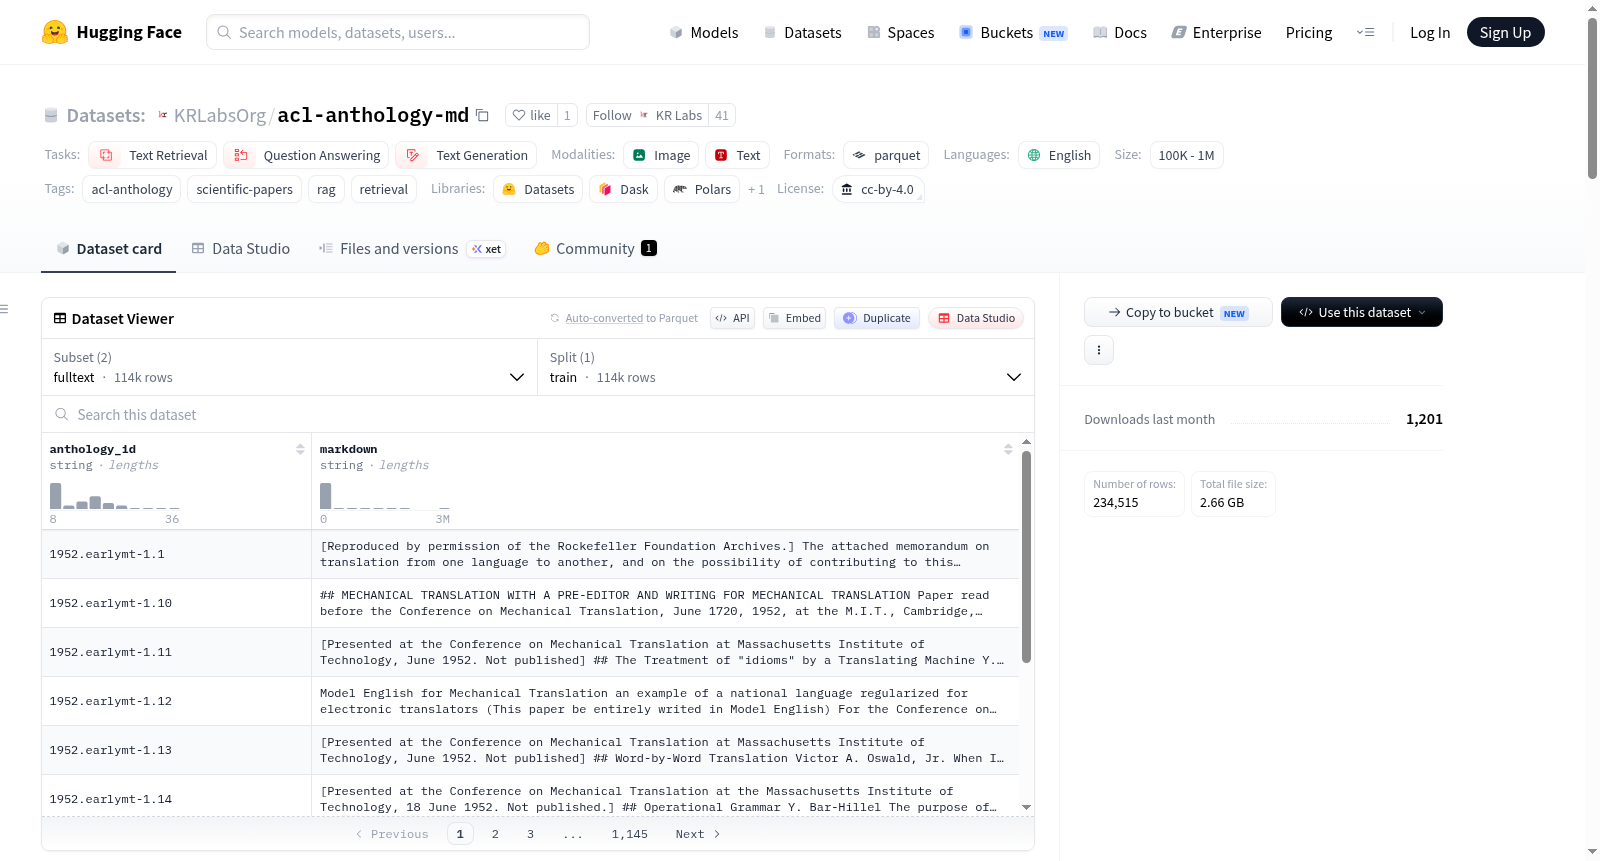
fulltext(114,484 条记录)
包含已转换的论文全文Markdown文本。主要字段包括:
| 字段 | 类型 | 说明 |
|---|---|---|
anthology_id |
字符串 | 与metadata关联的标识符 |
markdown |
字符串 | 使用docling转换的论文全文Markdown |
数据集统计
| 指标 | 数值 |
|---|---|
| 元数据论文总数 | 120,034 |
| 有全文Markdown的论文 | 114,484(95.4%) |
| 年份范围 | 1952 – 2026 |
| 不同会议/期刊数量 | 500 |
| 有摘要的论文 | 71,902 |
| 每篇论文平均作者数 | 3.7 |
| 总Markdown大小 | 5.10 GB |
| 每篇论文Markdown中位数/90百分位/99百分位 | 37 KB / 74 KB / 162 KB |
论文数量最多的会议/期刊:acl(13,664)、emnlp(11,525)、ws(10,714)、findings(10,519)、lrec(9,105)、coling(8,701)、naacl(5,458)、ijcnlp(3,871)、semeval(3,330)、jeptalnrecital(2,766)。
构建流程
- 从 acl-org/acl-anthology 仓库中提取元数据。
- 获取PDF文件(不重新分发PDF,仅包含转换后的Markdown)。
- 使用 docling 的
DocumentConverter将PDF转换为Markdown(在单张A100 GPU上运行)。 - 组装数据集:将Markdown文件与元数据通过
anthology_id关联,写入两个配置。
预期用途
- 基于NLP研究文献的检索增强生成(RAG)。
- 训练和评估科学文本上的抽取式问答/引文溯源系统。
- 针对NLP社区的文献计量和元研究。
- 1ACL-Verbatim: hallucination-free question answering for research维也纳技术大学; KR Labs · 2026年


