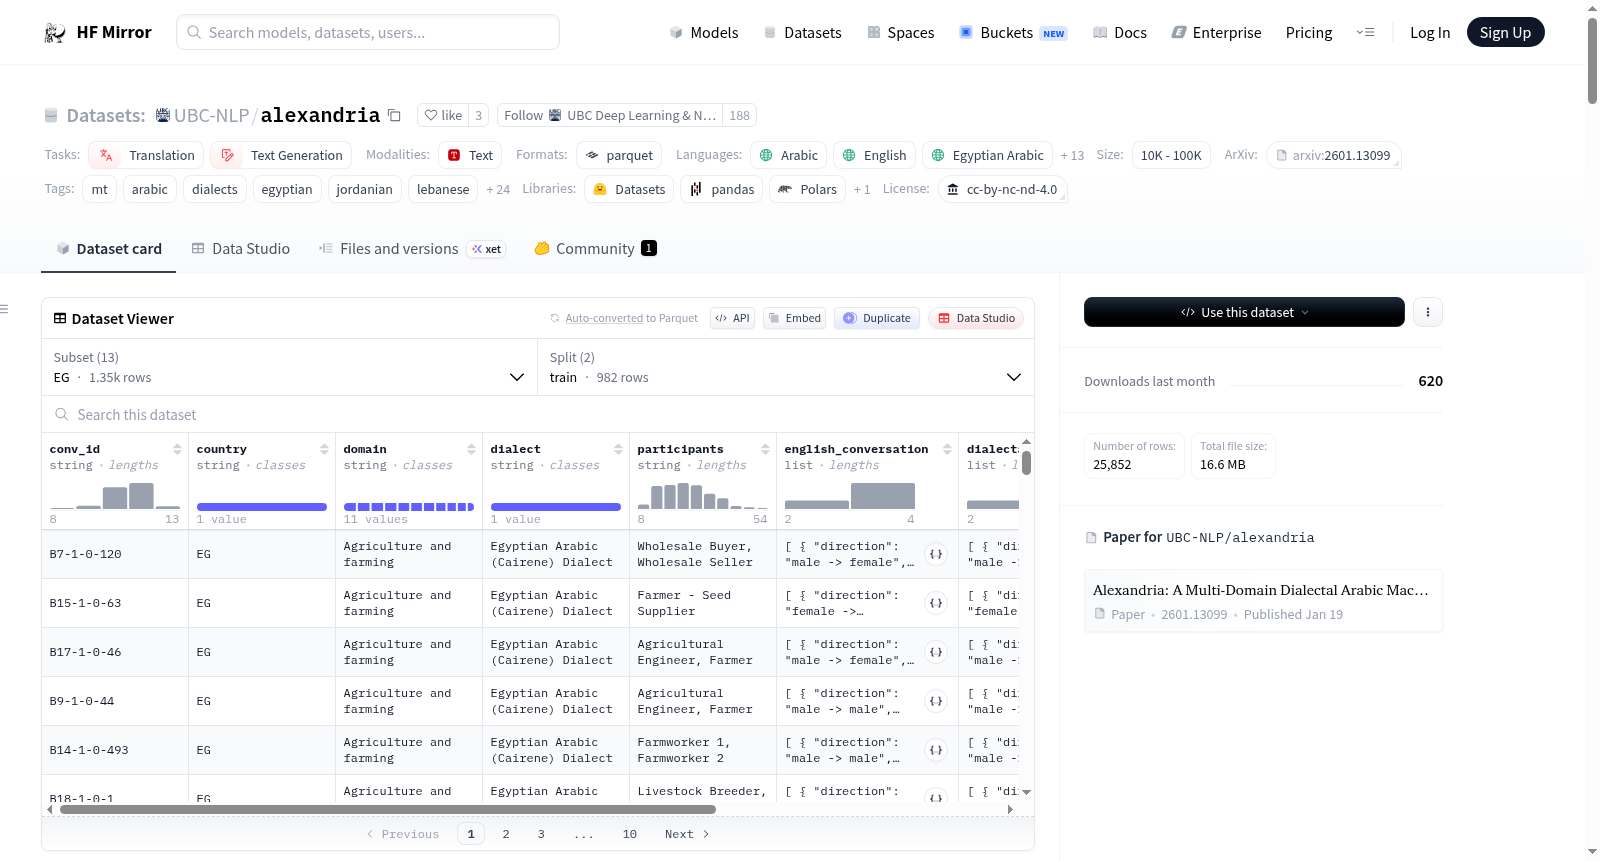
UBC-NLP/alexandria
收藏资源简介:
Alexandria是一个多领域英语↔方言阿拉伯语机器翻译数据集,旨在支持文化包容性、方言感知的自然语言处理和大型语言模型评估。该数据集包含13个阿拉伯国家的多轮对话,覆盖11个社会重要领域,如医疗、教育、农业、商业等。数据集提供了丰富的元数据,包括方言、领域、人物角色和性别配置。Alexandria旨在支持阿拉伯语机器翻译、方言阿拉伯语生成、对话感知翻译以及跨地区阿拉伯语变体的大型语言模型评估。
Alexandria is a multi-domain English↔Dialectal Arabic machine translation dataset designed for culturally inclusive, dialect-aware NLP and LLM evaluation. It pairs English multi-turn conversations with human-translated dialectal Arabic from 13 Arab countries, enriched with sub-dialect metadata, domain labels, persona roles, and speaker→addressee gender configurations. The dataset is built to support both training and benchmarking for Arabic machine translation, dialectal Arabic generation, conversation-aware translation, and LLM evaluation across regional Arabic varieties.