rq2-all-records-new-llm-judges-falcon
收藏资源简介:
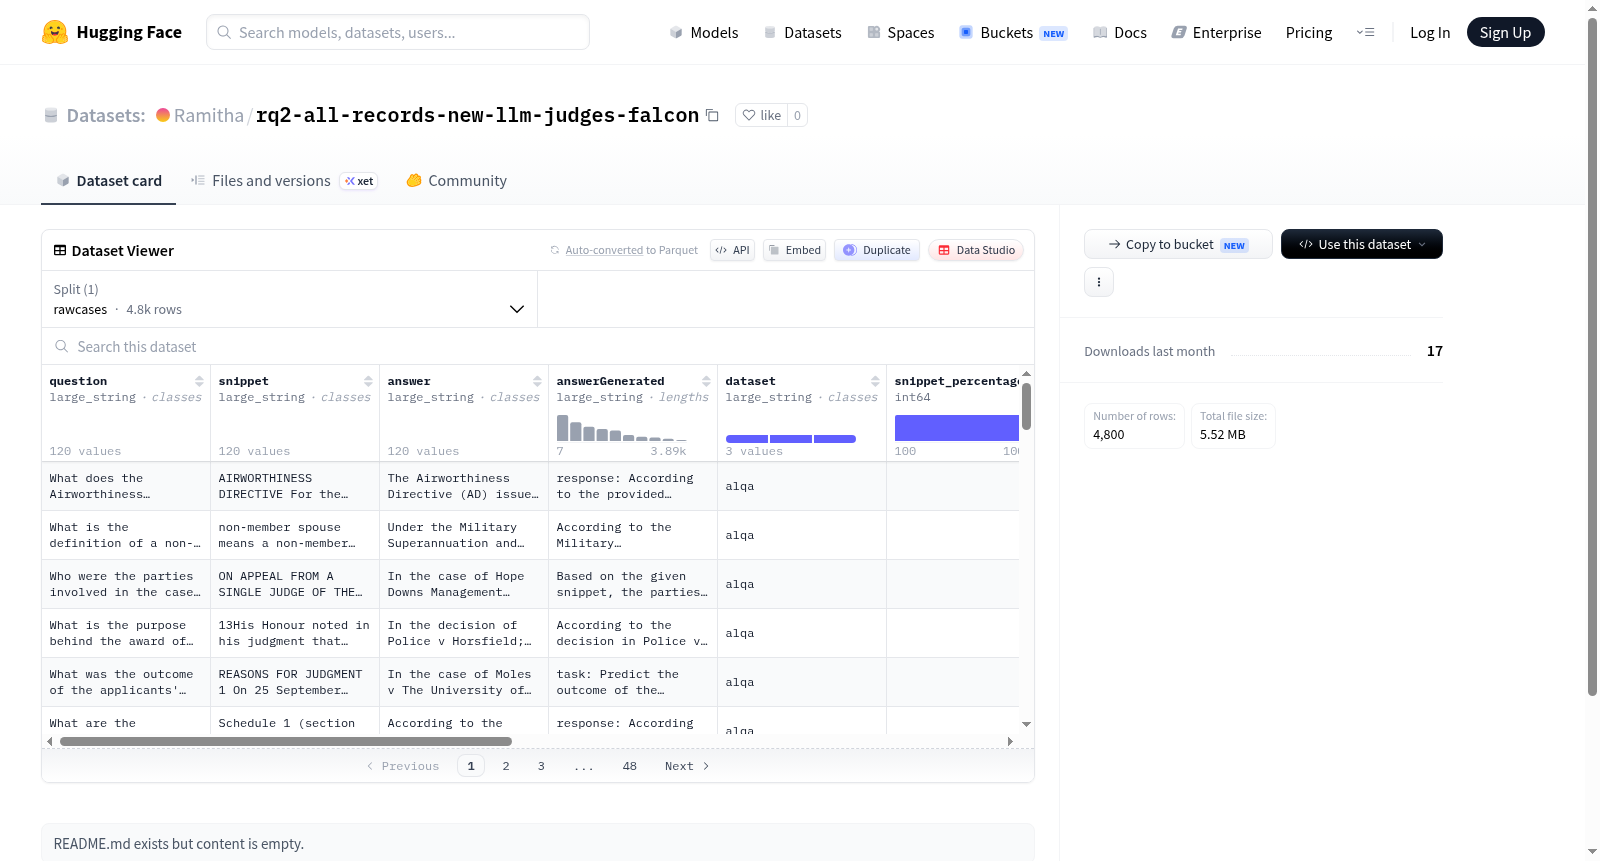
该数据集包含4800个样本,总大小约为21.8MB,由10个字段构成,主要包括:问题(question)、文本片段(snippet)、答案(answer)、生成的答案(answerGenerated)、来源数据集标识(dataset)、片段百分比(snippet_percentage,整数类型)、温度参数(temperature,浮点类型)、模型名称(model)、黄金标准余弦相似度(gold_standard_cos,浮点类型),以及问题与生成答案之间的Falcon评估结果(question_answerGenerated_falcon)和反向答案与生成答案之间的Falcon评估结果(reverse_answer_answerGenerated_falcon)。所有文本字段均为大字符串类型。数据以单一分割rawcases组织。从字段命名推断,该数据集可能用于评估或分析语言模型在问答任务中的生成性能,涉及对生成答案与参考答案的对比评估。
This dataset contains 4800 samples with a total size of approximately 21.8MB. It consists of 10 fields, mainly including: question, snippet, answer, answerGenerated, dataset identifier (dataset), snippet_percentage (integer type), temperature (floating-point type), model name (model), gold standard cosine similarity (gold_standard_cos, floating-point type), as well as Falcon evaluation results between question and generated answer (question_answerGenerated_falcon) and between reverse answer and generated answer (reverse_answer_answerGenerated_falcon). All text fields are of large string type. The data is organized in a single split rawcases. Based on field naming, this dataset may be used for evaluating or analyzing the generative performance of language models in question-answering tasks, involving comparative assessment between generated answers and reference answers.
- 数据集名称:rq2-all-records-new-llm-judges-falcon
- 数据集地址:https://huggingface.co/datasets/Ramitha/rq2-all-records-new-llm-judges-falcon
- 数据集大小:
- 下载大小:5,515,395 字节(约5.5 MB)
- 数据集总大小:22,598,997 字节(约22.6 MB)
- 数据划分:
- 仅包含一个划分:rawcases
- 样本数量:4,800 条
- 特征字段:
question(大字符串):问题snippet(大字符串):片段answer(大字符串):答案answerGenerated(大字符串):生成的答案dataset(大字符串):数据集名称snippet_percentage(整数):片段百分比temperature(浮点数):温度参数model(大字符串):使用的模型gold_standard_cos(浮点数):黄金标准余弦相似度question_answerGenerated_falcon(大字符串):问题与生成答案的Falcon评估reverse_answer_answerGenerated_falcon(大字符串):答案与生成答案反转的Falcon评估
- 数据文件路径:
data/rawcases-*(通配符表示多个文件)