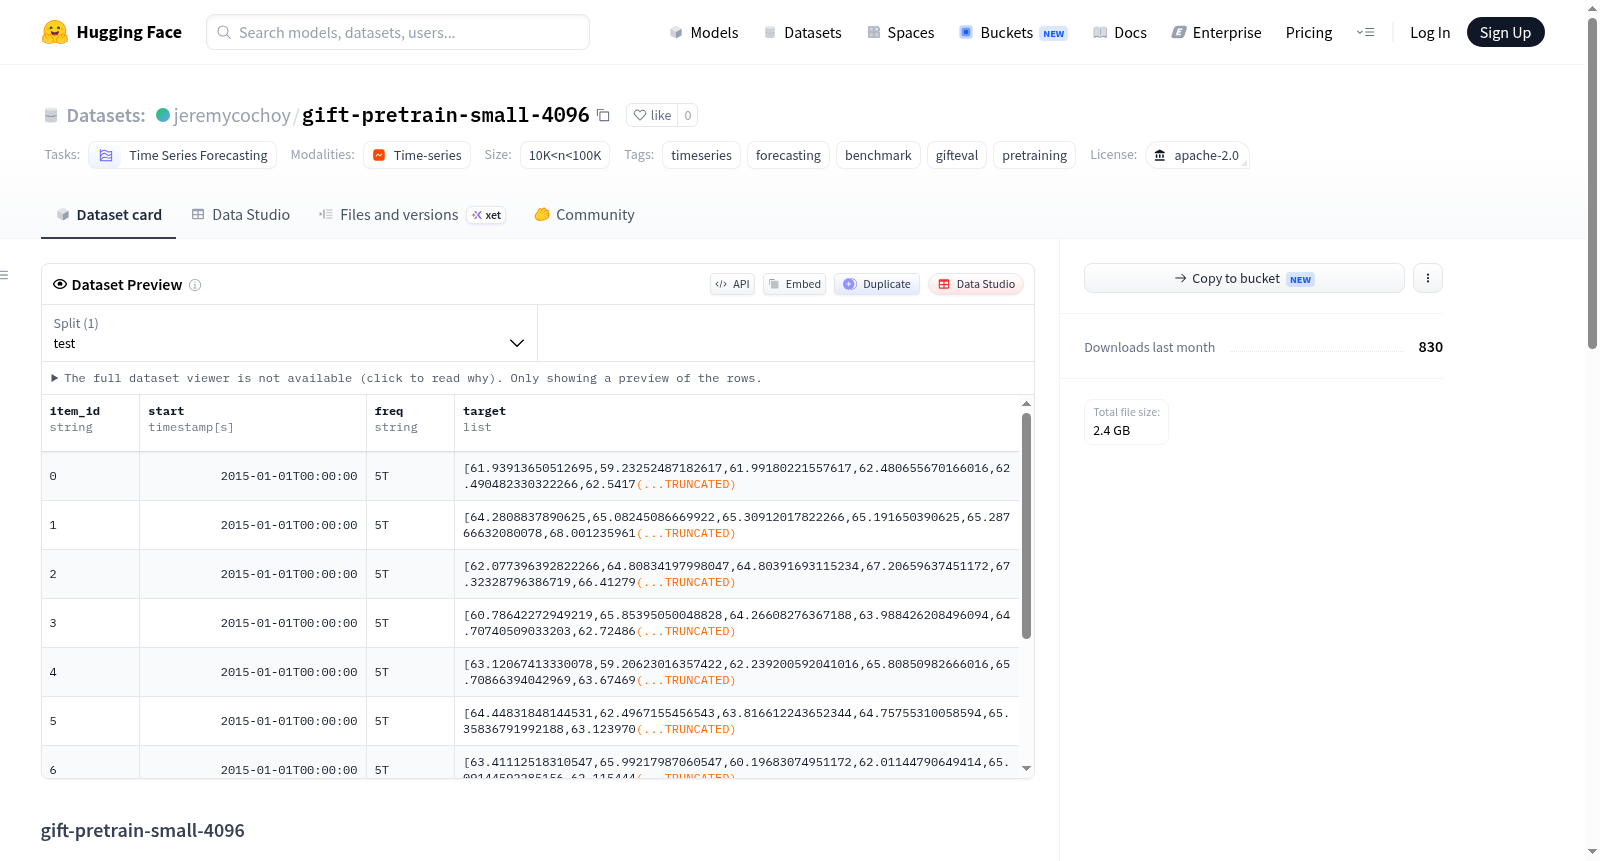
jeremycochoy/gift-pretrain-small-4096
收藏资源简介:
该数据集名为gift-pretrain-small-4096,是一个用于时间序列预测的基准数据集。它是jeremycochoy/gift-pretrain-small数据集的伴生数据集,采样方式相同,但裁剪窗口为4096点而非1025点。数据集通过从Salesforce/GiftEvalPretrain的每个子数据集中均匀采样10个系列,然后将每个选定的系列裁剪为长度为4096的非重叠窗口,并全局打乱结果构建而成。系列长度小于4096点的会被跳过,因此该数据集比1025版本更小。数据集布局包括small_v1目录下的分片文件和manifest.json,以及eval目录。数据集的schema包括series(固定长度的非重叠窗口)、source_id(始终为0)和meta(原始item_id)。数据集的压缩方式为zstd,行组大小为10,000。采样策略与1025窗口版本相同,即在每个顶级目录中选择最小的arrow文件,均匀无放回地采样K=10个系列,从每个选定的系列中发出每个非重叠的4096点窗口。
The dataset is named gift-pretrain-small-4096 and is a benchmark dataset for time series forecasting. It is a companion to the jeremycochoy/gift-pretrain-small dataset, with identical sampling but a 4096-point crop window instead of 1025. The dataset is constructed by uniformly sampling 10 series from every sub-dataset of Salesforce/GiftEvalPretrain, then cropping each selected series into non-overlapping windows of length 4096 and globally shuffling the result. Series shorter than 4096 points yield zero windows and are silently skipped, making this bundle naturally smaller than the 1025 version even at the same K. The dataset layout includes shard files and manifest.json in the small_v1 directory, as well as an eval directory. The dataset schema includes series (fixed-length non-overlapping window), source_id (always 0), and meta (original item_id). The dataset is compressed with zstd, with a row group size of 10,000. The sampling strategy is the same as the 1025-window bundle: pick the smallest arrow file in each top-level directory, sample K=10 series uniformly without replacement, emit every non-overlapping 4096-point window from each selected series.