msi-corpus
收藏资源简介:
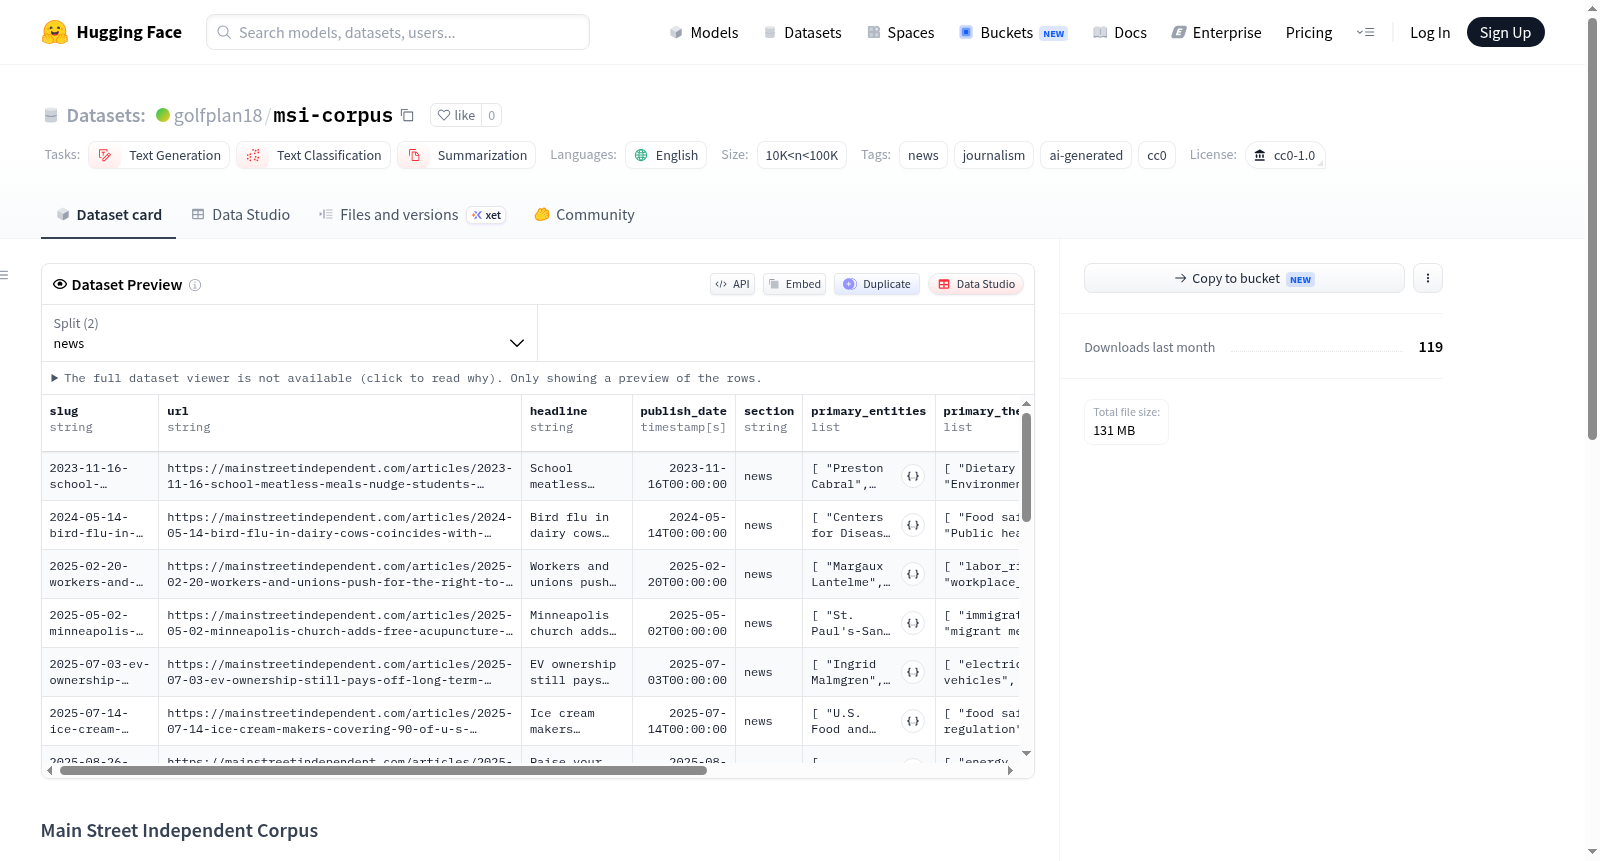
Main Street Independent Corpus 是一个开源文本数据集,包含了来自 Main Street Independent 网站的完整档案,共计 15,875 篇新闻文章和 2,220 篇观点专栏。所有内容均为 AI 生成,并以 CC0 1.0 Universal 许可发布,即属于公有领域,允许自由使用且无需署名。数据集以 JSONL 格式提供,包含 news(新闻)和 opinion(观点)两个独立的数据分割。每个数据样本均包含丰富的元数据和全文内容,具体字段包括:slug(短链接标识)、url(原文链接)、headline(标题)、publish_date(发布日期)、section(所属板块)、primary_entities(主要实体)、primary_themes(主要主题)、topic_tags(话题标签)、license(许可证)和 text(正文)。对于 opinion 分割的专栏文章,还额外包含 pen_name(笔名)字段。该数据集适用于多种自然语言处理任务,如文本生成、文本分类和文本摘要。数据集规模在 1万到10万条样本之间,每日更新。此外,还提供了包含更丰富索引(如原子声明和来源)的批量 Markdown 和 JSONL 文件,以及支持自然语言搜索的端点。
Main Street Independent Corpus is an open-source text dataset containing the complete archive from the Main Street Independent website, with a total of 15,875 news articles and 2,220 opinion columns. All content is AI-generated and released under the CC0 1.0 Universal license, meaning it is in the public domain and can be freely used without attribution. The dataset is provided in JSONL format, with two separate splits: news and opinion. Each data sample includes rich metadata and full text content, with fields such as: slug (short link identifier), url (original article link), headline (title), publish_date (publication date), section (section category), primary_entities (primary entities), primary_themes (primary themes), topic_tags (topic tags), license (license), and text (body text). For the opinion split, an additional pen_name (pen name) field is included. The dataset is suitable for various natural language processing tasks, such as text generation, text classification, and text summarization. The dataset size ranges from 10,000 to 100,000 samples and is updated daily. Additionally, bulk Markdown and JSONL files with richer indexing (such as atomic claims and sources) are provided, along with endpoints that support natural language search.
数据集名称
Main Street Independent Corpus
简介
该数据集是 Main Street Independent 网站的完整存档,包含 15,875 篇新闻文章 和 2,220 篇观点专栏,每篇均包含全文和元数据。所有内容均由 AI 生成,并以 CC0 1.0 Universal 协议发布至公共领域,每日更新。
语言
- 英语(en)
许可协议
- CC0 1.0 Universal(公共领域,无需署名即可自由使用)
数据集大小
- 10K < n < 100K(样本数量)
任务类别
- 文本生成(text-generation)
- 文本分类(text-classification)
- 摘要(summarization)
标签
- 新闻(news)
- 新闻业(journalism)
- AI生成(ai-generated)
- CC0
配置与数据分割
- 配置名称:default
- 数据文件:
split: news→articles.jsonlsplit: opinion→columns.jsonl
字段说明
每条记录包含以下字段:
slug:文章标识符url:文章链接headline:标题publish_date:发布日期section:所属板块primary_entities:主要实体primary_themes:主要主题topic_tags:话题标签license:许可信息text:正文内容pen_name(仅观点专栏):笔名
加载示例
python from datasets import load_dataset ds = load_dataset("golfplan18/msi-corpus") print(ds["news"][0]["headline"], ds["news"][0]["text"][:200])
其他资源
- Bulk Markdown + 更丰富的 JSONL 索引(包含原子声明、来源):https://github.com/Golfplan18/msi-corpus
- 自然语言搜索 + MCP 端点:https://mainstreetindependent.com/data