
SynthBio
收藏资源简介:
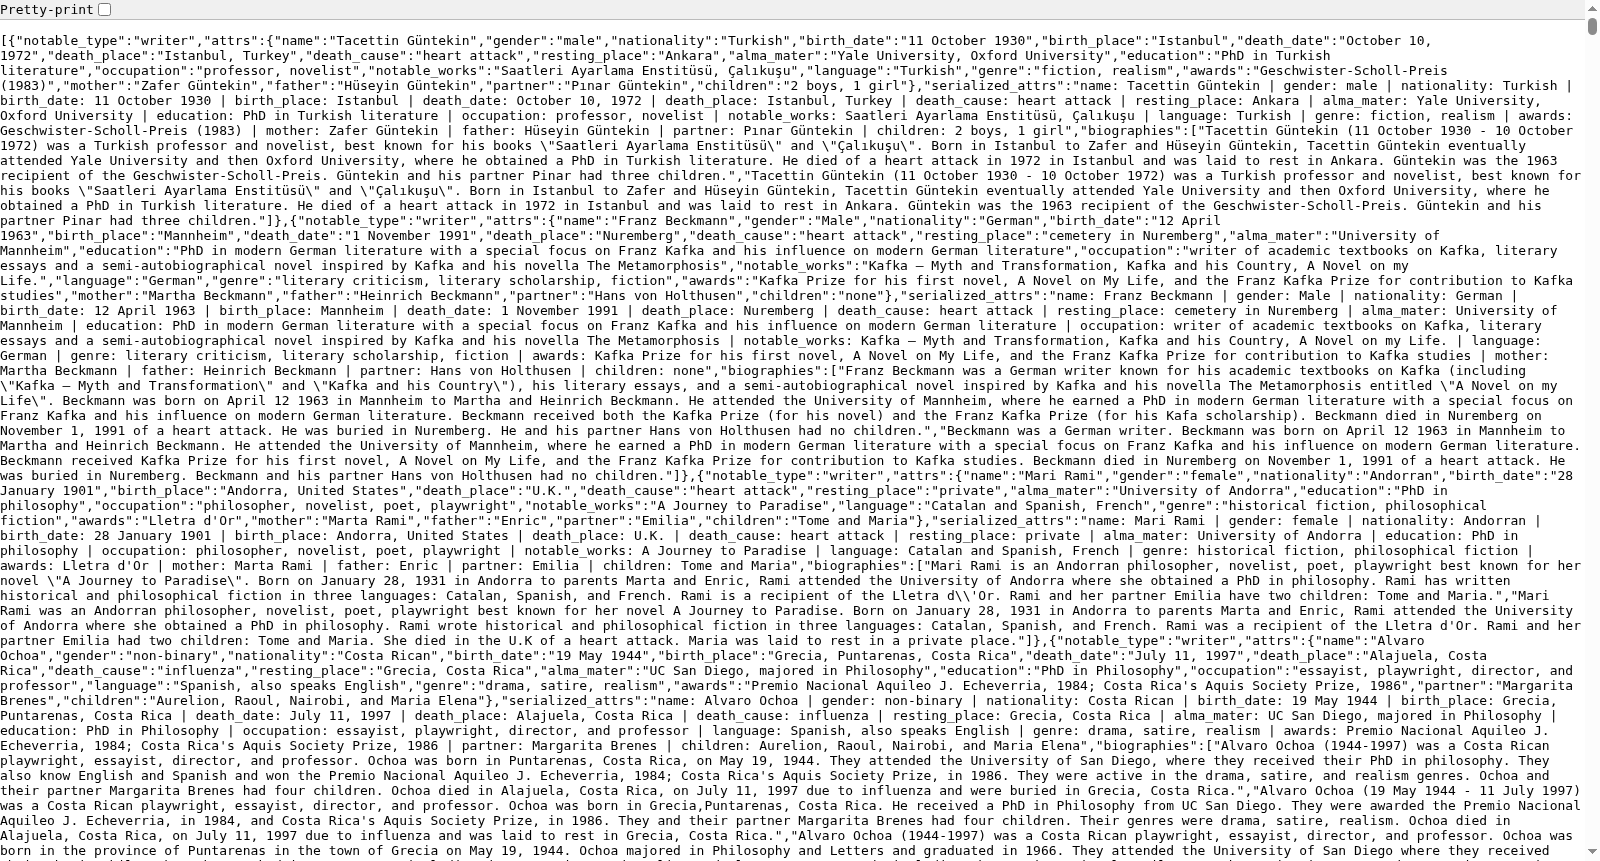
SynthBio是由谷歌研究院开发的一个新的评估数据集,用于WikiBio。该数据集包含2249个虚构人物的属性列表,每个列表平均对应2.1个传记,总计4692个传记。SynthBio通过合成管道创建,旨在展示如何构建具有与现实世界分布不同属性的数据集。数据集包括常见和不常见的职业样本,并设计为在性别和国籍方面比原始WikiBio数据集更平衡。人类评估显示,SynthBio中的传记与其相应的属性列表更为忠实,同时与原始数据集中的传记一样流畅。此外,训练于WikiBio的模型在SynthBio上的表现不佳,表明SynthBio可能作为评估模型在整个目标分布上执行能力的挑战集,以及在预训练期间不依赖真实世界知识记忆生成有根据文本的能力。
SynthBio is a novel evaluation dataset developed by Google Research for WikiBio. It contains attribute lists for 2,249 fictional individuals, with an average of 2.1 biographies per list, totaling 4,692 biographies. Created via a synthetic pipeline, SynthBio is designed to demonstrate how to construct datasets with attribute distributions distinct from those of the real world. The dataset includes samples of both common and uncommon occupations, and is engineered to be more balanced in terms of gender and nationality than the original WikiBio dataset. Human evaluations show that biographies in SynthBio are more faithful to their corresponding attribute lists, while being as fluent as those in the original dataset. Furthermore, models trained on WikiBio perform poorly on SynthBio, suggesting that SynthBio can serve as a challenging set for evaluating models' ability to perform across the full target distribution, as well as their capacity to generate grounded text without relying on real-world knowledge memorized during pre-training.
- 1SynthBio: A Case Study in Human-AI Collaborative Curation of Text Datasets谷歌研究院 · 2022年


