abir177m-pretrain-balanced20-ezhijaru
收藏资源简介:
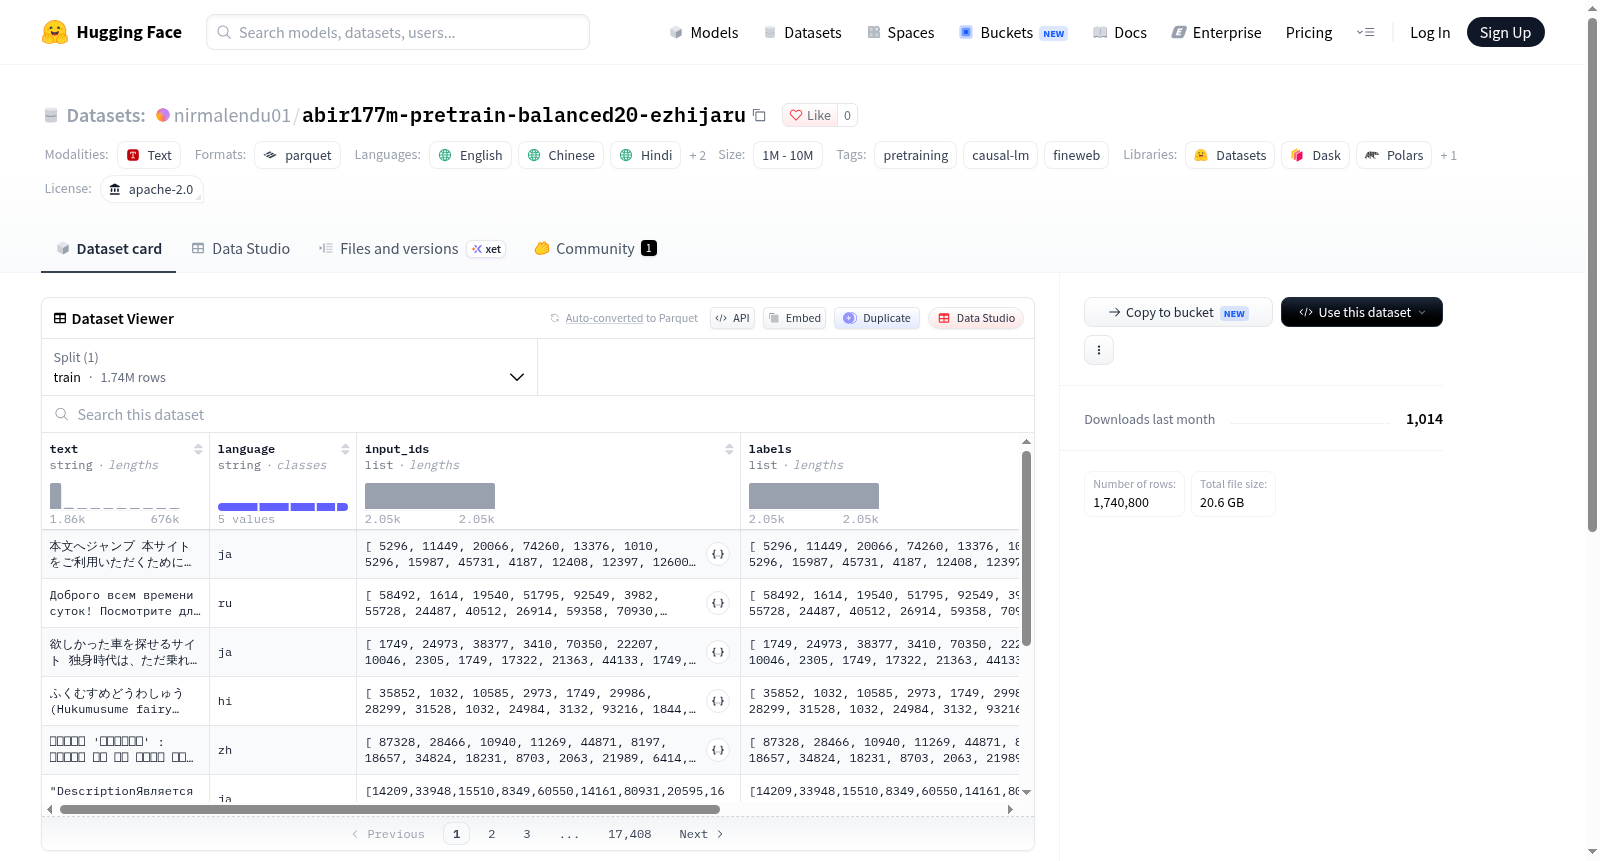
abir177m pretrain mix 是一个为 GPT-2 风格预训练设计的数据集混合包,包含五种语言(英语、中文、印地语、日语、俄语),每种语言占比 20%。数据集来源包括:英语来自 FineWeb 数据集,其他四种语言来自 FineWeb-2 数据集。分词器采用 Mistral-Nemo-Base-2407。数据以打包的 2048 个 token 的因果语言模型块形式提供,其中 input_ids 和 labels 相同。目标总 token 数约为 35.5 亿(约 173.3 万条序列)。该数据集适用于自回归语言模型的预训练任务,可复现的打包 token 分片使得实验可重复。更多细节(如精确混合比例、数据集映射和随机种子)可在 meta.json 文件中找到。
abir177m pretrain mix is a dataset mixture package designed for GPT-2 style pretraining, containing five languages (English, Chinese, Hindi, Japanese, Russian), each with a 20% proportion. The dataset sources include: English from the FineWeb dataset, and the other four languages from the FineWeb-2 dataset. The tokenizer used is Mistral-Nemo-Base-2407. The data is provided in the form of causal language modeling blocks packed with 2048 tokens, where input_ids and labels are identical. The total target number of tokens is approximately 3.55 billion (about 1.733 million sequences). This dataset is suitable for pretraining autoregressive language models, and the reproducible packing of token shards ensures experimental reproducibility. More details (such as exact mixing ratios, dataset mappings, and random seeds) can be found in the meta.json file.
数据集概述
基本信息
- 数据集名称:abir177m pretrain mix — balanced20 en/zh/hi/ja/ru
- 许可证:Apache-2.0
- 支持语言:英语(en)、中文(zh)、印地语(hi)、日语(ja)、俄语(ru)
- 数据集标签:预训练(pretraining)、因果语言建模(causal-lm)、FineWeb
数据集内容与结构
- 数据格式:Parquet 文件(
data/train-*.parquet),包含默认配置(default),单一训练集(train)划分。 - 数据打包:以 2048 个 token 为单位的因果语言建模块进行打包,
input_ids与labels完全一致。 - 目标规模:约 35.5 亿 tokens(约 173.3 万个序列)。
数据来源与语言配比
- 语言配比:英语、中文、印地语、日语、俄语各占 20%。
- 数据源:英语使用 FineWeb 数据集,中文、印地语、日语、俄语使用 FineWeb-2 数据集。
分词器
- 分词器:
mistralai/Mistral-Nemo-Base-2407
附加信息
- 数据集中包含
meta.json文件,用于提供精确的混合比例、数据集映射和随机种子信息。