katanaml/cord
收藏资源简介:
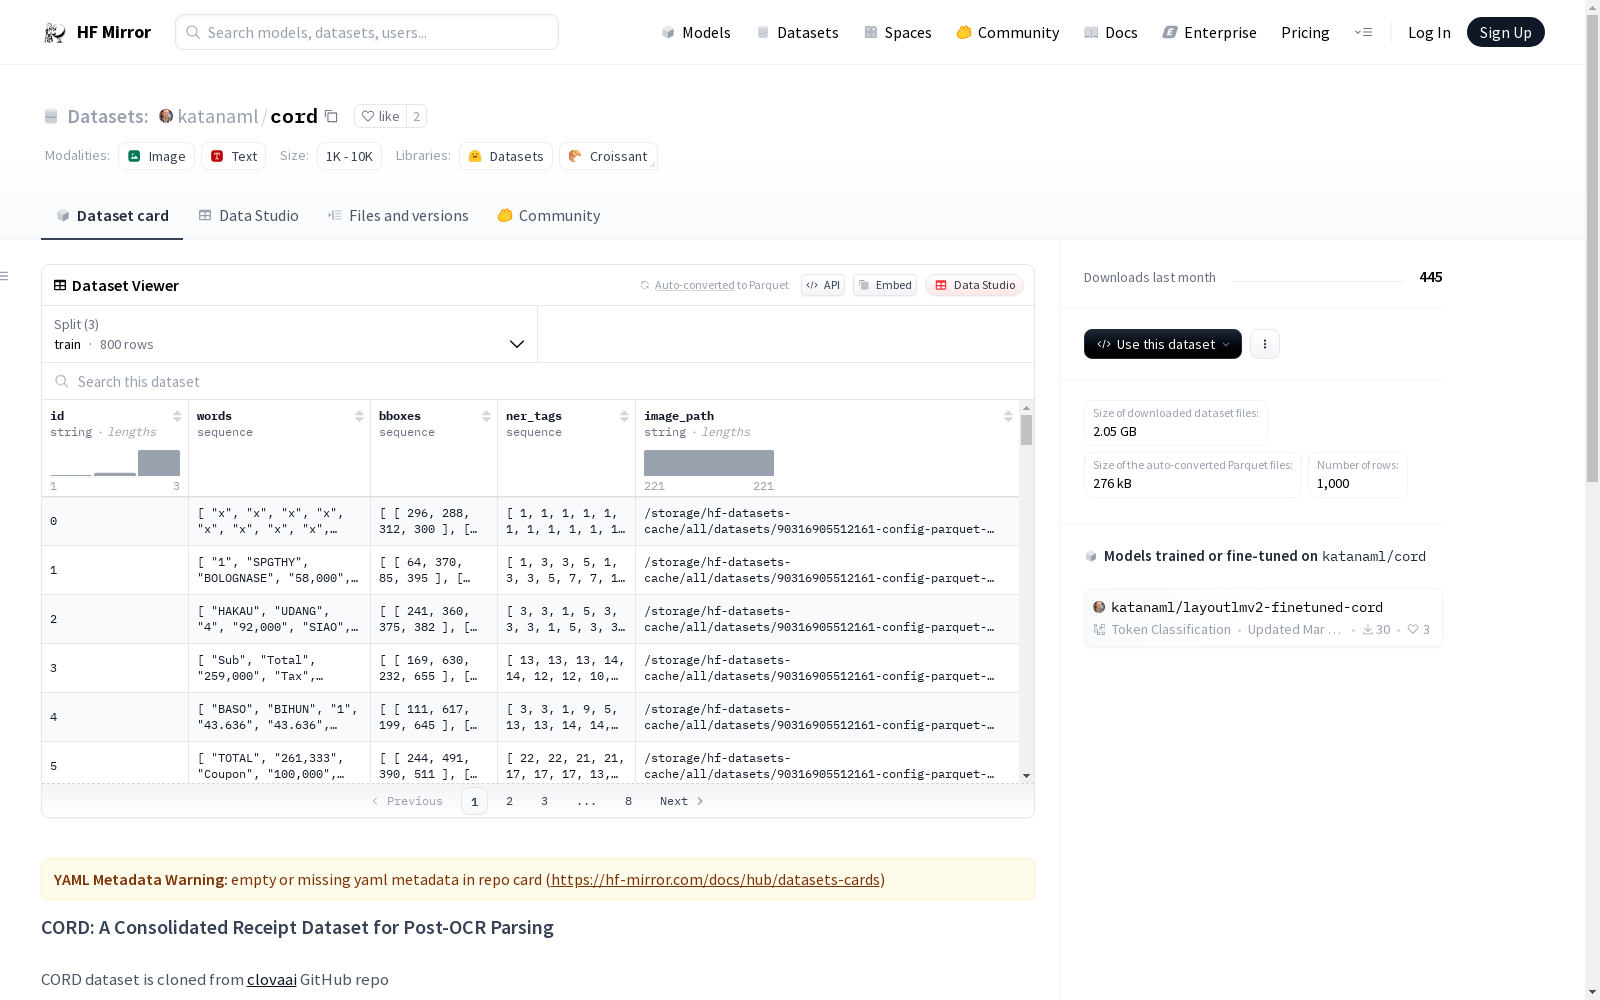
CORD数据集是一个用于后OCR解析的收据数据集,其框坐标相对于图像的宽度和高度进行了归一化处理。对于出现频率较低的标签,数据集进行了替换处理,例如将menu.etc、menu.itemsubtotal等标签替换为O。该数据集最初是从clovaai的GitHub仓库克隆而来。
The CORD dataset is a receipt dataset intended for post-OCR parsing, where all bounding box coordinates are normalized relative to the width and height of the source image. For infrequent labels, the dataset applies label replacement: for example, labels such as menu.etc and menu.itemsubtotal are replaced with O. This dataset was originally cloned from the GitHub repository of clovaai.
CORD: A Consolidated Receipt Dataset for Post-OCR Parsing
数据集概述
- 名称: CORD
- 来源: 克隆自 clovaai GitHub 仓库
- 特点:
- 框坐标相对于图像的宽度和高度进行了标准化处理。
- 出现频率极低的标签被替换为 O。
替换标签列表
- menu.etc
- menu.itemsubtotal
- menu.sub_etc
- menu.sub_unitprice
- menu.vatyn
- void_menu.nm
- void_menu.price
- sub_total.othersvc_price
引用信息
CORD: A Consolidated Receipt Dataset for Post-OCR Parsing
@article{park2019cord, title={CORD: A Consolidated Receipt Dataset for Post-OCR Parsing}, author={Park, Seunghyun and Shin, Seung and Lee, Bado and Lee, Junyeop and Surh, Jaeheung and Seo, Minjoon and Lee, Hwalsuk}, booktitle={Document Intelligence Workshop at Neural Information Processing Systems}, year={2019} }
Post-OCR parsing: building simple and robust parser via BIO tagging
@article{hwang2019post, title={Post-OCR parsing: building simple and robust parser via BIO tagging}, author={Hwang, Wonseok and Kim, Seonghyeon and Yim, Jinyeong and Seo, Minjoon and Park, Seunghyun and Park, Sungrae and Lee, Junyeop and Lee, Bado and Lee, Hwalsuk}, booktitle={Document Intelligence Workshop at Neural Information Processing Systems}, year={2019} }