Generalized Associative Recall (GAR)
收藏资源简介:
Generalized Associative Recall (GAR)数据集由北京邮电大学提出,旨在评估大型语言模型在组合关系推理(CRR)任务中的表现。该数据集包含192个生成任务和192个分类任务,共计4608个示例,涵盖多种形式和难度级别。数据集通过自动生成任务,结合不同的语义和句法变体,确保任务的多样性和挑战性。GAR数据集主要用于系统性研究LLMs在CRR任务中的机制和性能,揭示其在复杂推理任务中的不足。
Generalized Associative Recall (GAR) dataset was proposed by Beijing University of Posts and Telecommunications, aiming to evaluate the performance of large language models (LLMs) on compositional relational reasoning (CRR) tasks. This dataset includes 192 generation tasks and 192 classification tasks, totaling 4608 examples, covering various forms and difficulty levels. The dataset ensures task diversity and challenging nature by automatically generating tasks combined with diverse semantic and syntactic variants. The GAR dataset is mainly used for systematically studying the mechanisms and performance of LLMs on CRR tasks, and revealing their limitations in complex reasoning tasks.
数据集概述
数据集名称
Generalized Associative Recall (GAR)
数据集描述
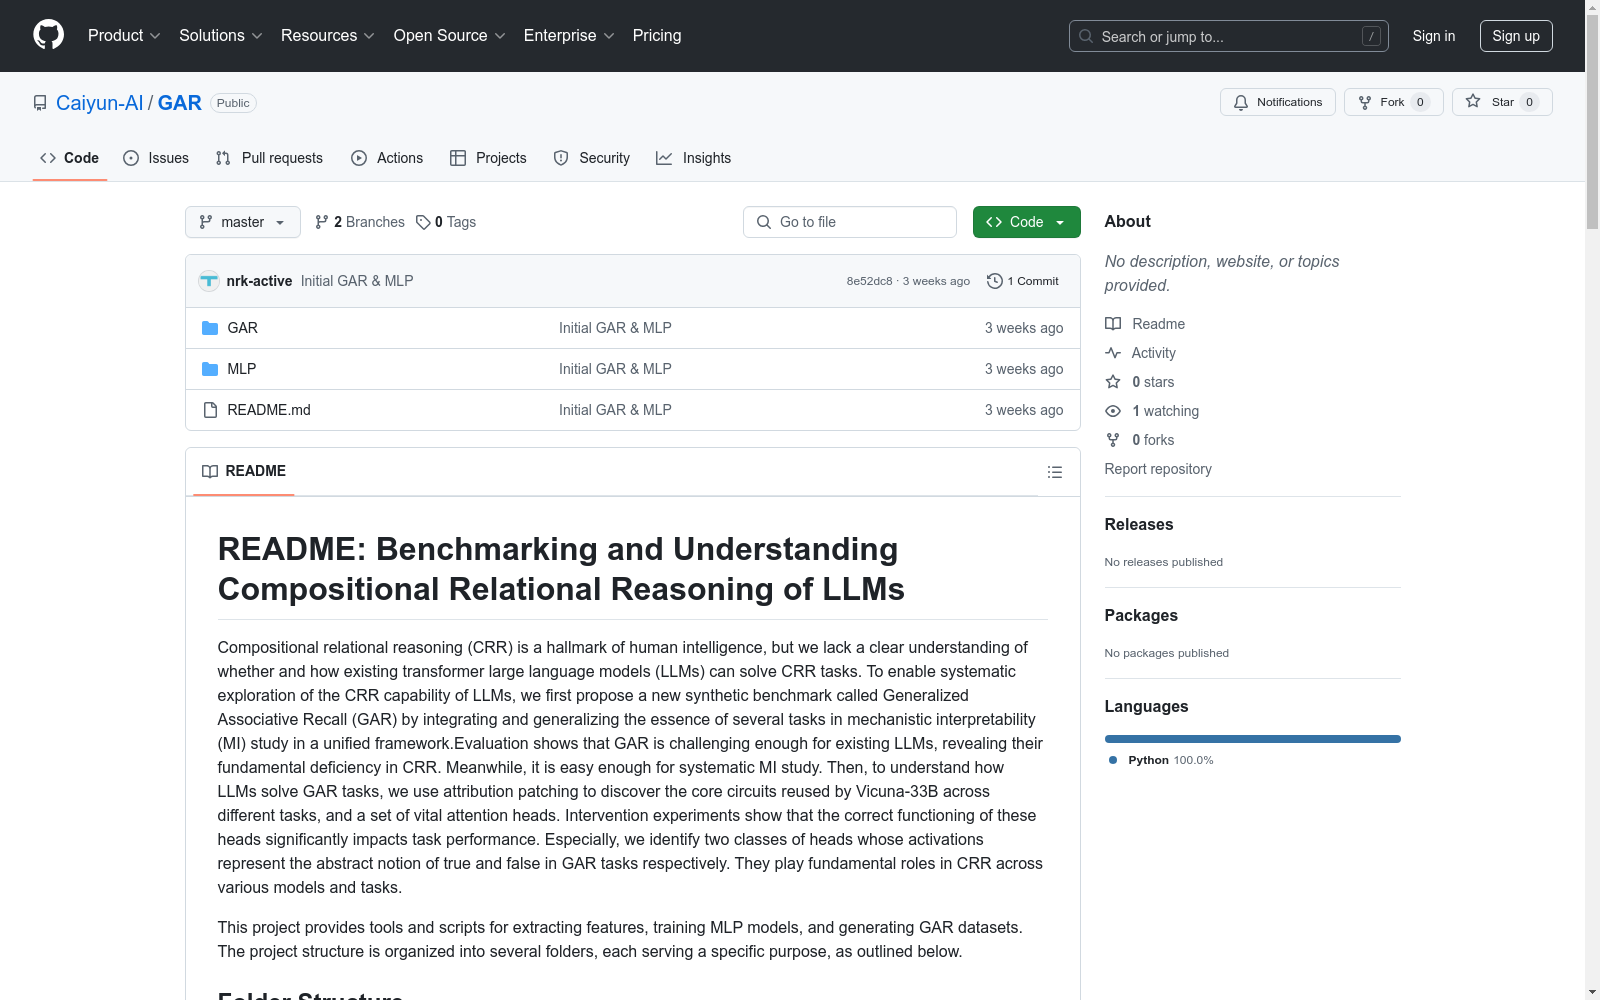
GAR 是一个用于评估大型语言模型(LLMs)在组合关系推理(Compositional Relational Reasoning, CRR)任务中表现的综合基准。该数据集通过整合和概括机械解释性(Mechanistic Interpretability, MI)研究中的多个任务,形成了一个统一的框架。GAR 数据集旨在揭示现有 LLMs 在 CRR 任务中的基本缺陷,并为系统性 MI 研究提供基础。
数据集结构
GAR
- code: 包含生成 GAR 数据的代码(
GAR_utils.py和generate_GAR.py)以及基础数据。 - data: 包含由
generate_GAR.py生成的 GAR 示例,共有 4608 条数据。
MLP
- code: 包含训练模型(
train_and_test_MLP.py)和提取特征(get_features.py)的代码。 - data: 包含四个文件夹,分别是
GoT_zero_shot和SNLI_zero_shot,用于提取 GoT/SNLI 特征的 JSONL 文件和 CSV 文件;以及GoT_one_shot和SNLI_one_shot,用于模型测试的 GoT/SNLI 数据。
数据集使用
1. 生成 GAR 数据
运行以下命令生成 GAR 数据集:
python GAR/code/generate_GAR.py --cache_dir Your cache_dir --model_name Your model_name
2. 训练和测试 MLP
2.1. 提取特征
运行以下命令从数据集中提取特征:
python MLP/code/get_features.py --cache_dir Your cache_dir --model_name Your model_name --file_path Your data path
2.2. 训练 MLP 模型
运行以下命令训练 MLP 模型:
python MLP/code/train_and_test_MLP.py --dataname SNLI
依赖
- PyTorch 2.3.1
- Huggingface Transformers 4.36.0
- 所需模型:Vicuna-33B-v1.3