MBZUAI/LaMini-instruction
收藏资源简介:
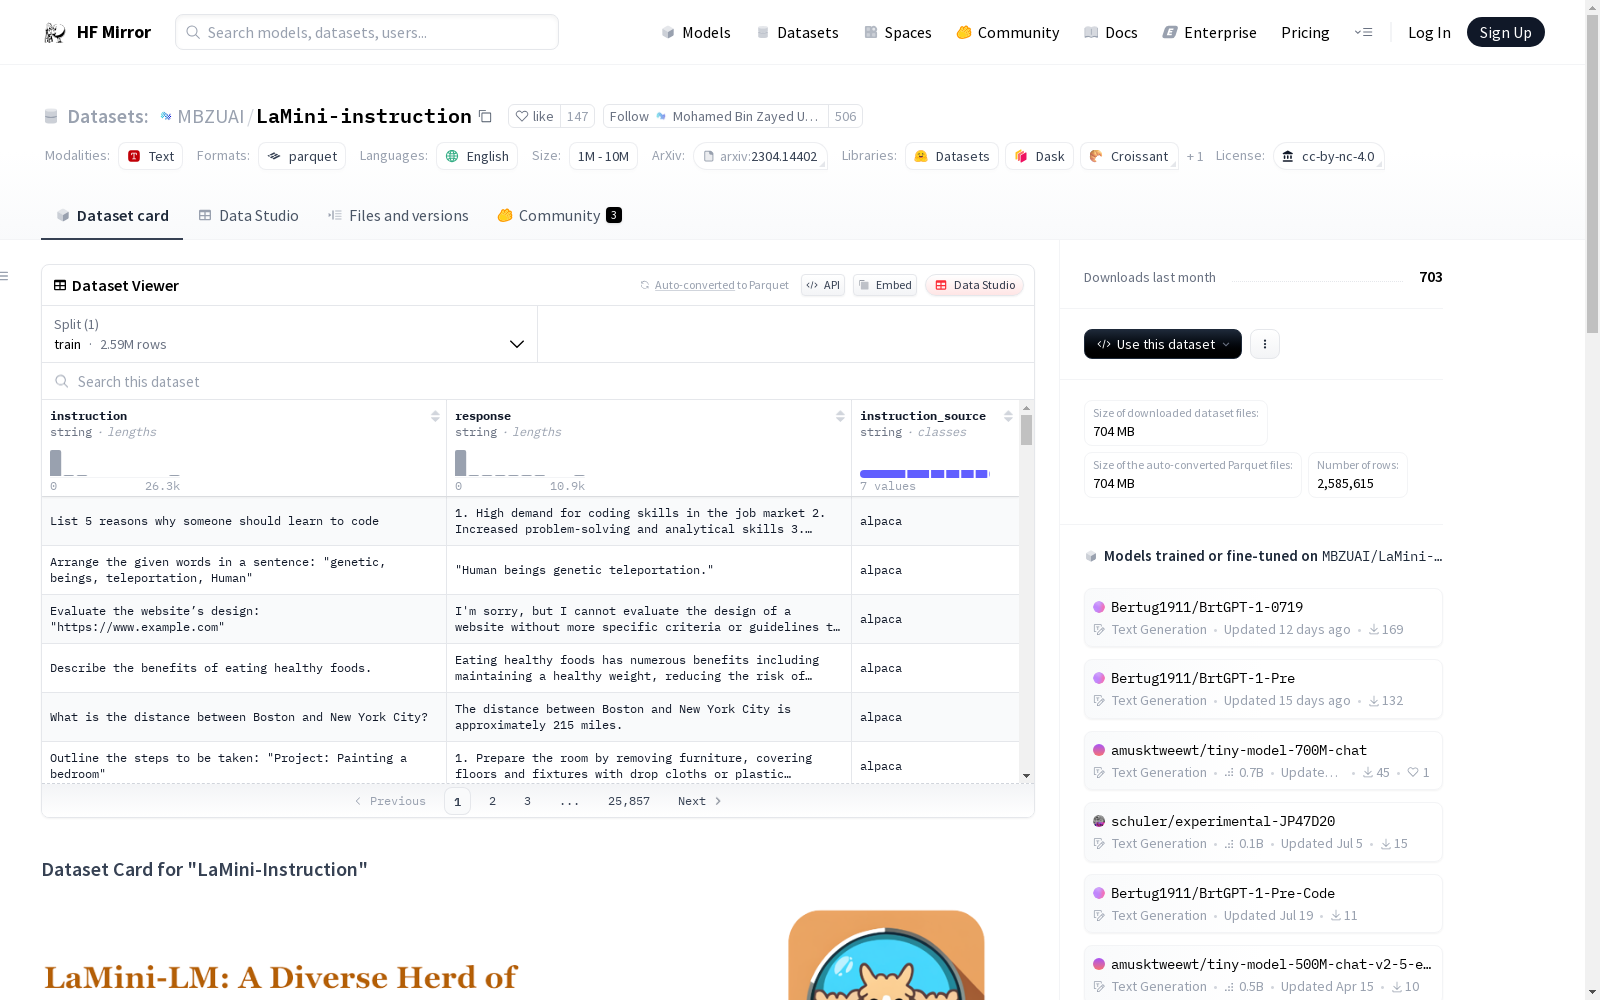
LaMini-Instruction数据集通过从大型语言模型中提取知识,使用gpt-3.5-turbo生成了258万对指令和响应。每个样本包含指令、响应和指令来源三个字段。指令字段描述了模型需要执行的任务,响应字段是gpt-3.5-turbo生成的响应,指令来源字段指示了指令的来源。数据集用于微调小型语言模型,并指出数据集中可能包含的错误和偏见。
The LaMini-Instruction dataset extracts knowledge from large language models, and uses gpt-3.5-turbo to generate 2.58 million instruction-response pairs. Each sample contains three fields: instruction, response, and instruction source. The instruction field describes the task that the model needs to perform, the response field holds the outputs generated by gpt-3.5-turbo, and the instruction source field indicates the origin of the corresponding instruction. This dataset is intended for fine-tuning small language models, and it is noted that potential errors and biases may exist within the dataset.
数据集概述
数据集名称: LaMini-Instruction
许可证: Creative Commons NonCommercial (CC BY-NC 4.0)
任务类别: text2text-generation
语言: English
数据集大小: 1M<n<10M
数据集结构
数据字段
- instruction: 字符串类型,描述模型预期执行的任务。
- response: 字符串类型,由
gpt-3.5-turbo生成的指令响应。 - instruction_source: 字符串类型,指令的来源,可能的值包括
{alpaca, generated_flan, generated_p3, original_flan, original_p3, self_instruct_with_topic, self_instruct_without_topic}。
数据分割
- 训练集: 包含2585615个实例,总字节数为1162632572。
数据集使用注意事项
- 数据集的输出是从ChatGPT中提炼的,因此包含ChatGPT产生的错误和偏见。使用此数据集训练的模型将继承这些错误和偏见。建议用户谨慎使用此数据,并提出新的方法来过滤或改进这些不完美之处。
数据集生成
- 数据集通过执行句子/离线提炼(Kim和Rush, 2016)生成,共生成2.58M对指令和响应,使用
gpt-3.5-turbo基于多个现有的提示资源。 - 用于微调各种小型语言模型,形成LaMini-LM模型系列。