CFinBench
收藏资源简介:
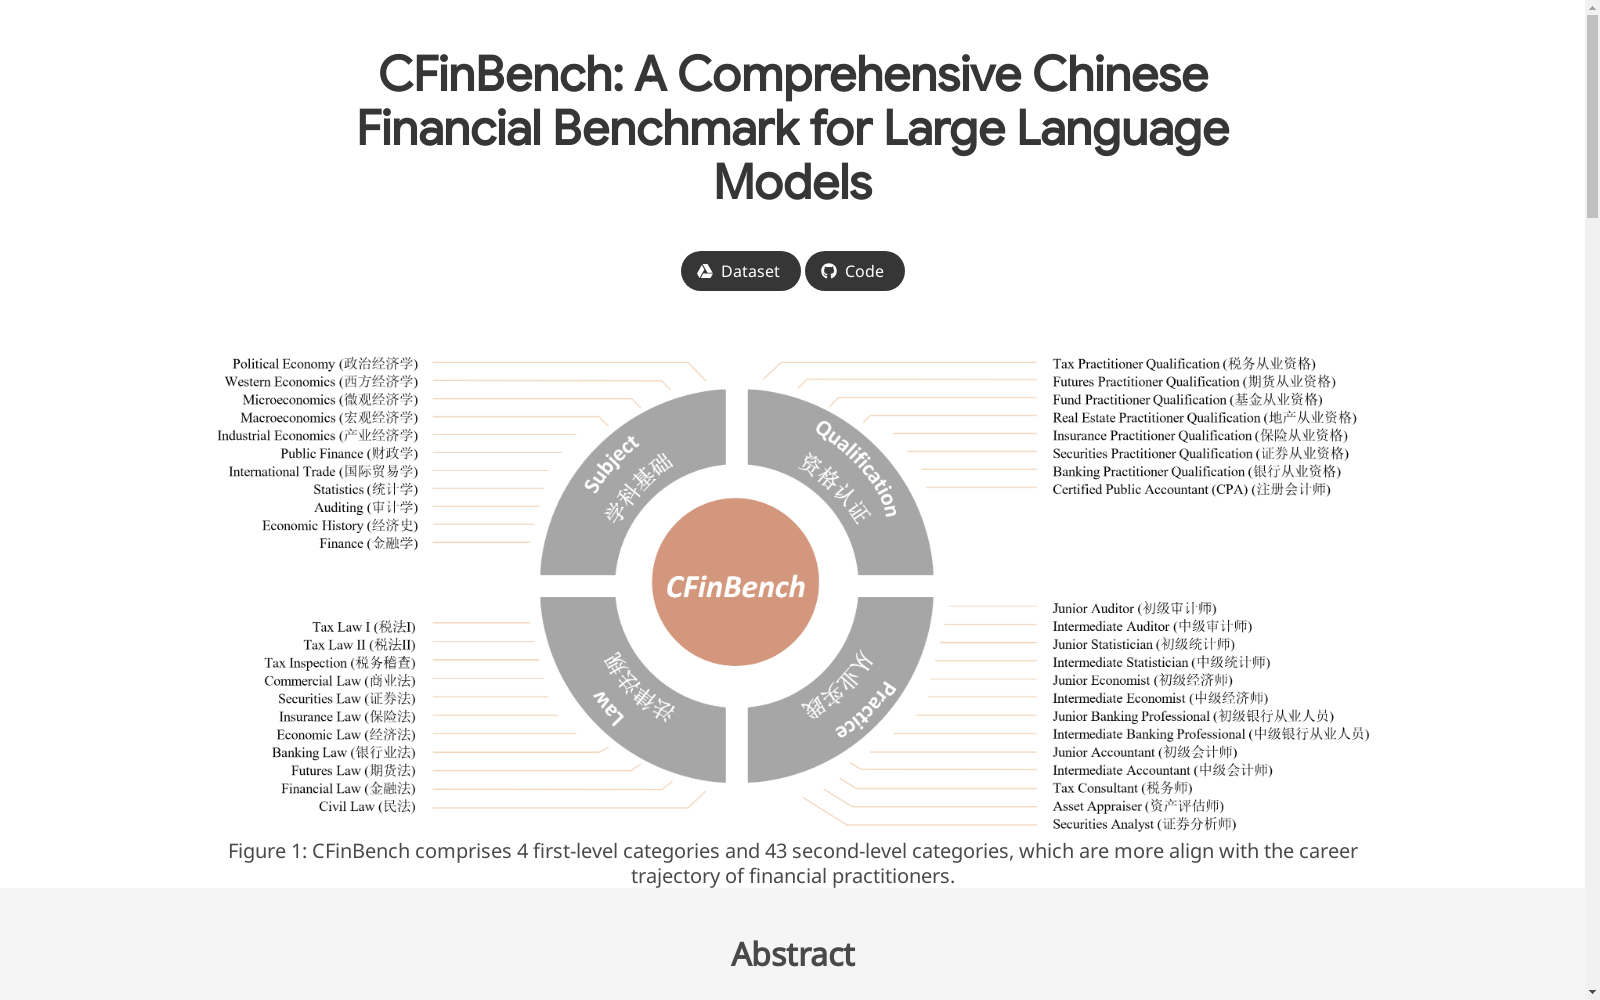
CFinBench是由华为诺亚方舟实验室等机构精心打造的中文金融领域大型语言模型评估基准,包含99,100条问题,覆盖43个细分领域,涉及单选、多选和判断题三种题型。数据集内容源自网络公开的模拟考试,经过多轮数据清洗和人工验证,确保了数据的高质量和广泛适用性。该数据集旨在全面评估模型在金融知识、资格认证、实际操作及法律法规等方面的能力,为金融领域的大型语言模型研究和应用提供了一个高标准、全面的测试平台。
CFinBench is a carefully curated evaluation benchmark for Chinese financial domain large language models, developed by institutions including Huawei Noah's Ark Lab and others. It consists of 99,100 questions covering 43 sub-sectors, with three question types: single-choice, multiple-choice, and true-false questions. The dataset content is sourced from publicly available online mock exams, and has undergone multiple rounds of data cleaning and manual verification to ensure its high quality and broad applicability. This benchmark aims to comprehensively evaluate a model's capabilities in financial knowledge, qualification certification, practical operations, laws and regulations, and other relevant areas, providing a high-standard and comprehensive test platform for research and applications of large language models in the financial domain.
CFinBench 数据集概述
关于数据集
CFinBench 是一个综合评估基准,专门设计用于在中国背景下评估大型语言模型(LLMs)的金融知识。该基准围绕四个主要类别构建:金融主题、金融资格、金融实践和金融法律。这些类别分别考察 LLMs 在基础金融知识、获取必要金融认证、履行实际金融角色以及遵守金融法律法规方面的能力。CFinBench 包含 99,100 个问题,涵盖 43 个子类别和三种类型的问题:单选、多选和判断题。
该基准用于评估 50 个代表性 LLMs,包括 GPT4 和几个面向中国的模型。结果显示,GPT4 和一些中国模型在评估中领先,最高平均准确率为 60.16%。这突显了 CFinBench 的挑战性。研究作者计划公开所有数据和评估代码,以供该领域的进一步研究和开发。
公告
- 2024/07/06 论文链接:arXiv Here。
- 2024/06/20 数据集发布链接:Here。
- 2024/06/16 评估代码已开源:Here。
- 2024/06/12 所有数据和评估代码即将发布。
引用
@article{nie2024cfinbench, title={CFinBench: A Comprehensive Chinese Financial Benchmark for Large Language Models}, author={Nie, Ying and Yan, Binwei and Guo, Tianyu and Liu, Hao and Wang, Haoyu and He, Wei and Zheng, Binfan and Wang, Weihao and Li, Qiang and Sun, Weijian and others}, journal={arXiv preprint arXiv:2407.02301}, year={2024} }