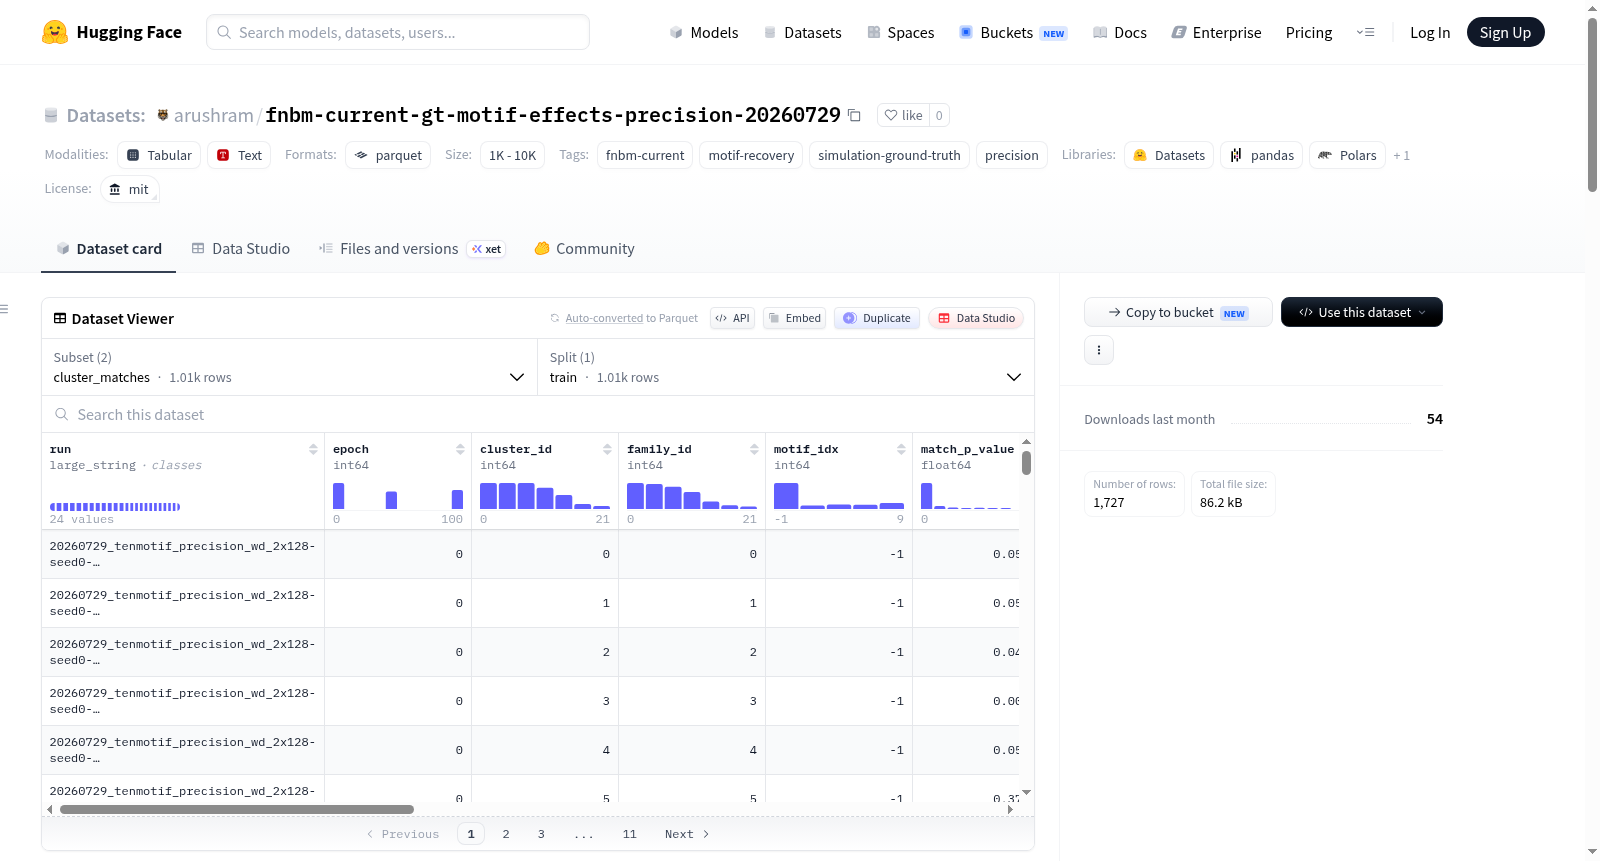
fnbm-current-gt-motif-effects-precision-20260729
收藏资源简介:
该数据集名为 "fnbm-current-gt-motif-effects-precision-20260729",旨在评估模拟 ground truth 中植入的 motif 效应在去重后的恢复精度。效应大小定义为每个 motif 家族聚类后每个样本贡献(OLS 斜率)与 motif 真实出现次数之间的线性关系,其单位与模拟器的 beta 系数相同,且不受去重管道内部规范的影响。每个样本贡献的均方误差(MSE)是在验证集上对中心化贡献计算的。数据集包含两个配置:"first_order" 和 "cluster_matches",其中 "cluster_matches" 配置包含 1007 个训练样本。数据共有 27 个字段,包括 run(运行目录名)、epoch(训练轮次)、motif_idx(植入 motif 的索引)、beta_gt(植入的一阶效应大小)、gt_contribution_std(植入的每个样本贡献的标准差)、mean_occurrences(每个验证序列中 motif 的平均出现次数)、n_families_matched(匹配的 motif 家族数量)、family_ids(家族 ID 列表)、n_clusters(归因于该 motif 的去重簇数)、cluster_ids(簇 ID 列表)、filter_ids(卷积滤波器索引)、n_filters(滤波器数量)、family_match_conflict(家族匹配冲突标志)、effect_gauge(管道自身的效应标量,与 beta_gt 不可比)、matched(是否匹配)、beta_hat(恢复的效应大小)、beta_hat_se(标准误)、contribution_corr(Pearson 相关系数)、model_contribution_std(模型贡献的标准差)、mse(均方误差)、nmse(归一化均方误差,主要质量指标)、offset(偏移量)、count_slope_r(回归的 Pearson r)、interaction_context_dc_penalty、interaction_feature_l2_penalty、seed、arm(实验臂)。数据集通过 Hugging Face datasets 库加载,使用示例为 `load_dataset("arushram/fnbm-current-gt-motif-effects-precision-20260729", split="train")`。
The dataset is named fnbm-current-gt-motif-effects-precision-20260729 and aims to evaluate the recovery precision of implanted motif effects in simulated ground truth after deduplication. The effect size is defined as the linear relationship between the per-sample contribution (OLS slope) after clustering each motif family and the true motif occurrence count, with units identical to the simulators beta coefficients and unaffected by the deduplication pipelines internal normalization. The mean squared error (MSE) of per-sample contributions is computed on the validation set for centered contributions. The dataset includes two configurations: first_order and cluster_matches, where the cluster_matches configuration contains 1007 training samples. The data has 27 fields, including run (run directory name), epoch (training epoch), motif_idx (index of the implanted motif), beta_gt (implanted first-order effect size), gt_contribution_std (standard deviation of implanted per-sample contributions), mean_occurrences (average motif occurrences per validation sequence), n_families_matched (number of matched motif families), family_ids (list of family IDs), n_clusters (number of deduplication clusters attributed to the motif), cluster_ids (list of cluster IDs), filter_ids (convolutional filter indices), n_filters (number of filters), family_match_conflict (family match conflict flag), effect_gauge (pipeline-internal effect scalar, not comparable to beta_gt), matched (whether matched), beta_hat (recovered effect size), beta_hat_se (standard error), contribution_corr (Pearson correlation coefficient), model_contribution_std (standard deviation of model contributions), mse (mean squared error), nmse (normalized mean squared error, primary quality metric), offset (offset), count_slope_r (Pearson r of regression), interaction_context_dc_penalty, interaction_feature_l2_penalty, seed, arm (experimental arm). The dataset is loaded via the Hugging Face datasets library, using the example: `load_dataset("arushram/fnbm-current-gt-motif-effects-precision-20260729", split="train")`.
数据集概述
基本信息
- 数据集名称: fnbm-current-gt-motif-effects-precision-20260729
- 许可证: MIT
- 数据集大小: 234,540 字节(约 228 KB)
- 样本数量: 1,007 条训练样本(README 中另有描述为 720 行,以实际数据为准)
- 标签: fnbm-current、motif-recovery、simulation-ground-truth、precision
数据集内容
该数据集记录了去重后种植基序(motif)效应的恢复结果,并以模拟真实值(ground truth)作为评分基准。效应大小采用每个基序家族聚类后逐样本贡献对基序真实出现次数的 OLS 斜率,与模拟器的 beta 参数同单位,且不受去重流水线内部尺度影响。
数据集配置
数据集包含两个预配置(config):
| 配置名称 | 数据路径 |
|---|---|
| first_order | first_order/train-*.parquet |
| cluster_matches | cluster_matches/train-*.parquet |
主要字段说明
| 字段名 | 类型 | 描述 |
|---|---|---|
| run | large_string | 运行目录名,编码网格组合信息 |
| epoch | int64 | 执行去重遍的训练轮次 |
| motif_idx | int64 | 种植基序的索引 |
| beta_gt | float64 | 种植的一阶效应大小 |
| gt_contribution_std | float64 | 种植逐样本贡献的标准差 |
| mean_occurrences | float64 | 每个验证序列中该基序的平均出现次数 |
| n_families_matched | int64 | 归因于此的基序家族数量 |
| family_ids | large_string | 家族 ID 列表(逗号分隔) |
| n_clusters | int64 | 归因于此基序的去重簇数量 |
| cluster_ids | large_string | 簇 ID 列表(逗号分隔) |
| filter_ids | large_string | 对应卷积滤波器索引列表 |
| n_filters | int64 | 这些簇背后的卷积滤波器数量 |
| family_match_conflict | bool | 家族簇匹配到不同种植基序时是否为真 |
| effect_gauge | float64 | 流水线自身效应标量(仅用于连续性,不可与 beta_gt 比较) |
| matched | bool | 是否有簇的共识 PWM 通过 Tomtom 匹配该种植基序 |
| beta_hat | float64 | 恢复的效应大小,与 beta_gt 同单位,尺度不变 |
| beta_hat_se | float64 | beta_hat 的标准误 |
| contribution_corr | float64 | 模型逐样本贡献与种植 z1 之间的 Pearson 相关系数 |
| model_contribution_std | float64 | 模型逐样本贡献的标准差 |
| mse | float64 | 模型与种植逐样本贡献(均居中)之间的均方误差 |
| nmse | float64 | MSE 除以种植贡献方差,主要质量指标 |
| offset | float64 | 模型贡献均值与种植贡献均值之差 |
| count_slope_r | float64 | beta_hat 回归的 Pearson r |
| interaction_context_dc_penalty | float64 | 无描述 |
| interaction_feature_l2_penalty | float64 | 无描述 |
| seed | int64 | 无描述 |
| arm | large_string | 运行所属的实验组(precision 或 sensitivity) |
生成参数
- 生成脚本: scripts/publish_motif_gt_eval.py
- 模型: FactorizedNBM (fnbm_20260729)
- 实验名称: fnbm-current
- 工件类型: eval_result
- 运行次数: 24 次
- 训练轮次: [0, 50, 100]
使用示例
python from datasets import load_dataset
dataset = load_dataset("arushram/fnbm-current-gt-motif-effects-precision-20260729", split="train") print(f"Loaded {len(dataset)} rows")