omnilingual-gaia2
收藏资源简介:
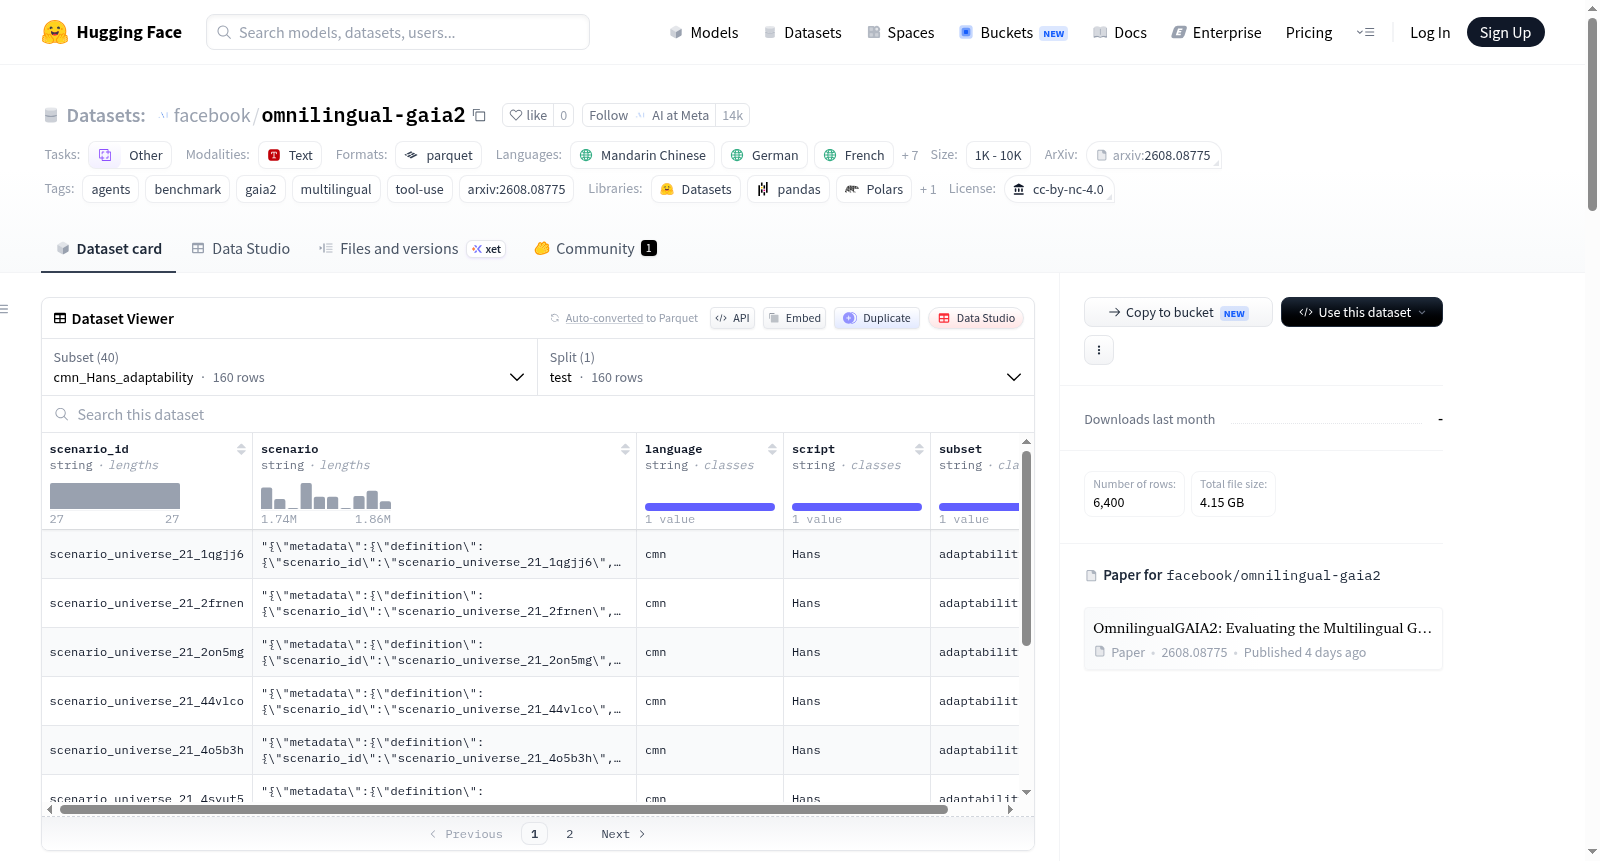
OmnilingualGAIA2 是一个多语言智能体基准数据集,是 GAIA2 基准的多语言扩展。它包含 6400 个场景,覆盖 10 种目标语言:简体中文、德语、法语、印地语、印度尼西亚语、意大利语、日语、葡萄牙语、西班牙语和土耳其语。每种语言包含 640 个场景,均匀分布在四个能力子集上:执行(execution)、搜索(search)、歧义(ambiguity)和适应性(adaptability),每个子集 160 个场景。数据集的每个配置对应一个 (语言_文字, 子集) 对,仅提供 test 分割。每条记录包含以下字段:scenario_id(跨语言共享的场景标识符)、scenario(以 JSON 字符串表示的完整场景定义,包含 metadata、apps、events、version 和 augmentation)、language(ISO 639-3 语言代码)、script(ISO 15924 文字代码)、subset(GAIA2 能力子集)。场景 ID 在不同语言中对齐,因此同一子集下的任意两个配置可以逐行比较。翻译通过机器翻译管线生成,使用了 google/gemma-4-31B-it 模型,并强制执行跨表面保真度约束,但未经过完全人工验证。该数据集适用于评估多语言智能体在工具使用、任务执行等场景中的能力,特别是衡量前沿 AI 智能体在多语言环境下的表现差距。
OmnilingualGAIA2 is a multilingual agent benchmark dataset, a multilingual extension of the GAIA2 benchmark. It contains 6400 scenarios covering 10 target languages: Simplified Chinese, German, French, Hindi, Indonesian, Italian, Japanese, Portuguese, Spanish, and Turkish. Each language includes 640 scenarios evenly distributed across four capability subsets: execution, search, ambiguity, and adaptability, with 160 scenarios per subset. Each configuration of the dataset corresponds to a (language_script, subset) pair, and only the test split is provided. Each record contains the following fields: scenario_id (a cross-language shared scenario identifier), scenario (a complete scenario definition in JSON string format, including metadata, apps, events, version, and augmentation), language (ISO 639-3 language code), script (ISO 15924 script code), and subset (GAIA2 capability subset). Scenario IDs are aligned across languages, so any two configurations under the same subset can be compared row by row. Translations are generated via a machine translation pipeline using the google/gemma-4-31B-it model, with cross-surface fidelity constraints enforced but not fully manually verified. This dataset is suitable for evaluating multilingual agents capabilities in tool use, task execution, etc., particularly measuring the performance gap of frontier AI agents in multilingual environments.
OmnilingualGAIA2 数据集概述
基本信息
- 数据集名称: OmnilingualGAIA2
- 发布机构: Facebook (Hugging Face 平台)
- 许可证: CC BY-NC 4.0(非商业使用)
- 任务类型: 其他(智能体基准测试)
- 相关论文: arXiv:2608.08775(访问地址)
数据集简介
OmnilingualGAIA2 是 GAIA2 智能体基准测试的多语言扩展版本,包含 6400 个场景,覆盖 10 种目标语言。所有场景均通过机器翻译管道从英文参考版本转换而来,并强制执行跨表面保留契约。
语言覆盖
| 语言 | 执行 | 搜索 | 歧义 | 适应性 | 总计 |
|---|---|---|---|---|---|
| 中文(简体) | 160 | 160 | 160 | 160 | 640 |
| 德语 | 160 | 160 | 160 | 160 | 640 |
| 法语 | 160 | 160 | 160 | 160 | 640 |
| 印地语 | 160 | 160 | 160 | 160 | 640 |
| 印度尼西亚语 | 160 | 160 | 160 | 160 | 640 |
| 意大利语 | 160 | 160 | 160 | 160 | 640 |
| 日语 | 160 | 160 | 160 | 160 | 640 |
| 葡萄牙语 | 160 | 160 | 160 | 160 | 640 |
| 西班牙语 | 160 | 160 | 160 | 160 | 640 |
| 土耳其语 | 160 | 160 | 160 | 160 | 640 |
总计: 6400 个场景
数据配置与结构
- 配置方式: 每个(语言, 子集)组合对应一个独立配置,共 40 个配置(10 语言 × 4 子集)
- 数据分割: 每个配置仅包含一个
test分割 - 文件格式: Parquet 格式
数据列说明
| 列名 | 描述 |
|---|---|
scenario_id |
跨语言共享的稳定 GAIA2 场景标识符 |
scenario |
完整的场景定义(JSON 字符串) |
language |
ISO 639-3 语言代码 |
script |
ISO 15924 文字代码 |
subset |
GAIA2 能力子集 |
场景对象结构
scenario 对象包含以下顶层键:metadata(场景 ID、持续时间、开始时间、提示、标签)、apps(智能体操作的序列化应用环境)、events(预言事件 DAG)、version、augmentation。
使用说明
可通过 datasets 库加载数据,例如:
python
from datasets import load_dataset
ds = load_dataset("facebook/omnilingual-gaia2", "spa_Latn_execution", split="test")
基准测试可通过将配置物化为场景 JSON 文件后,使用 gaia2-runner run-dataset 命令运行。
验证器说明
使用标准英文验证器对非英语轨迹进行评分并非公平比较。多语言验证器正在通过 PR 形式发布在 Meta Agents Research Environments 仓库中,在合并前,使用默认判断器进行的跨语言比较结果仅作参考。
数据来源与局限性
- 源数据集: meta-agents-research-environments/gaia2-cli
- 翻译方式: 使用 google/gemma-4-31B-it 进行机器翻译
- 验证状态: 翻译结果未经完全人工验证
引用格式
bibtex @misc{caciolai2026omnilingualgaia2evaluatingmultilingualgap, title={OmnilingualGAIA2: Evaluating the Multilingual Gap in Frontier AI Agents}, author={Andrea Caciolai and Pere-Lluís Huguet Cabot and Chierh Cheng and Albert Ventayol-Boada and Gabriel Mejia Gonzalez and Christophe Ropers and Lucas Bandarkar and Sebastian Ruder and Darlene Sakakihara and Elliot Yun and Pierre Andrews and Grégoire Mialon and Romain Froger and Marta R. Costa-jussà}, year={2026}, eprint={2608.08775}, archivePrefix={arXiv}, primaryClass={cs.CL}, url={https://arxiv.org/abs/2608.08775}, }