dh-unibe/kurrent-hanse-xvi-test-lines-with-evaluation
收藏资源简介:
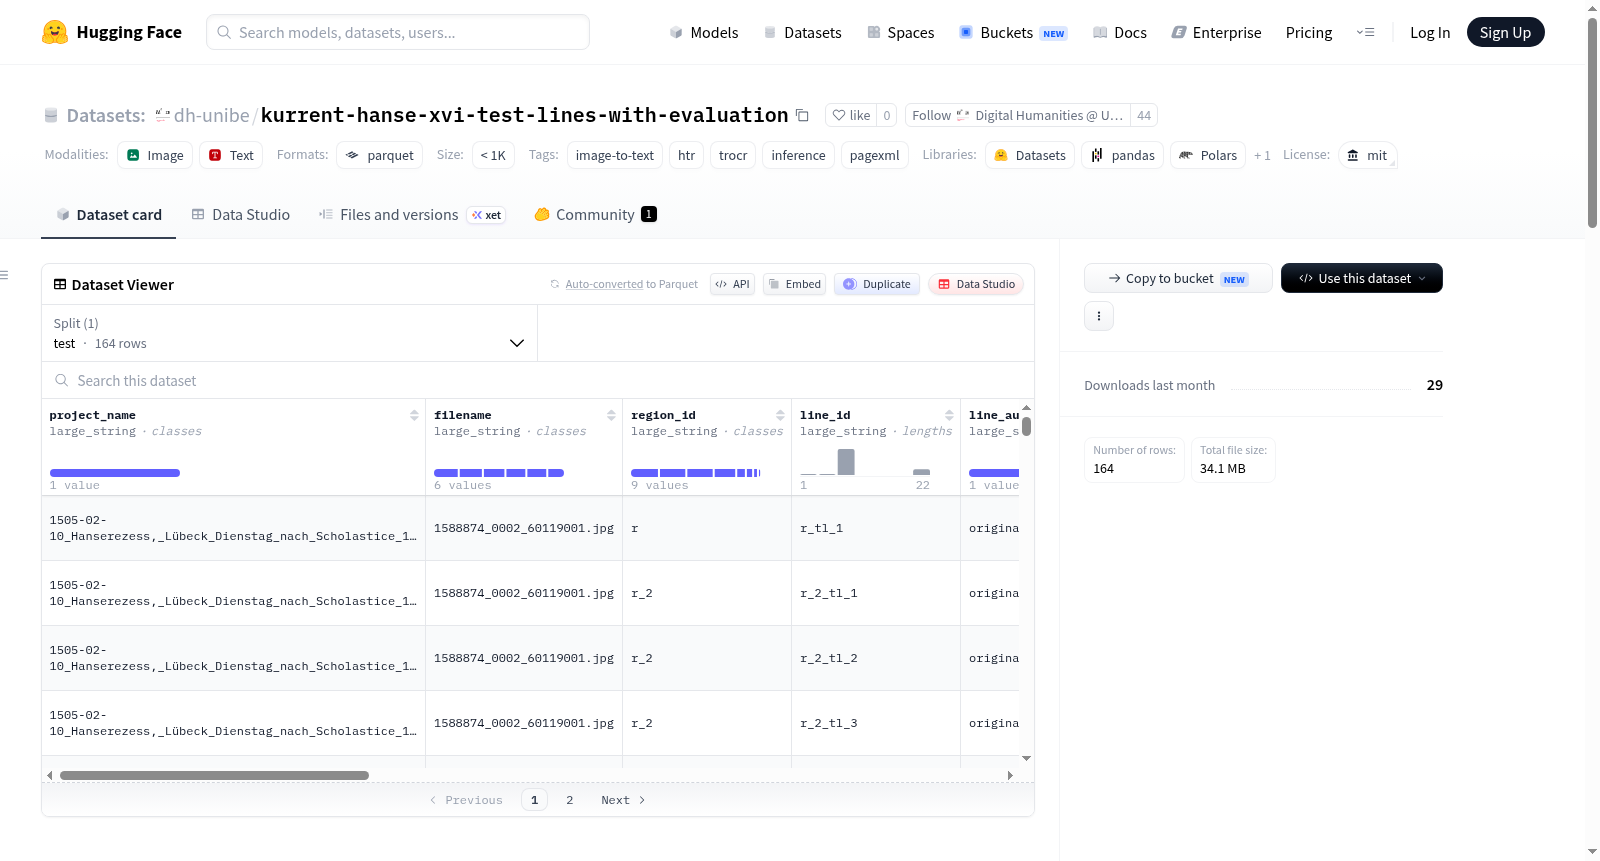
该数据集名为evaluation-hf-printed,是基于danameyer/evaluation-hf-printed数据集并经过推理结果增强的版本。它包含164个样本,仅用于测试分割。数据集主要用于图像到文本转换、手写文本识别(HTR)和TrOCR模型的推理评估。数据特征包括项目名称、文件名、区域ID、行ID、行增强信息、图像、文本、行阅读顺序、行坐标、行基线、区域阅读顺序、区域类型、区域坐标以及一个特定的推理结果列(例如inference_20260605_220242_149959_model_dh-unibe_trocr-kurrent-XVI-XVII)。数据以parquet格式组织,按分割和项目名称分片存储。评估结果显示字符错误率(CER)为0.435,评估时间戳为2026-06-06T00:37:26。数据集适用于NLP和计算机视觉任务,特别是历史文档或印刷文本的自动识别和评估。
This dataset, named evaluation-hf-printed, is derived from danameyer/evaluation-hf-printed and has been enriched with inference results. It contains 164 samples across a single test split. The dataset is designed for image-to-text conversion, handwritten text recognition (HTR), and TrOCR model inference evaluation. Features include project_name, filename, region_id, line_id, line_augmentation, image, text, line_reading_order, line_coords, line_baseline, region_reading_order, region_type, region_coords, and a specific inference column (e.g., inference_20260605_220242_149959_model_dh-unibe_trocr-kurrent-XVI-XVII). Data is organized in parquet format, sharded by split and project name. Evaluation results show a Character Error Rate (CER) of 0.435, with a timestamp of 2026-06-06T00:37:26. The dataset is suitable for NLP and computer vision tasks, particularly for automatic recognition and evaluation of historical documents or printed texts.