VidProM
收藏资源简介:
VidProM是由悉尼科技大学的Wenhao Wang和浙江大学的Yi Yang共同创建的大型数据集,包含167万条独特的文本到视频提示和669万条由四个最先进的扩散模型生成的视频。数据集通过网络抓取和本地生成两种方式收集视频,利用最新的文本嵌入模型进行构建,旨在推动文本到视频提示工程、高效视频生成、假视频检测和视频复制检测等研究领域的发展。VidProM数据集的应用领域广泛,包括但不限于视频内容的自动生成和视频版权保护。
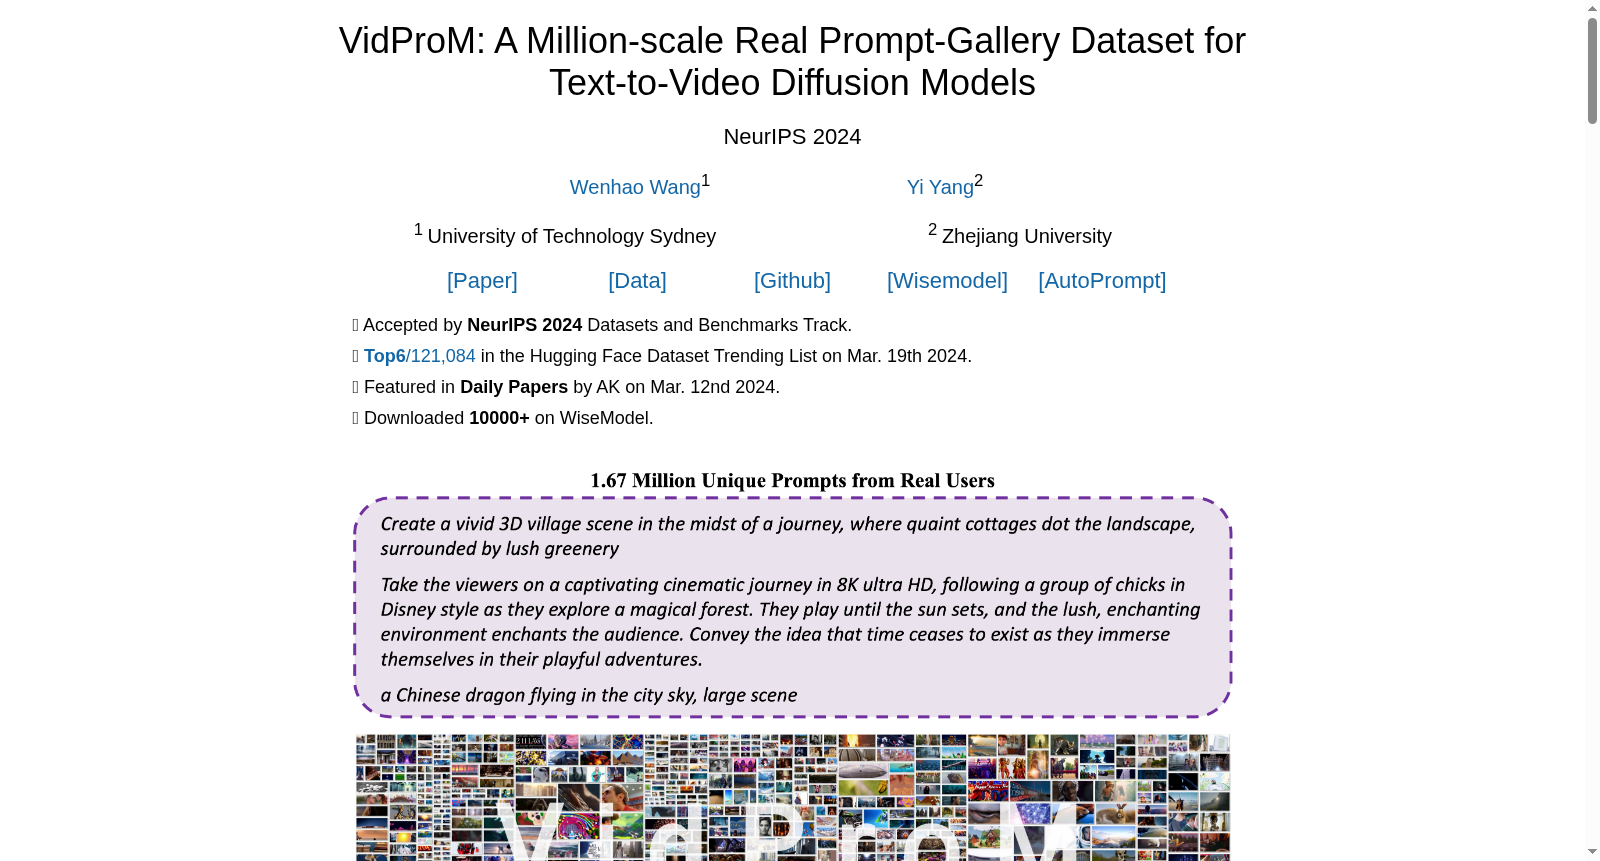
VidProM is a large-scale dataset co-created by Wenhao Wang from the University of Technology Sydney and Yi Yang from Zhejiang University. It contains 1.67 million unique text-to-video prompts and 6.69 million videos generated by four state-of-the-art diffusion models. The dataset collects videos via two approaches: web scraping and local generation, and is constructed using the latest text embedding models. It aims to advance research in fields including text-to-video prompt engineering, efficient video generation, deepfake video detection, and video copy detection. The VidProM dataset has broad application scenarios, including but not limited to automatic video content generation and video copyright protection.