cstr/grundwortschatz-voc-en
收藏资源简介:
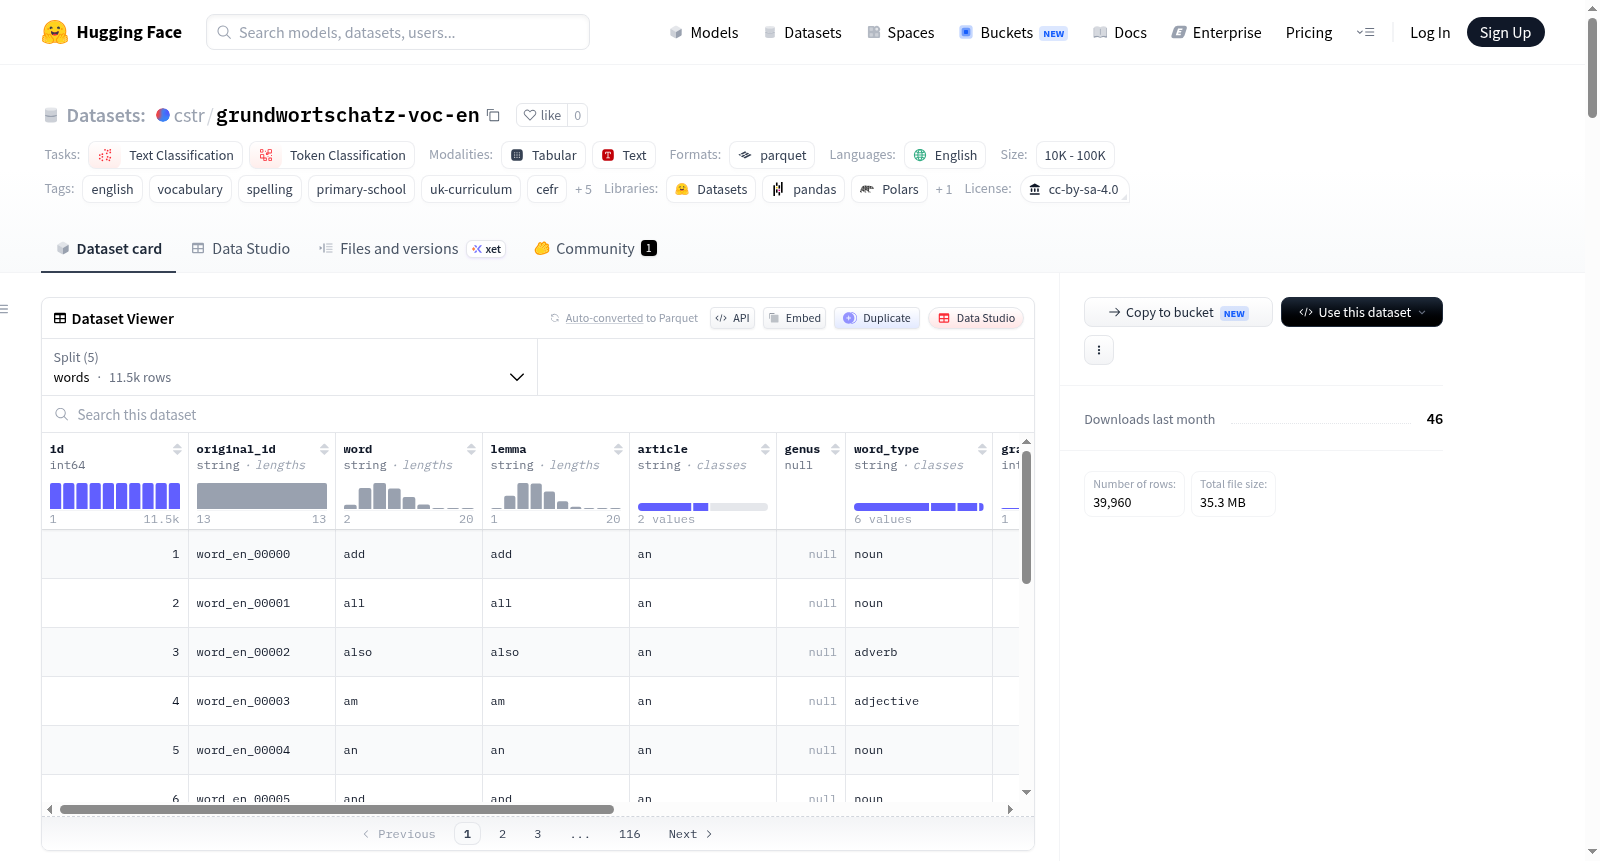
WortUniversum英语词汇数据库是一个包含11,539个词元的英国英语词汇数据库,覆盖了小学阶段词汇(对应CEFR-J A1–B2级别、剑桥少儿英语Starters/Movers/Flyers考试、英国国家课程1-6年级拼写列表),并为每个单词提供了多源增强信息。增强内容包括:Wiktionary的定义、国际音标发音、词形变化和例句;开放英语词网(OEWN)的词义记录,如近义词、反义词、上位词和下位词;wordfreq的Zipf分数、每百万词出现频率和频率带(1-5级);CEFR-J v1.5级别标签(A1–B2),覆盖6,879个条目;剑桥少儿英语Starters/Movers/Flyers词汇标签,覆盖833个条目;英国教育部法定拼写列表(1-2年级、3-4年级、5-6年级),覆盖318个条目;所有条目的课程衍生年级估计(1-6级);针对4,653个条目的27,363个常见学习者错误对(来自Norvig和Wikipedia);针对150个条目的264个英式与美式方言拼写变体(基于SCOWL);分级例句(由LLM生成,覆盖所有6个年级);来自72本公有领域英语书籍的Project Gutenberg例句;以及与应用程序运行时兼容的SQLite FTS5搜索索引。该词汇库是课程目标的超集,标签控制应用程序根据用户级别展示的子集。数据集以SQLite数据库(grundwortschatz_en.db.gz)形式提供,并包含Parquet格式的辅助文件(words.parquet、translations.parquet、examples.parquet等),支持通过pandas或DuckDB加载。数据集主要用于教育应用、词汇学习和自然语言处理研究。
A UK-English lexical database of 11,539 lemmas covering primary-school vocabulary (CEFR-J A1–B2, YLE Starters/Movers/Flyers, UK Year 1–6 statutory lists), with multi-source enrichment per word: Wiktionary definitions, IPA pronunciation, inflections, examples; Open English WordNet (OEWN) sense records: synonyms, antonyms, hypernyms, hyponyms; wordfreq Zipf score, occurrences-per-million, frequency band (1–5); CEFR-J v1.5 level tags (A1–B2) for 6,879 entries; Cambridge YLE Starters / Movers / Flyers vocabulary tags (833 entries); UK DfE statutory spelling lists: Year 1–2, 3–4, 5–6 (318 entries); Curriculum-derived gradeLevelEstimate (1–6) for all entries; 27,363 common learner error pairs on 4,653 entries (Norvig + Wikipedia); 264 UK ↔ US dialect spelling variants across 150 entries (SCOWL); Grade-differentiated example sentences (LLM-generated, all 6 grades); Project Gutenberg example sentences from 72 public-domain EN books; SQLite FTS5 search index compatible with the app runtime. The vocabulary is a superset of curriculum targets; tags control which subset the app surfaces per user level. The dataset ships as a SQLite database (grundwortschatz_en.db.gz) with Parquet companion files (words.parquet, translations.parquet, examples.parquet, etc.), loadable via pandas or DuckDB. It is intended for educational applications, vocabulary learning, and NLP research.