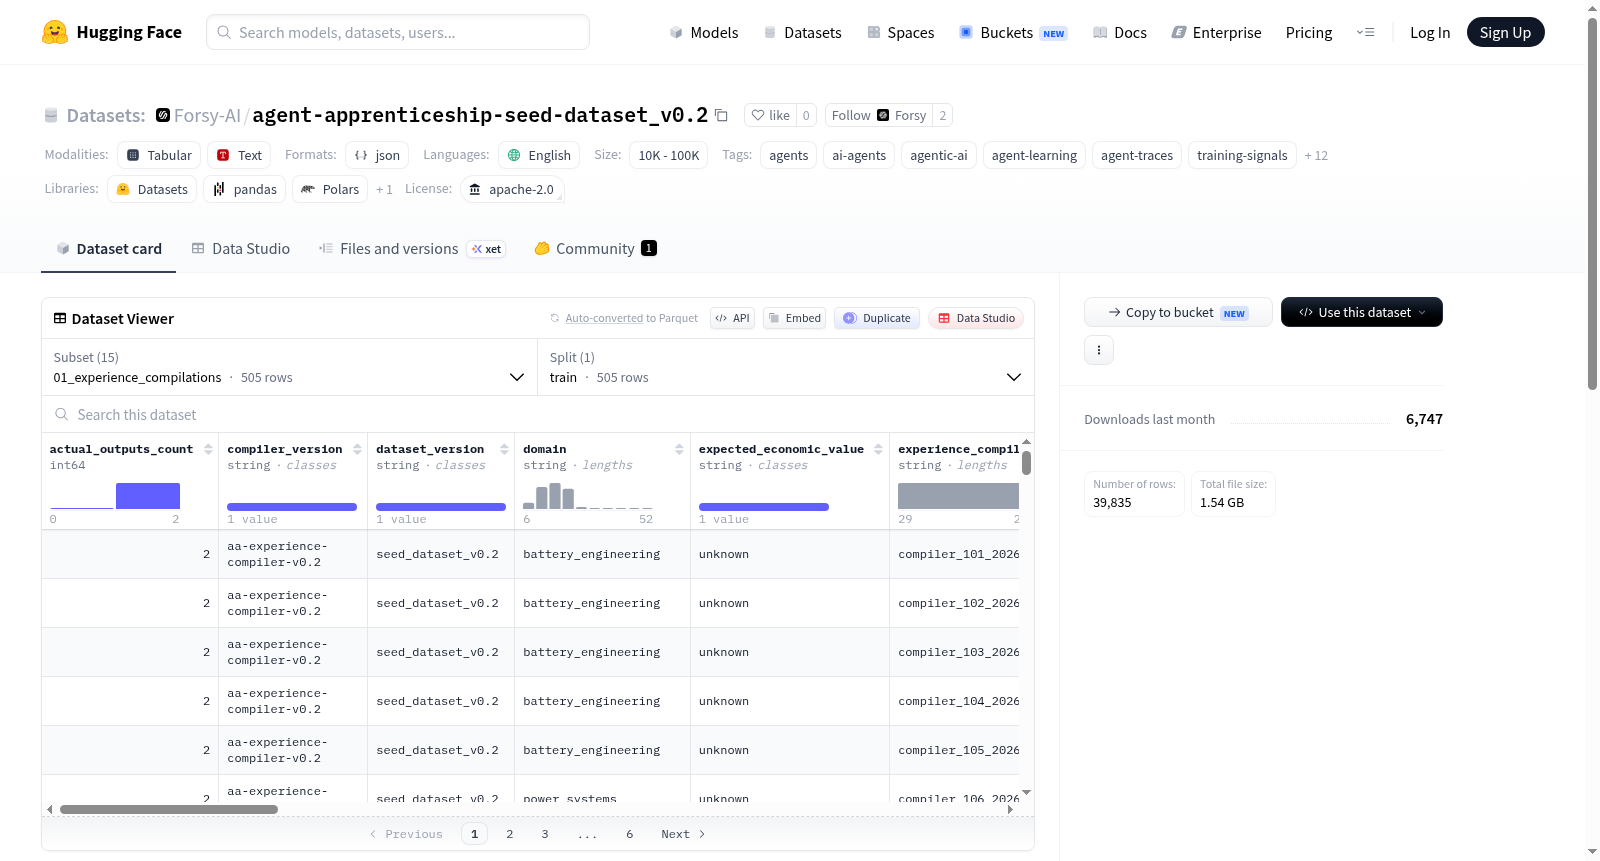
agent-apprenticeship-seed-dataset_v0.2
收藏资源简介:
Agent Apprenticeship Seed Dataset v0.2是一个开源数据集,专为AI代理学习和改进设计,旨在构建一个生态系统,将真实世界代理工作经验循环转化为集体学习。在该系统中,AI代理通过工作流循环完成任务,并通过迭代执行不断优化,由导师代理或人类评估,最终将工作转化为可重用的经验和数据,以提升未来代理性能。数据集支持跨领域迭代工作流,涵盖从简单任务到复杂专业工作的多种场景,学徒代理与导师代理、用户或人类专家协作完成真实任务,同时每个工作流生成可重用的学习信号。具体包含500多个精选和基础化的种子任务、495个可重用代理课程、1000多个完整代理执行轨迹、1000多个代理工作片段/任务展开、505个完整代理工作经验编译以及39000多个结构化经验编译记录。数据集涵盖多个领域的专业且具有经济价值的任务,是Agent Apprenticeship生态系统的第一层,支持与本地代理(如Codex、Cursor、Claude Code等)及不同模型提供商结合使用,用户可本地运行自动化工作流循环,贡献学习信号到生态系统,并利用共享信号改进自身代理。
Agent Apprenticeship Seed Dataset v0.2 is an open-source dataset designed for AI agent learning and improvement, aiming to build an ecosystem that transforms real-world agent work experience cycles into collective learning. In this system, AI agents complete tasks through workflow loops, continuously optimize via iterative execution, are evaluated by mentor agents or humans, and ultimately convert work into reusable experience and data to enhance future agent performance. The dataset supports cross-domain iterative workflows, covering scenarios from simple tasks to complex professional work, with apprentice agents collaborating with mentor agents, users, or human experts on real-world tasks, while each workflow generates reusable learning signals. Specifically, it includes over 500 curated and foundational seed tasks, 495 reusable agent courses, over 1,000 complete agent execution trajectories, over 1,000 agent work segments/task expansions, 505 complete agent work experience compilations, and over 39,000 structured experience compilation records. The dataset covers professional and economically valuable tasks across multiple domains, forming the first layer of the Agent Apprenticeship ecosystem, and supports integration with local agents (e.g., Codex, Cursor, Claude Code, etc.) and various model providers, enabling users to run automated workflow loops locally, contribute learning signals back to the ecosystem, and leverage shared signals to improve their own agents.
数据集概述:Agent Apprenticeship Seed Dataset v0.2
该数据集是一个面向AI Agent的开放式训练与评估资源,旨在通过收集真实世界的Agent工作轨迹,构建可复用的学习信号,推动Agent的集体进化。
核心特点
- 真实世界任务驱动:数据集包含500多个经过精心筛选的真实世界任务,覆盖从简单到复杂专业工作的多个领域。
- 可复用的学习信号:每个Agent工作流程都会生成结构化的经验数据,可被生态系统中的其他Agent学习利用。
- 迭代式工作循环:支持Agent通过工作循环(workflow loops)执行任务,并在此过程中持续改进。
数据规模
- 任务数量:500多个精选种子任务
- Agent课程:495个可复用的Agent经验教训
- 执行轨迹:1000多个完整的Agent执行轨迹
- 工作回合:1000多个Agent工作片段/任务推演
- 经验汇编:505个完整的Agent工作经验汇编
- 结构化记录:39000多条结构化经验汇编记录
数据集配置与文件
数据集包含15个配置文件,每个配置文件对应一个JSONL数据文件,覆盖从原始经验到训练信号的完整流程:
| 配置名称 | 文件路径 | 描述 |
|---|---|---|
| 01_experience_compilations | data/01_experience_compilations.jsonl |
工作经验汇编 |
| 02_traces | data/02_traces.jsonl |
Agent执行轨迹 |
| 03_trace_steps | data/03_trace_steps.jsonl |
轨迹步骤分解 |
| 04_skill_packs | data/04_skill_packs.jsonl |
技能包 |
| 05_runtime_learning | data/05_runtime_learning.jsonl |
运行时学习数据 |
| 06_training_sft_examples | data/06_training_sft_examples.jsonl |
监督微调(SFT)示例 |
| 07_training_process_supervision | data/07_training_process_supervision.jsonl |
过程监督训练数据 |
| 08_training_reward_rows | data/08_training_reward_rows.jsonl |
奖励模型训练数据 |
| 09_training_verifier_rows | data/09_training_verifier_rows.jsonl |
验证器训练数据 |
| 10_preference_pairs_summary | data/10_preference_pairs_summary.jsonl |
偏好对总结 |
| 11_training_critique_revision_pairs | data/11_training_critique_revision_pairs.jsonl |
批评-修订对训练数据 |
| 12_training_failure_cases | data/12_training_failure_cases.jsonl |
失败案例 |
| 13_training_task_variants | data/13_training_task_variants.jsonl |
任务变体 |
| 14_eval_rubric_items | data/14_eval_rubric_items.jsonl |
评估准则条目 |
| 15_source_evidence_map | data/15_source_evidence_map.jsonl |
源证据映射 |
数据来源与构建
- 所有任务源自真实世界,经过专家或人类在循环中评估与验证。
- 数据由Agent在工作循环中执行任务时自动生成,包括成功与失败的案例。
- 支持本地Agent(如Codex、Cursor、Claude Code、OpenClaw等)以及多种模型提供商。
许可证与语言
- 许可证:Apache-2.0
- 语言:英语(en)
- 标签:agents, ai-agents, agentic-ai, agent-learning, agent-traces, training-signals, loop-engineering, reinforcement-learning, process-supervision, reward-modeling等。