PALR_finetuning20
收藏资源简介:
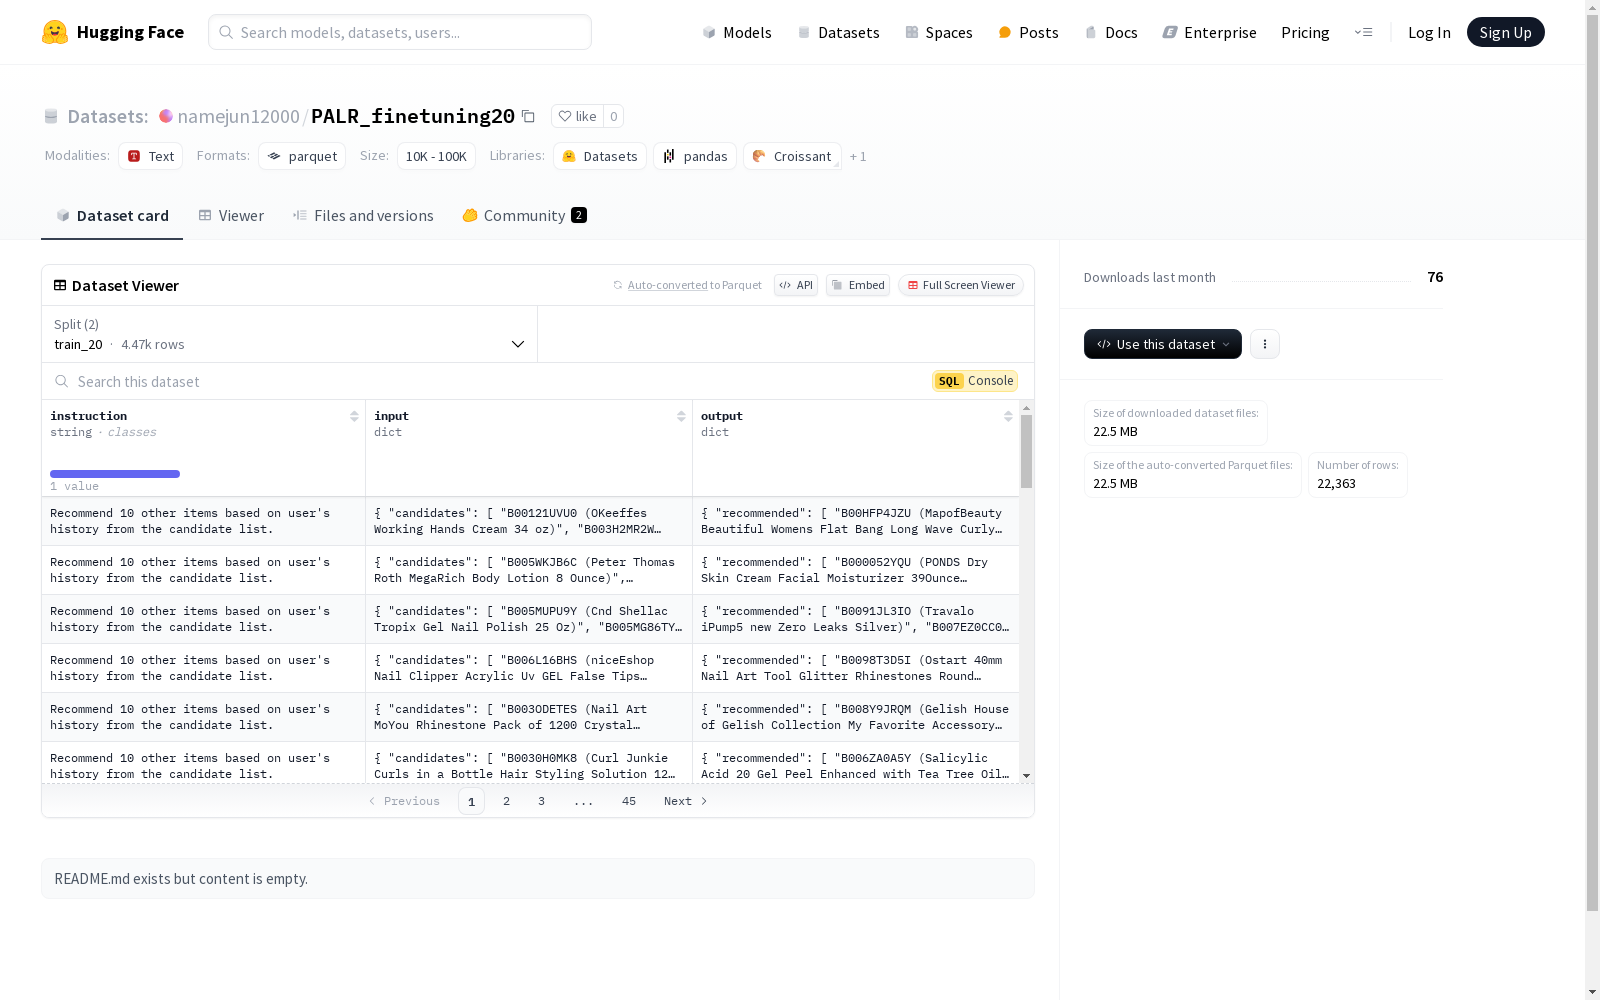
该数据集包含三个主要特征:'instruction'、'input'和'output'。'instruction'是一个字符串类型的特征,'input'是一个结构化特征,包含'candidates'、'interaction'和'user_id'三个子特征,其中'candidates'和'interaction'是字符串序列,'user_id'是字符串类型。'output'也是一个结构化特征,包含'recommended'子特征,是一个字符串序列。数据集分为两个部分:'train_20'和'train_80',分别包含4473和17890个样本。数据集的总下载大小为22525096字节,总数据集大小为136379314字节。
This dataset includes three primary features: 'instruction', 'input' and 'output'. The 'instruction' is a string-type feature. The 'input' is a structured feature that contains three sub-features: 'candidates', 'interaction' and 'user_id'. Specifically, 'candidates' and 'interaction' are string sequences, while 'user_id' is of string type. The 'output' is also a structured feature, which includes the sub-feature 'recommended' that is a string sequence. The dataset is split into two subsets: 'train_20' and 'train_80', which contain 4473 and 17890 samples respectively. The total download size of the dataset is 22525096 bytes, and the total size of the full dataset is 136379314 bytes.
PALR_finetuning20 数据集概述
数据集信息
特征
- instruction: 类型为
string。 - input: 包含以下结构:
- candidates: 类型为
sequence的string。 - interaction: 类型为
sequence的string。 - user_id: 类型为
string。
- candidates: 类型为
- output: 包含以下结构:
- recommended: 类型为
sequence的string。
- recommended: 类型为
数据分割
- train_20:
- 样本数量: 4473
- 字节数: 27162003
- train_80:
- 样本数量: 17890
- 字节数: 109217311
数据集大小
- 下载大小: 22525096 字节
- 数据集总大小: 136379314 字节
配置
- default:
- train_20: 路径为
data/train_20-* - train_80: 路径为
data/train_80-*
- train_20: 路径为