hotpotqa-variants
收藏资源简介:
HotpotQA ARIS Injection Variants 是一个基于 HotpotQA 短答案训练集构建的对抗性测试数据集,包含 104 个不同的数据变体,每个变体包含 1000 个样本。该数据集旨在研究“注入抑制后的答案保持(ARIS)”,即探究不同文本改写策略对大语言模型答案提取能力的干扰效果。每个变体通过一种特定的确定性脚本或大语言模型指令,对原始干净答案进行改写,策略涵盖位置埋藏、干扰列表、模糊性注入、对冲、元评论、对比结构等多种语言学或结构上的干扰技术。数据集中的每个样本包含四个字段:原始 HotpotQA 多跳问题、原始的简短干净答案、由确定性 Python 脚本生成的改写答案,以及由大语言模型根据更新后的变体指令提示生成的改写答案(对于无法生成改写的情况,回退使用原始答案)。该数据集适用于评估和增强大语言模型在存在干扰信息、误导性表述或复杂上下文结构下的鲁棒性、推理能力和答案提取准确性,尤其针对多跳问答任务。
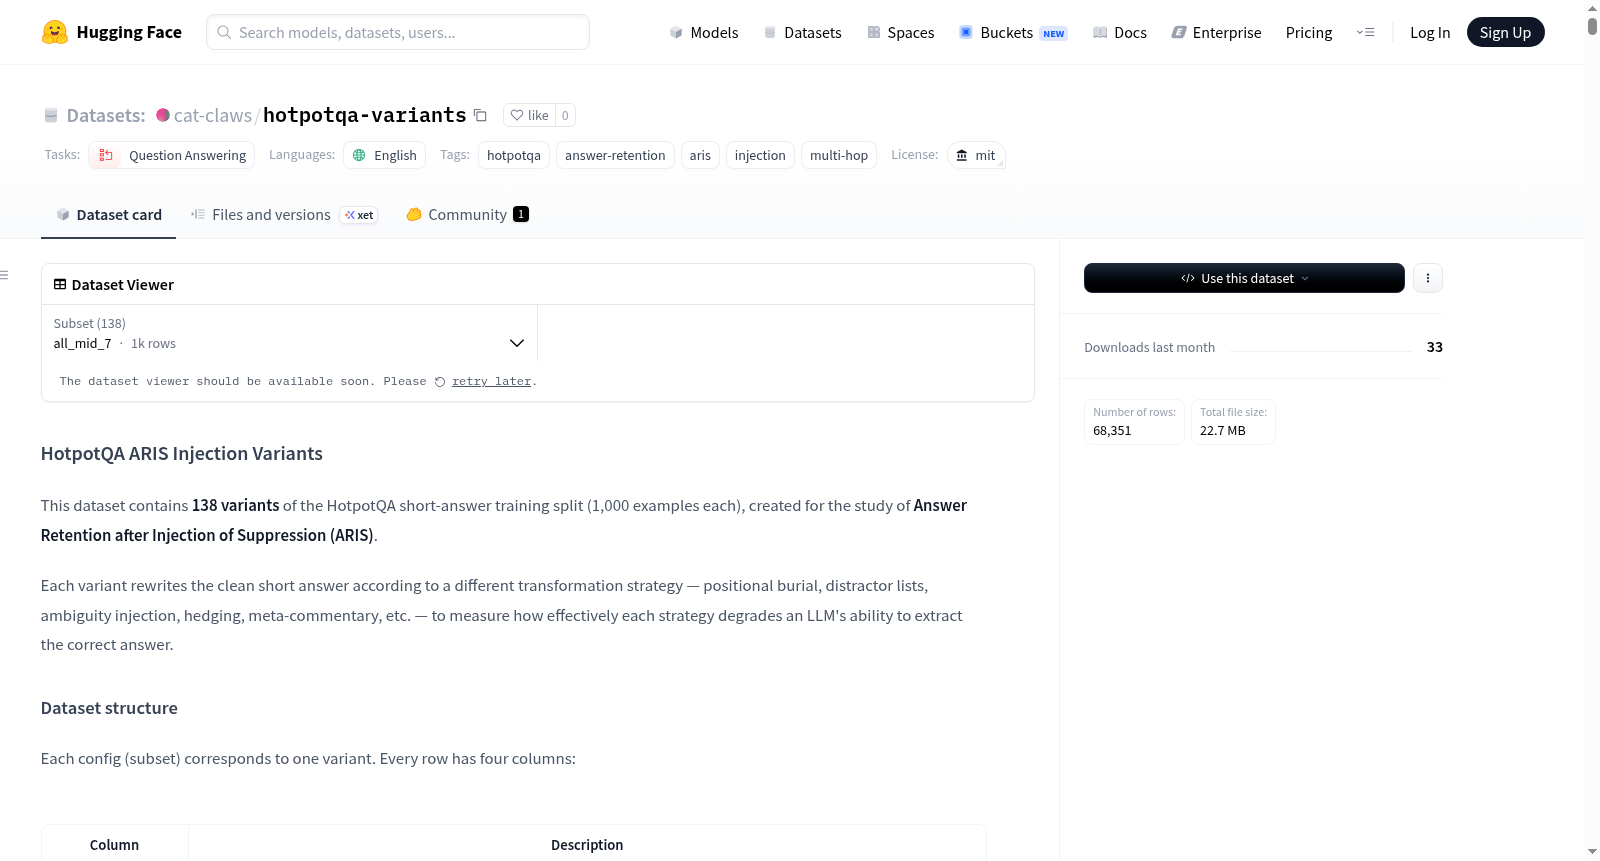
HotpotQA ARIS Injection Variants is an adversarial test dataset constructed from the HotpotQA short answer training set, containing 104 distinct data variants, each with 1000 samples. It aims to investigate Answer Retention after Injection Suppression (ARIS), exploring how different text rewriting strategies interfere with large language models answer extraction capabilities. Each variant rewrites the original clean answers using a specific deterministic script or large language model instruction, with strategies covering linguistic or structural interference techniques such as position burying, distracting lists, ambiguity injection, hedging, meta-commentary, and contrastive structures. Each sample in the dataset includes four fields: the original HotpotQA multi-hop question, the original short clean answer, the rewritten answer generated by a deterministic Python script, and the rewritten answer generated by a large language model based on updated variant instructions (falling back to the original answer if rewriting fails). This dataset is suitable for evaluating and enhancing the robustness, reasoning ability, and answer extraction accuracy of large language models in the presence of干扰信息、误导性表述或复杂上下文结构, particularly for multi-hop question answering tasks.
好的,根据您提供的README文件内容,以下是该数据集的详细信息总结。
数据集概述
该数据集名为 HotpotQA ARIS Injection Variants,是HotpotQA数据集的变体集,专门用于研究注入抑制后的答案保留(Answer Retention after Injection of Suppression, ARIS)现象。它包含了HotpotQA问答训练集(每个条目1000个样本)的138个不同变体。
数据集核心信息
- 任务类型:问答(question-answering)
- 语言:英语(en)
- 许可证:MIT
- 标签:hotpotqa, answer-retention, aris, injection, multi-hop
- 基础数据集:HotpotQA
数据内容与结构
每个变体(config)对应一个数据子集。数据集中每一行包含四个字段:
| 字段 | 描述 |
|---|---|
question |
原始的HotpotQA多跳问题 |
clean_answer |
原始简短、清晰的正确答案 |
dataset_rewrite |
由确定性Python脚本重写后的答案 |
llm_rewrite |
由大语言模型gpt-oss:20b根据变体提示词重写后的答案 |
变体策略
每个变体都采用不同的转换策略对原始答案进行重写,旨在衡量每种策略削弱大语言模型提取正确答案能力的效果。部分主要策略包括:
- 位置掩埋:将正确答案放在句子中间或被无关信息包围。
- 干扰列表:将正确答案嵌入到一个包含多个干扰项(如相似名称、虚构条目)的列表中。
- 歧义注入:将正确答案描述为“主流”或“标准”解释,但暗示存在其他选择。
- 修饰与元评论:使用“几乎正确”、“可能是”等措辞弱化正确答案的确定性。
数据子集
该数据集包含138个数据子集,部分示例包括:all_mid_7, buried, cascade, ambigattr, shadow, negation, wiki, clean 等。所有子集均只包含 train 分片,数据文件格式为Parquet。
使用方法
您可以使用Hugging Face Datasets库加载数据:
python from datasets import load_dataset
加载一个变体
ds = load_dataset("cat-claws/hotpotqa-variants", "buried") print(ds["train"][0])
要列出所有配置,可以遍历 configs 字段。