poolside-laguna-hackathon/laguna-xs2-synthetic-training-data
收藏资源简介:
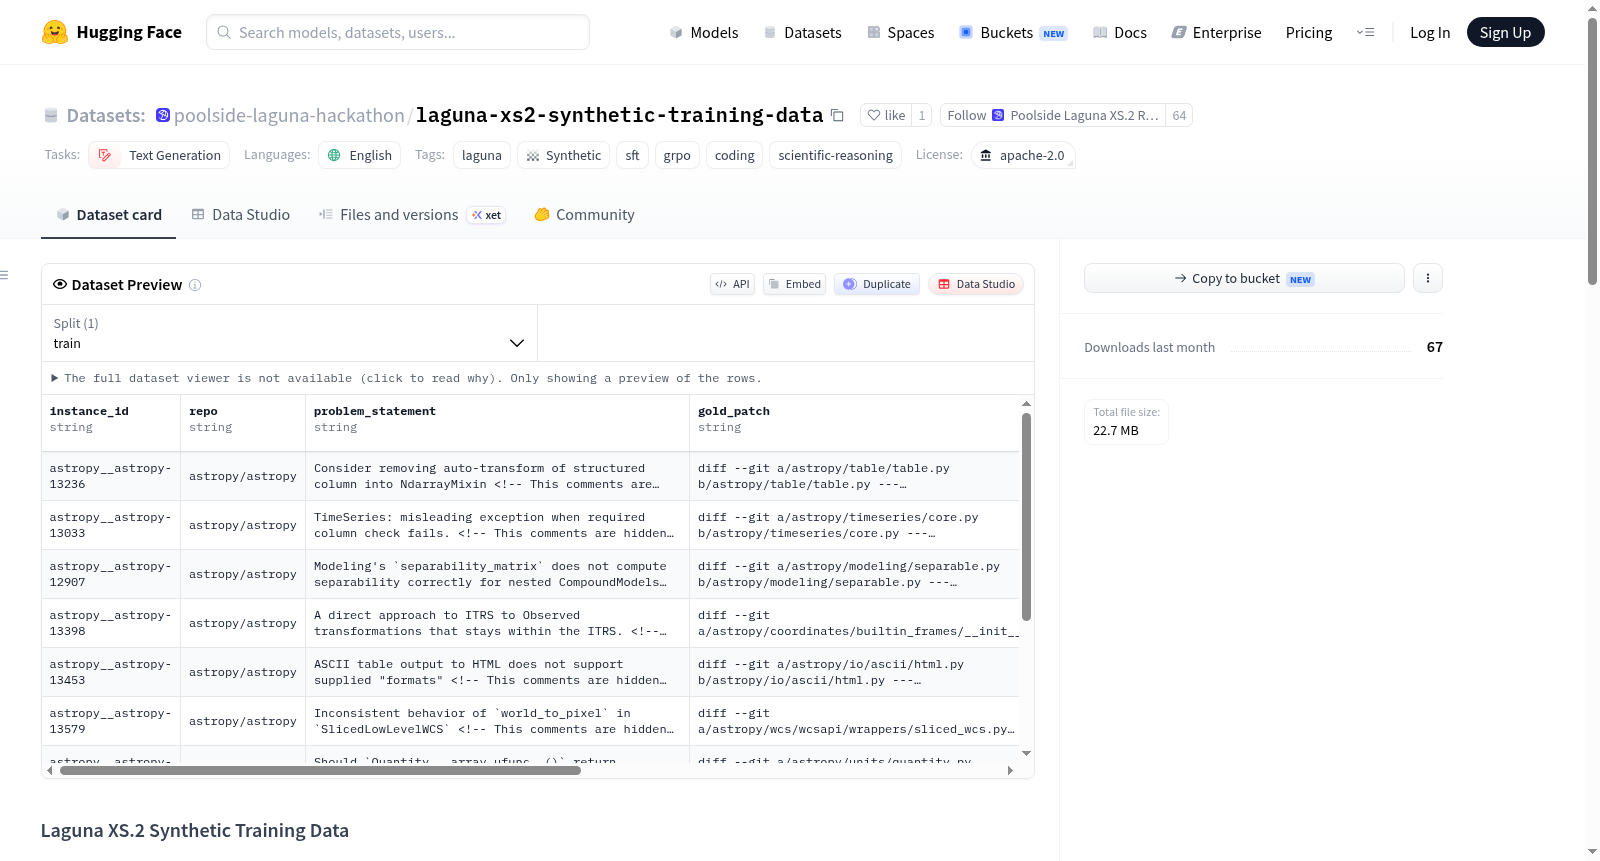
Laguna XS.2合成训练数据是一个用于改进Laguna XS.2模型在编码和科学推理任务上性能的合成数据集。该数据集是在Poolside Research Hackathon(2026年5月)中生成的。数据集包含两个主要部分:1) 编码部分:基于SWE-bench数据集,由Qwen3.6-35B-A3B教师模型生成的软件工程任务解决方案补丁,格式为JSONL,每个条目包括问题、教师生成的补丁和分数,适用于监督微调(SFT)或组策略优化(GRPO)训练;2) 科学部分:基于GPQA Diamond(研究生级科学问题)数据集,由AM-thinking-v1教师模型生成的思维链推理轨迹,格式为JSONL,每个条目包括问题、完整的推理轨迹和答案,适用于SFT训练,旨在提高模型在科学推理任务上的性能(在GPQA基准测试中测得42.6%的准确率)。数据集的生成动机是解决Laguna XS.2模型在GPQA Diamond(42.6%准确率,仅比随机高17.6%)和MATH500(46.6%准确率,在微积分和中级代数方面表现较弱)基准测试中的明显弱点。数据集的使用可以通过Python代码加载JSONL文件实现。
Laguna XS.2 Synthetic Training Data is a synthetic dataset generated to improve the Laguna XS.2 model on coding and scientific reasoning tasks. It was produced as part of the Poolside Research Hackathon in May 2026. The dataset consists of two main components: 1) Coding: SWE-bench coding trajectories generated by the Qwen3.6-35B-A3B teacher model, in JSONL format, each entry containing a problem, teacher solution patch, and score, suitable for SFT or GRPO training to enhance software engineering capabilities; 2) Scientific: GPQA Diamond reasoning traces generated by the AM-thinking-v1 teacher model, in JSONL format, each entry containing a question, full chain-of-thought reasoning trace, and answer, intended for SFT training to improve scientific reasoning performance (measured at 42.6% on GPQA). The motivation for creating this data is to address Laguna XS.2s weaknesses in benchmarks such as GPQA Diamond (42.6%, only 17.6% above random) and MATH500 (46.6%, with struggles in Precalculus and Intermediate Algebra). Usage involves loading the JSONL files with Python.