GroundCap
收藏资源简介:
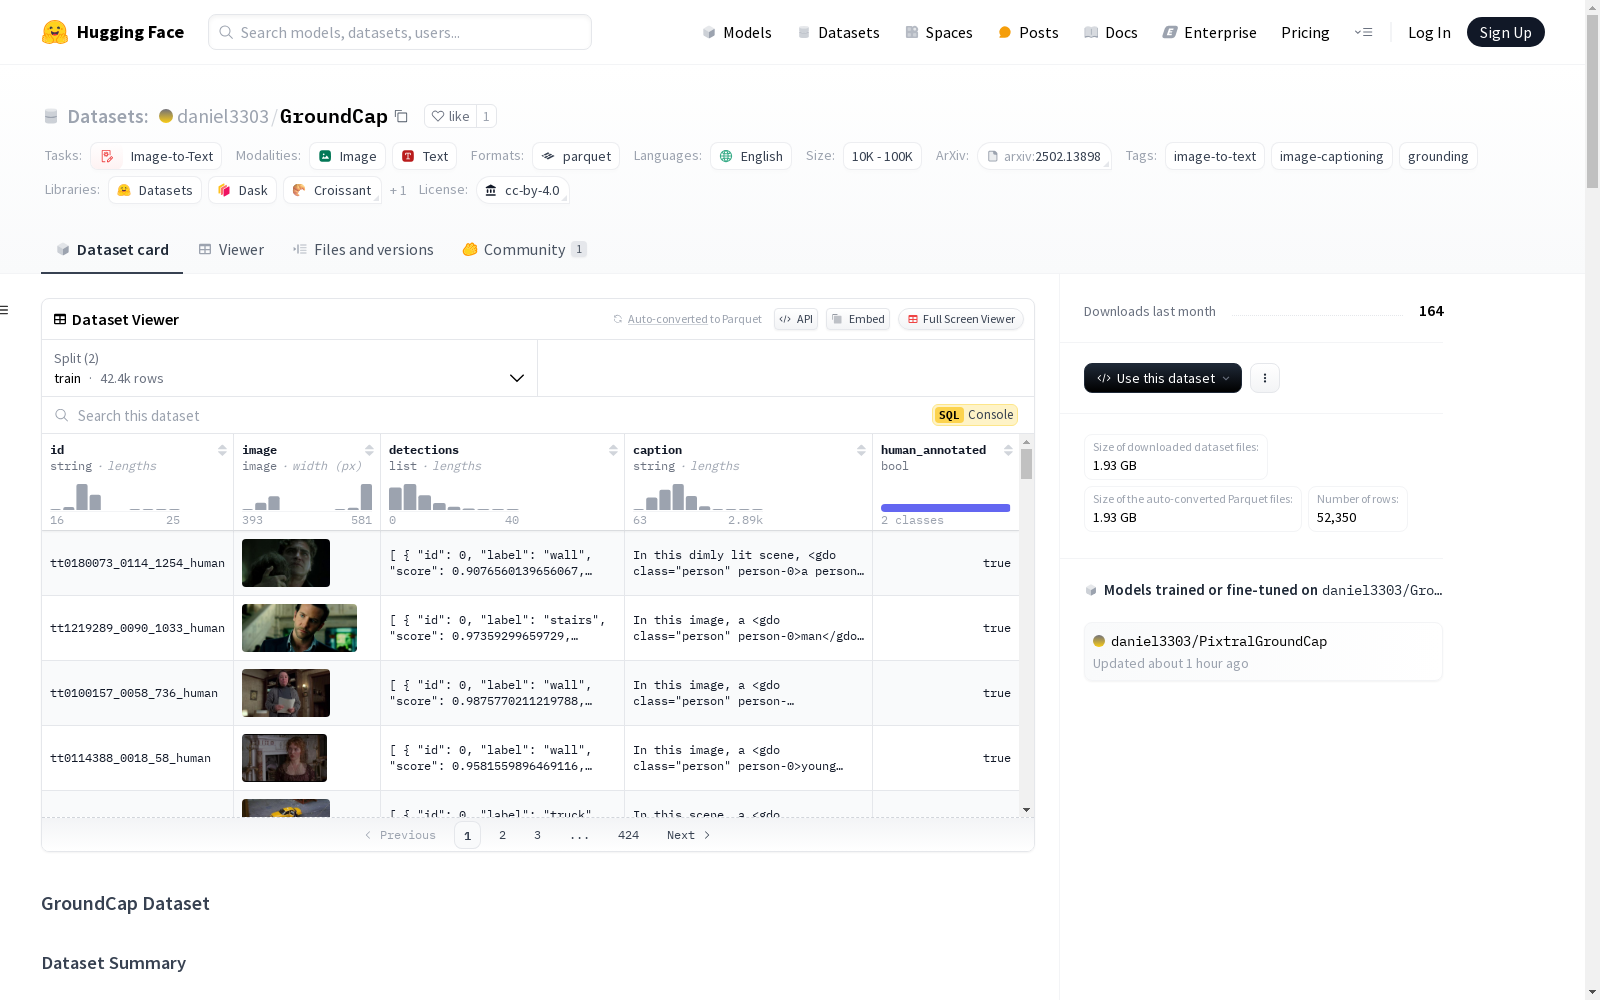
GroundCap是由INESC-ID Lisboa和Universidade de Lisboa的研究人员创建的一个视觉定位图像字幕数据集。该数据集包含来自77部电影的52,016张图像,其中包含344个由人类注释和52,016个自动生成的字幕。每个字幕都与检测到的对象(132个类别)和动作(51个类别)相关联,使用一个标签系统保持对象身份,同时将动作链接到相应的对象。该数据集旨在解决图像字幕系统中缺乏将描述性文本链接到特定视觉元素的问题。
GroundCap is a visual grounding image captioning dataset created by researchers from INESC-ID Lisboa and Universidade de Lisboa. It contains 52,016 images sourced from 77 films, paired with 344 human-annotated captions and 52,016 automatically generated captions. Each caption is associated with detected objects (132 categories) and actions (51 categories), adopting a labeling system that maintains object identities while linking actions to their corresponding objects. This dataset aims to address the limitation that existing image captioning systems lack the ability to connect descriptive text to specific visual elements.