Pradheep1647/tweet-style-dataset
收藏资源简介:
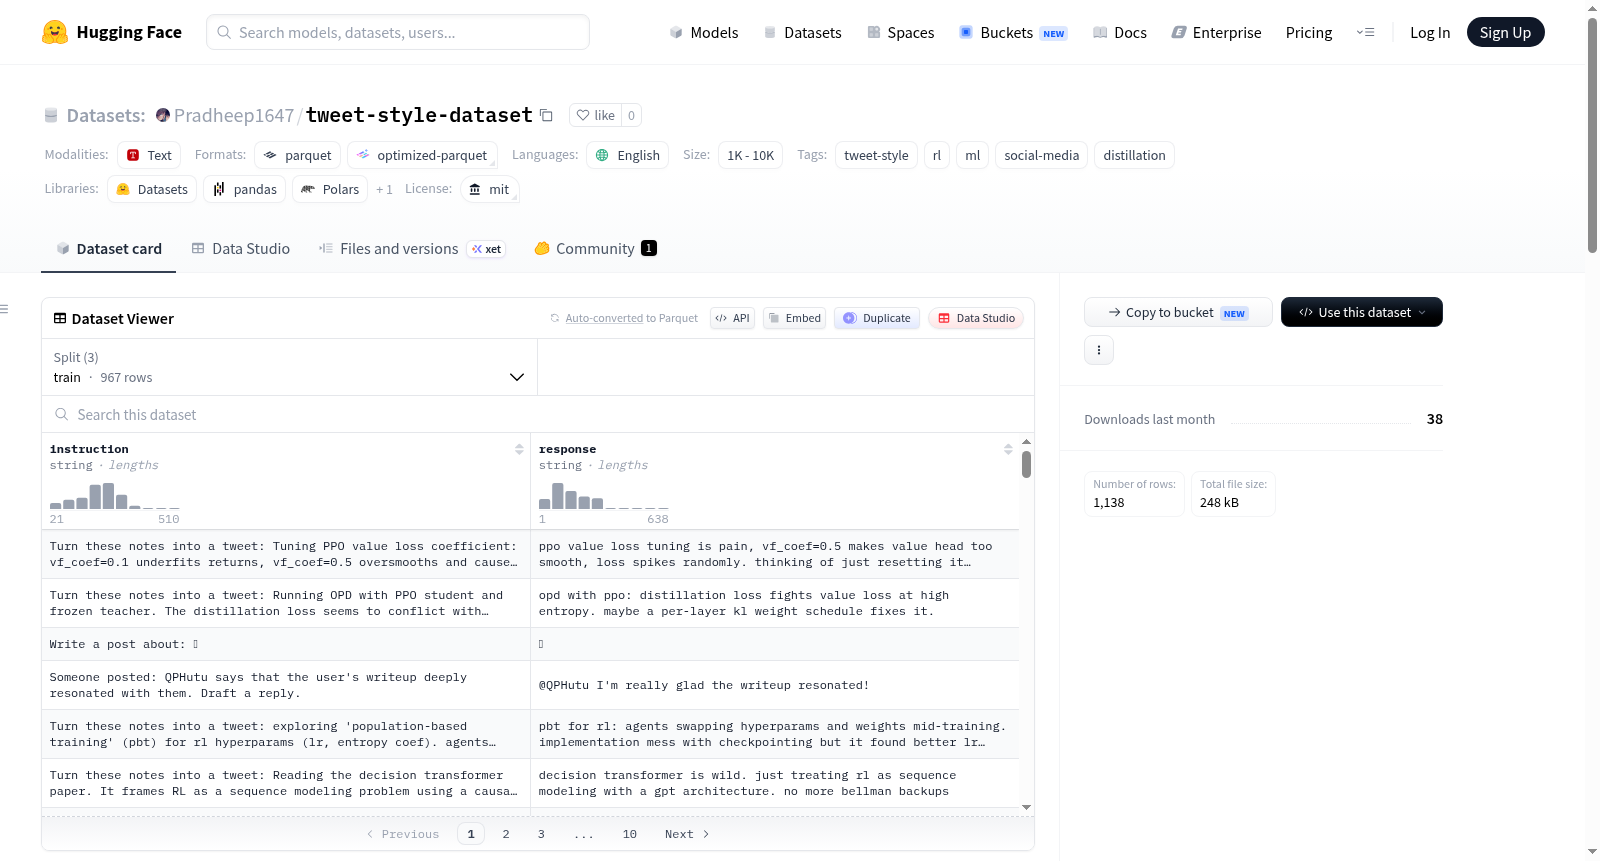
Tweet Style Dataset 是一个用于训练小型语言模型(SLM)的数据集,旨在通过基于策略的蒸馏方法,让模型学习模仿作者风格起草X/Twitter帖子。数据集基于作者@pradheepraop的Twitter档案导出(2025年9月至2026年5月),并通过DeepSeek v4(OpenRouter)生成的合成数据进行了丰富。它包括真实推文(经过丰富处理)、合成内容(从原始RL/ML笔记生成推文)和风格变体(对真实推文进行简洁和技术性重写),总计1,138条条目,分为训练集(967条)、验证集(85条)和测试集(86条)。数据模式包括instruction(任务提示,如将笔记转换为推文)和response(作者风格的推文响应)。数据集适用于监督微调(SFT)、基于策略的蒸馏(使用反向KL散度)和起草任务,帮助模型根据粗略笔记或主题生成具有作者随意/技术性声音的推文。
Tweet Style Dataset is a dataset for training a Small Language Model (SLM) to draft X/Twitter posts in the authors voice using on-policy distillation. It is built from a Twitter archive export of @pradheepraop (September 2025 – May 2026), enriched with synthetic data generated via DeepSeek v4 (OpenRouter). The dataset includes real tweets (enriched with prompts), synthetic content (generated from raw RL/ML notes to tweets), and style variants (concise and technical rewrites of real tweets), totaling 1,138 entries split into train (967 rows), validation (85 rows), and test (86 rows). The schema consists of instruction (task prompts such as converting notes to tweets) and response (tweet in the authors voice). It is intended for supervised fine-tuning (SFT), on-policy distillation with reverse-KL, and drafting tasks to generate tweets in the authors casual/technical style from rough notes or topics.