
He-Xingwei/ConIR
收藏官方服务:
资源简介:
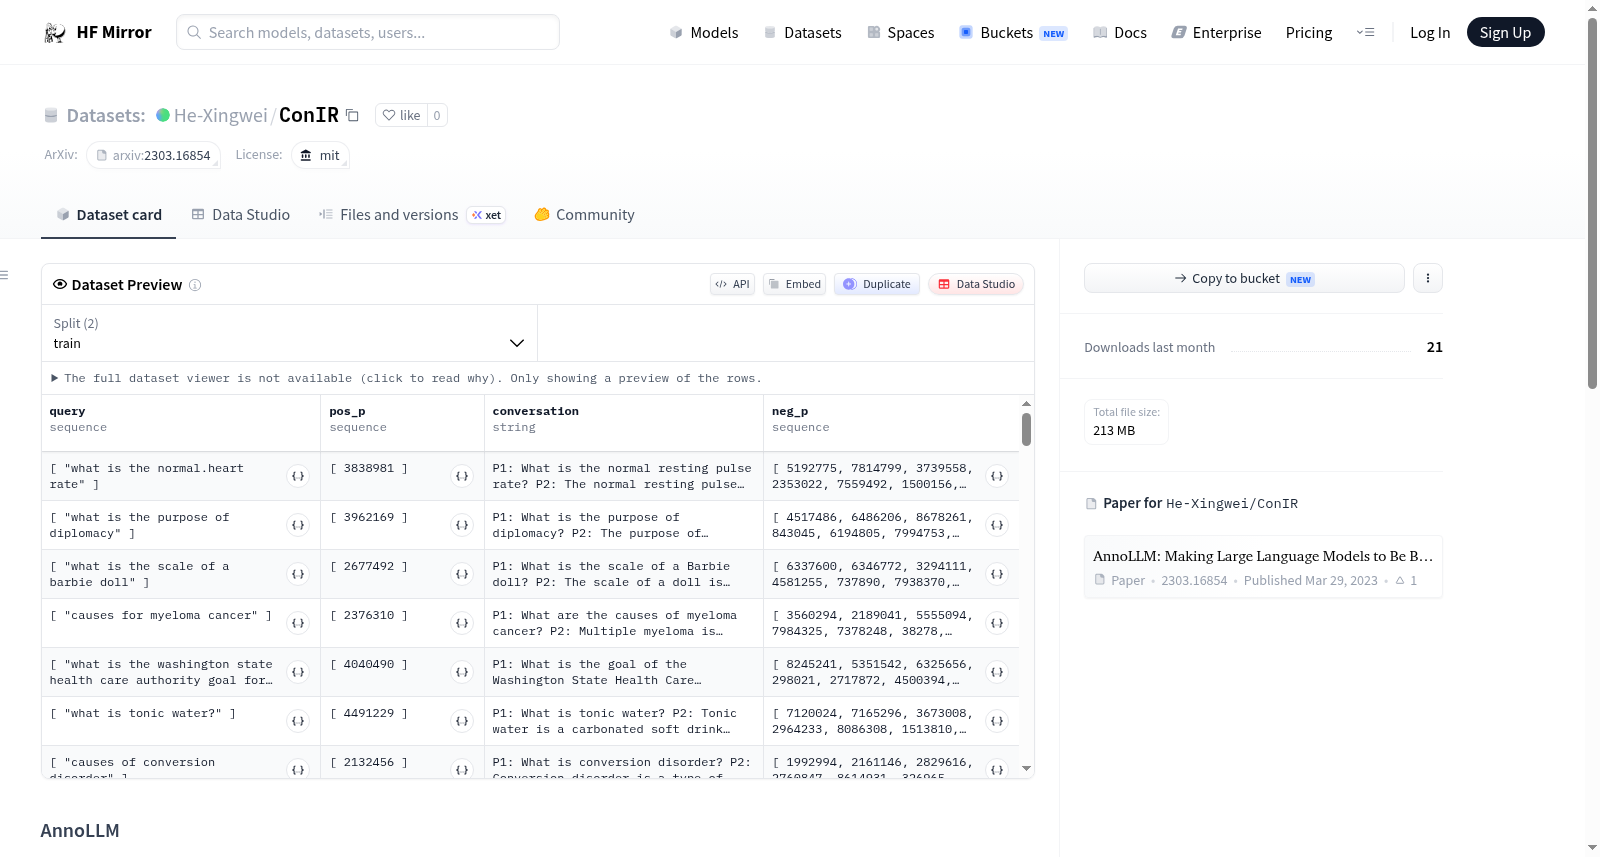
ConIR数据集是一个基于对话的信息检索数据集,由ChatGPT根据MS-MARCO段落排名数据集创建。该数据集包含训练集和测试集,大小分别为71,557和3,000。数据集中的每个查询来自MS-MARCO,每个查询对应一组正向和负向段落ID,以及由ChatGPT生成的对话内容。该数据集用于NAACL 2024论文,并遵循MIT许可。
The ConIR dataset is a dialogue-based information retrieval dataset created by ChatGPT based on the MS-MARCO passage ranking dataset. It includes training and test splits with sizes of 71,557 and 3,000 respectively. Each query in the dataset is sourced from MS-MARCO, and each query corresponds to a set of positive and negative passage IDs, alongside dialogue content generated by ChatGPT. This dataset was utilized in the NAACL 2024 paper and is released under the MIT License.
提供机构:
He-Xingwei原始信息汇总
数据集概述
数据集名称
- ConIR Dataset
数据集来源
- 由ChatGPT基于MS-MARCO passage ranking dataset创建。
数据集链接
数据集大小
- 训练集:71,557条记录
- 测试集:3,000条记录
数据集内容
- Attribute | Type | Description
- query | List[String] | 从MS-MARCO提取的查询语句
- pos_p | List[Integer] | 查询/对话的正例文章ID
- conversation | String | 基于正例文章由ChatGPT生成的对话
- neg_p | List[Integer] | 查询/对话的负例文章ID
许可协议
- MIT License
搜集汇总
数据集介绍
背景与挑战
背景概述
ConIR数据集是一个对话式信息检索数据集,基于MS-MARCO passage ranking数据集构建,通过ChatGPT生成对话内容,旨在提升大语言模型作为众包标注者的能力。数据集包含71,557条训练样本和3,000条测试样本,每个样本包括查询、正负段落ID和生成的对话文本,但当前存在数据生成错误,导致列不匹配问题。
以上内容由遇见数据集搜集并总结生成


