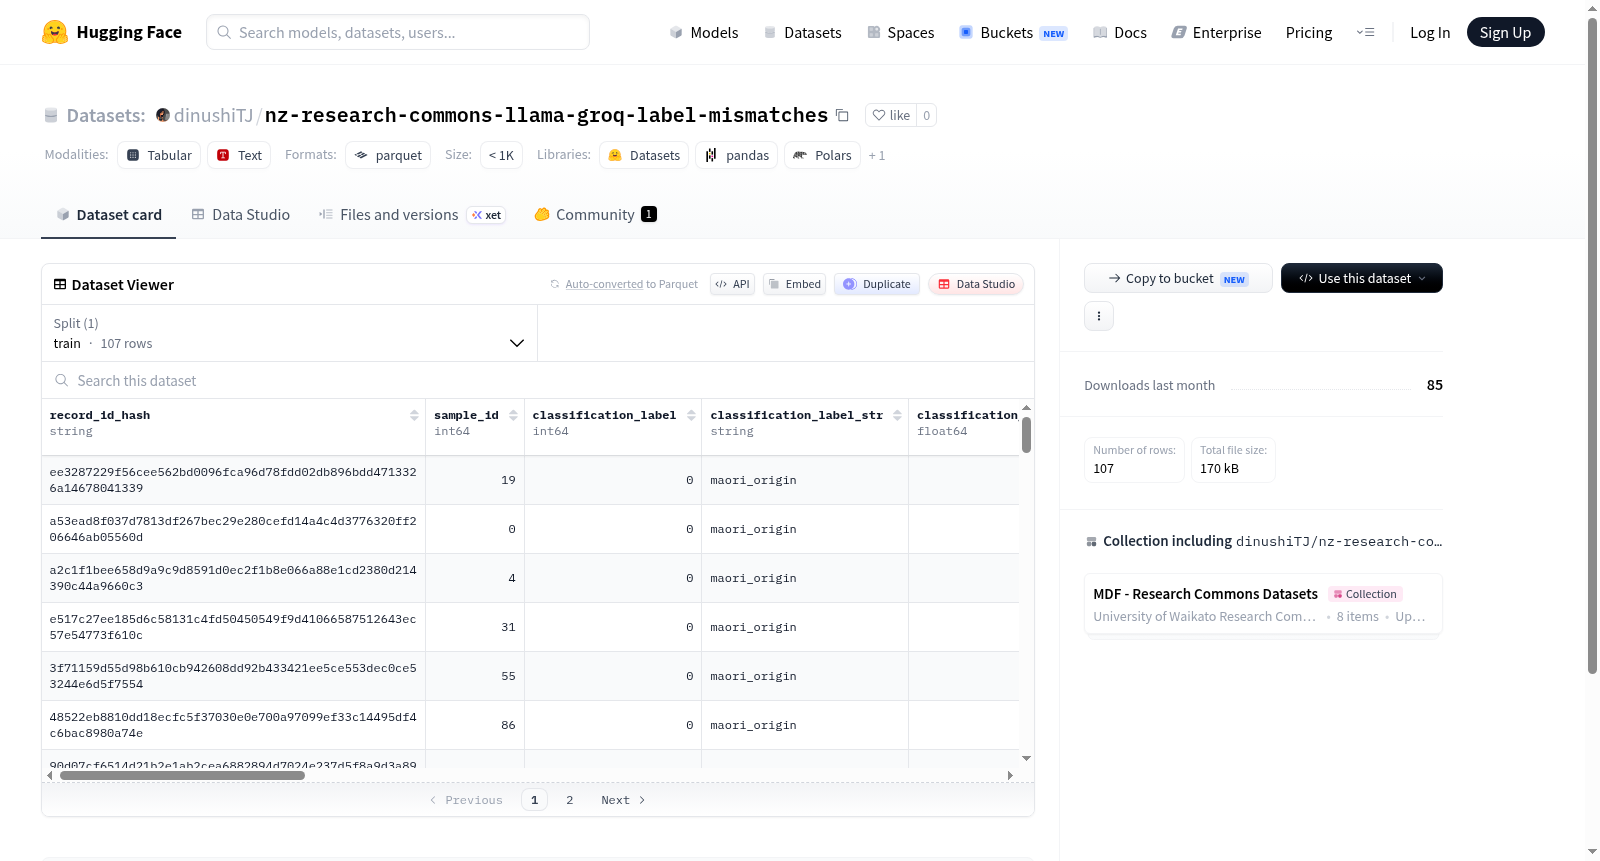
nz-research-commons-llama-groq-label-mismatches
收藏资源简介:
该数据集包含用于学术论文分类任务评估的数据,由104个样本组成,涵盖论文的元数据信息,包括标题、作者、年份、主题和摘要。核心内容涉及两种分类体系:一种基于预设的分类标签(包含数值标签、字符串标签、置信度及分类原因),另一种基于LLaMA模型生成的分类结果(包含标签、置信度、原因及可能的错误信息)。此外,数据集提供了用于模型比较的评估指标,如精确匹配结果、对比提供方、对比模型、对比类型、提示词版本、样本类型、每类样本数量及随机种子。该数据集适用于自然语言处理中的文本分类模型性能评估、大语言模型(如LLaMA)在学术领域的分类能力分析,以及不同分类方法或模型之间的对比研究。
This dataset contains data for evaluating academic paper classification tasks, consisting of 104 samples that cover metadata information such as title, author, year, topic, and abstract. The core content involves two classification systems: one based on preset classification labels (including numerical labels, string labels, confidence scores, and classification reasons), and another based on classification results generated by the LLaMA model (including labels, confidence scores, reasons, and possible error information). Additionally, the dataset provides evaluation metrics for model comparison, such as exact match results, comparison providers, comparison models, comparison types, prompt versions, sample types, number of samples per category, and random seeds. This dataset is suitable for evaluating the performance of text classification models in natural language processing, analyzing the classification capabilities of large language models (e.g., LLaMA) in the academic domain, and conducting comparative studies between different classification methods or models.
数据集概述
- 数据集名称:dinushiTJ/nz-research-commons-llama-groq-label-mismatches
- 数据集链接:https://huggingface.co/datasets/dinushiTJ/nz-research-commons-llama-groq-label-mismatches
- 数据集大小:下载大小为 166027 字节,数据集大小为 276226 字节
- 数据集划分:仅包含一个训练集(train),共 107 个样本
数据特征
该数据集包含以下 23 个特征字段:
| 字段名 | 数据类型 | 描述 |
|---|---|---|
| record_id_hash | string | 记录 ID 哈希值 |
| sample_id | int64 | 样本 ID |
| classification_label | int64 | 分类标签(数值) |
| classification_label_str | string | 分类标签(字符串) |
| classification_confidence | float64 | 分类置信度 |
| classification_reason | string | 分类理由 |
| title | string | 标题 |
| authors | string | 作者 |
| year | string | 年份 |
| subjects | string | 主题 |
| abstract | string | 摘要 |
| llama_label | string | Llama 模型输出的标签 |
| llama_confidence | float64 | Llama 模型输出的置信度 |
| llama_reason | string | Llama 模型输出的理由 |
| llama_error | null | Llama 模型错误信息(为空) |
| exact_match | bool | 是否精确匹配 |
| comparison_provider | string | 比较提供方 |
| comparison_model | string | 比较模型 |
| comparison_type | string | 比较类型 |
| prompt_version | string | 提示版本 |
| sample_type | string | 样本类型 |
| n_per_class | int64 | 每类样本数量 |
| random_seed | int64 | 随机种子 |
数据用途
该数据集主要用于比较和评估 Llama 模型(来自 Groq)与原始分类标签之间的差异,特别是标签不匹配(label mismatches)的情况。通过 classification_label 与 llama_label、exact_match 等字段,可以分析模型预测与原始标签的一致性和差异原因。