stackexchange-tezos-sandboxes-verified
收藏资源简介:
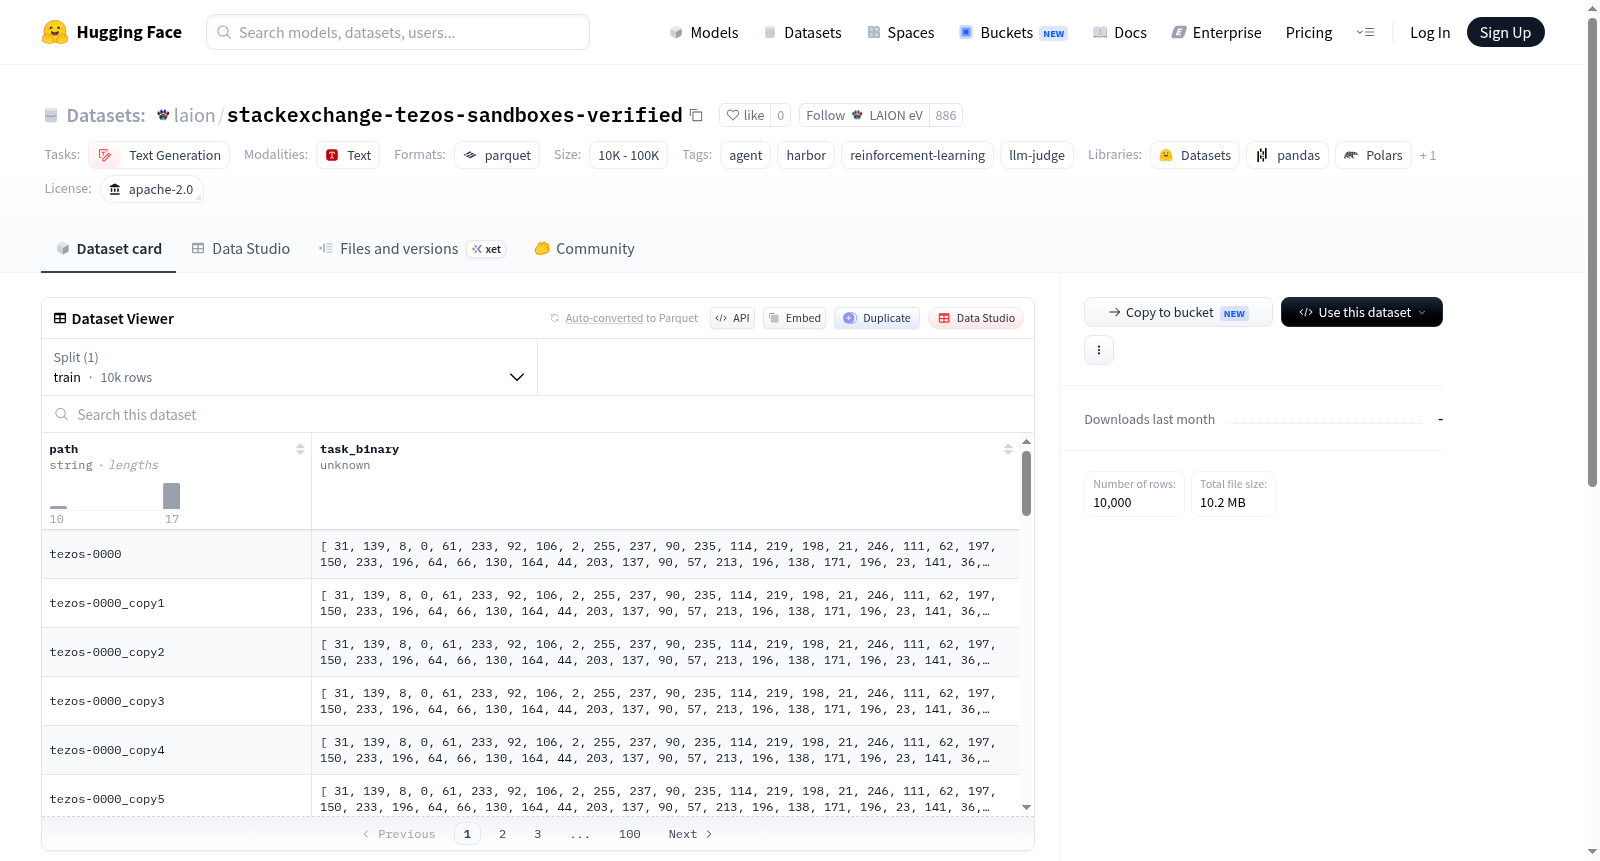
该数据集名为laion/stackexchange-tezos-sandboxes-verified,是一个包含10,000个任务的Harbor任务二进制数据集,遵循规范的Harbor/TaskTrove任务模式。数据集中的计算机使用任务源自Tezos StackExchange的问题,涵盖Tezos节点/面包师操作、加密货币/区块链概念、钱包和智能合约等相关主题。该数据集是DCAgent/stackexchange-tezos-sandboxes-skywork-response的重新打包版本,保留了原有的instruction.md和共享的ubuntu:24.04环境。每个任务沙箱都集成了从OpenThoughts-Agent框架移植的LLM-judge验证器,用于替代原始的Skywork奖励模型验证器。在验证阶段,系统会读取代理的响应文件以及包含任务指令和适应性评分标准的验证数据,通过litellm调用LLM法官(默认使用openai/gpt-4o-mini)进行自动评估,并将0.0-1.0范围的奖励分数写入日志文件。数据集使用需要配置OPENAI_API_KEY环境变量,其评分标准专门针对Tezos/区块链节点操作员请求,评估维度包括正确性、完整性、相关性和操作稳健性。
The dataset named laion/stackexchange-tezos-sandboxes-verified is a Harbor task binary dataset containing 10,000 tasks, following the standardized Harbor/TaskTrove task pattern. The computer usage tasks in the dataset are derived from questions on Tezos StackExchange, covering topics such as Tezos node/baker operations, cryptocurrency/blockchain concepts, wallets, and smart contracts. This dataset is a repackaged version of DCAgent/stackexchange-tezos-sandboxes-skywork-response, retaining the original instruction.md and the shared ubuntu:24.04 environment. Each task sandbox integrates an LLM-judge validator transplanted from the OpenThoughts-Agent framework, replacing the original Skywork reward model validator. During the verification phase, the system reads the agents response files along with verification data containing task instructions and adaptive scoring criteria, automatically evaluates them by calling an LLM judge (defaulting to openai/gpt-4o-mini) via litellm, and writes reward scores in the range of 0.0-1.0 to log files. Dataset usage requires configuring the OPENAI_API_KEY environment variable, and its scoring criteria are specifically designed for Tezos/blockchain node operator requests, with evaluation dimensions including correctness, completeness, relevance, and operational robustness.
数据集概述:laion/stackexchange-tezos-sandboxes-verified
- 许可证:Apache-2.0
- 任务类别:文本生成(text-generation)
- 标签:agent、harbor、reinforcement-learning、llm-judge
数据集内容
- 包含 10,000 个任务,遵循 Harbor / TaskTrove 任务模式。
- 每个任务包含两个列:
path(字符串类型)和task_binary(gzip tar 格式)。 - 任务来源于 Tezos 相关的 StackExchange 问题,涵盖 Tezos 节点/烘焙者操作、加密货币/区块链概念、钱包、合约等主题。
- 数据从
DCAgent/stackexchange-tezos-sandboxes-skywork-response重新打包而来,保留了instruction.md和共享的ubuntu:24.04环境。
验证机制
- 每个任务的沙箱环境内置了一个 LLM 评判验证器,该验证器移植自 OpenThoughts-Agent 的
data.nemotron_gym框架(verifiers/llm_judge.py),替代了原 Skywork 奖励模型验证器。 - 验证时,
tests/test_state.py读取 agent 的/app/response.txt以及/tests/verifier_data.json(包含任务指令和适配的评分标准),通过litellm调用 LLM 评判(默认模型为openai/gpt-4o-mini),并将 0.0 到 1.0 之间的奖励写入/logs/verifier/reward.txt。 - 运行时需要设置
OPENAI_API_KEY,该密钥通过task.toml的[verifier].env传播至验证器容器;可通过JUDGE_MODEL可选覆盖评判模型。
评分标准(Tezos 主题)
- 针对 Tezos/区块链节点运营者的请求,从以下四个维度进行评分:
- 正确性(correctness)
- 完整性(completeness)
- 相关性(relevance)
- 操作合理性(operational soundness)