Speech Emotion Recognition Adaptation Benchmark (SERAB)
收藏资源简介:
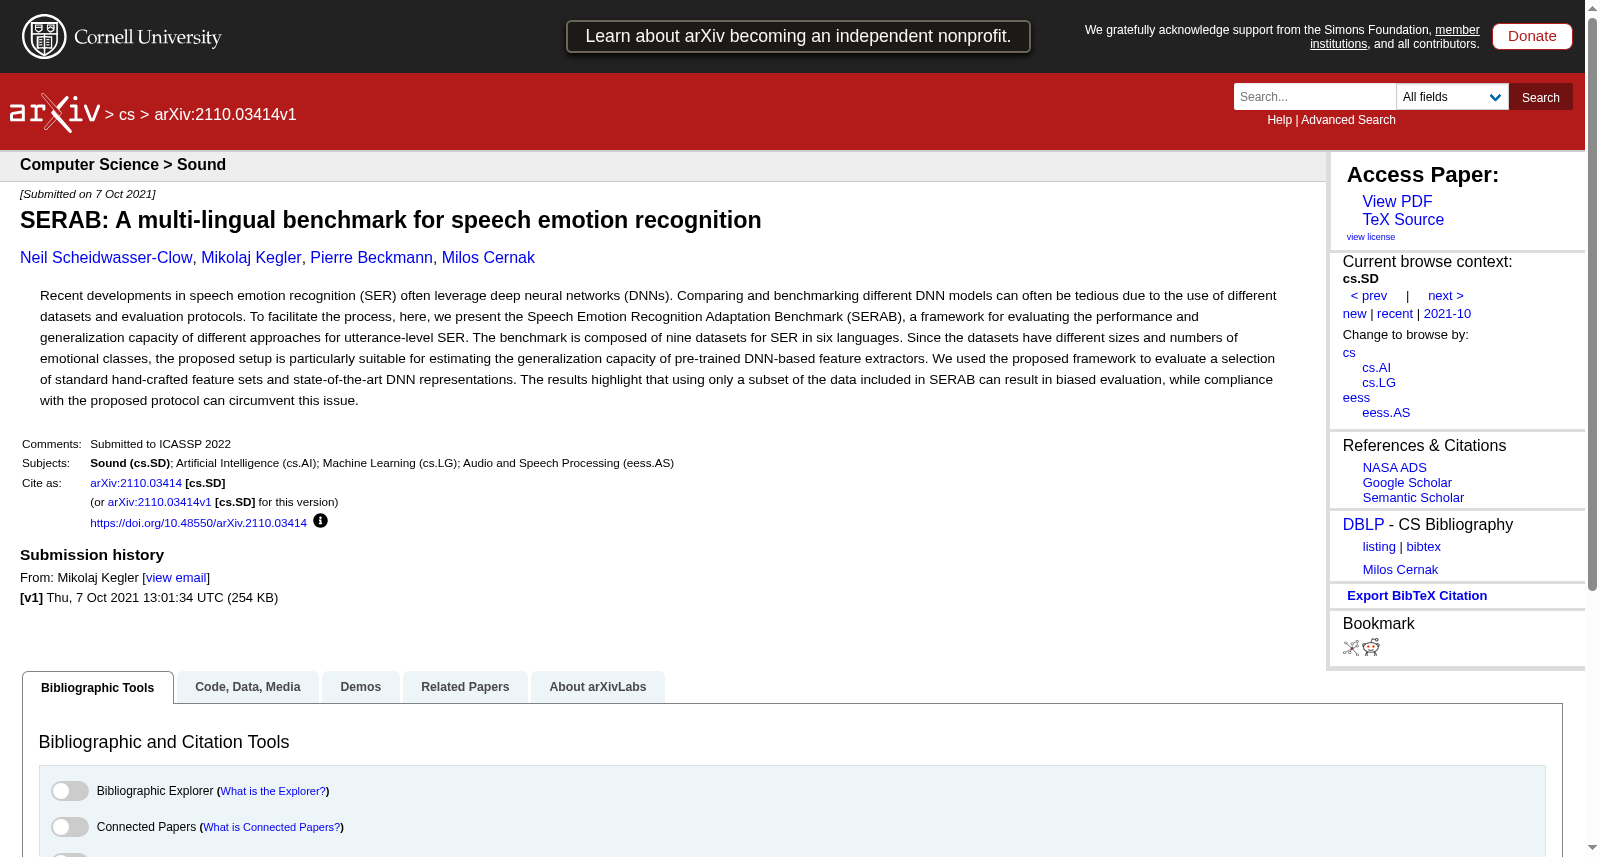
Speech Emotion Recognition Adaptation Benchmark (SERAB) 是一个多语言的语音情感识别基准,由洛桑联邦理工学院等机构创建。该数据集包含九个子数据集,覆盖六种语言,旨在评估不同语音情感识别方法的性能和泛化能力。数据集大小、情感类别数量各异,适用于评估预训练深度神经网络特征提取器的泛化能力。SERAB 的应用领域广泛,包括人机交互、医疗健康和公共安全等,旨在解决自动准确分类语音中情感的挑战。
Speech Emotion Recognition Adaptation Benchmark (SERAB) is a multilingual speech emotion recognition benchmark developed by institutions including the École Polytechnique Fédérale de Lausanne (EPFL). This dataset consists of nine sub-datasets spanning six languages, designed to evaluate the performance and generalization capability of diverse speech emotion recognition methods. The sub-datasets vary in scale and number of emotion categories, making them suitable for assessing the generalization ability of pre-trained deep neural network-based feature extractors. SERAB has broad application domains, including human-computer interaction, healthcare, public safety and more, aiming to address the challenge of automatically and accurately classifying emotions in speech.