BCCard/gemma-4-31B-korean-on-policy-150k
收藏资源简介:
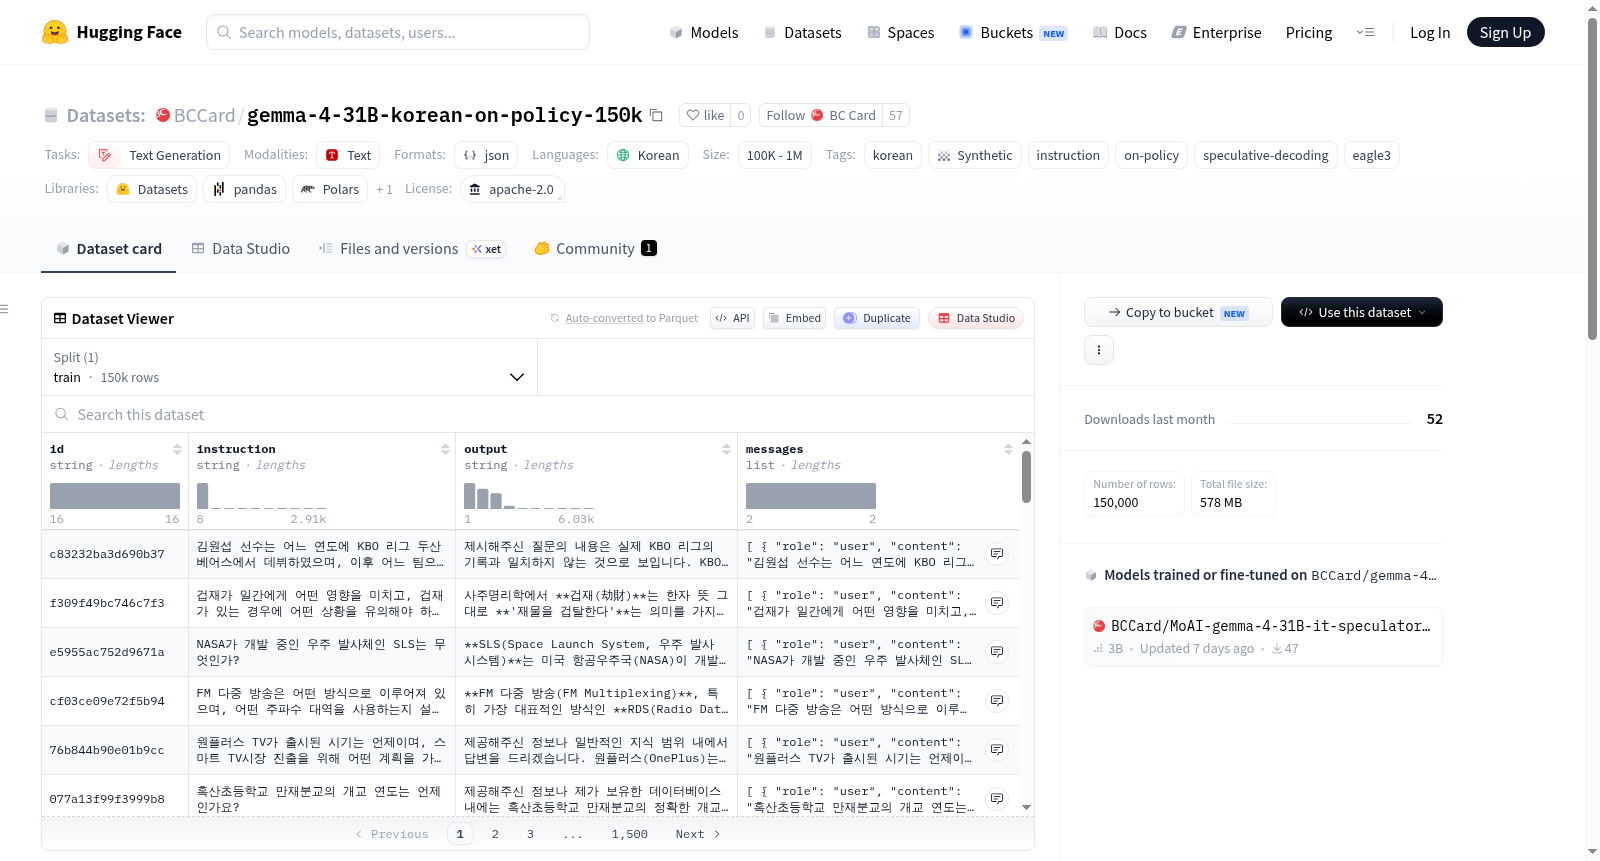
--- license: apache-2.0 language: - ko task_categories: - text-generation tags: - korean - synthetic - instruction - on-policy - speculative-decoding - eagle3 size_categories: - 100K<n<1M pretty_name: Korean On-Policy QA for Gemma 4 EAGLE-3 configs: - config_name: default data_files: - split: train path: data/*.jsonl --- # Korean On-Policy QA (Gemma 4) — EAGLE-3 training data Korean instruction/response pairs where the **responses were regenerated on-policy by a Gemma 4 verifier**. Originally built to retrain an EAGLE-3 speculator for Korean, but also usable for general Korean instruction-tuning / distillation. ## Structure - **Rows**: ~150,000 - **Language**: Korean - **Columns**: - `instruction` (string) — the question / instruction - `output` (string) — the verifier-generated response - `messages` (list) — chat format `[{"role":"user",...},{"role":"assistant",...}]` - **Split**: `train` ## How it was made - **Prompt source**: [sh2orc/bccard-maywell-jojo0217-markai-lcw99-kendamarron-microsoft](https://huggingface.co/datasets/sh2orc/bccard-maywell-jojo0217-markai-lcw99-kendamarron-microsoft) (1.71M-row Korean QA). Only the `instruction` column was sampled (~150k); **the original answers were discarded.** - **Response regeneration**: responses generated on-policy by `<VERIFIER>`. - e.g. `RedHatAI/gemma-4-26B-A4B-it-FP8-Dynamic` or `BCCard/gemma-4-31B-it-FP8-Dynamic` - thinking off; temperature 1.0 / top-p 0.95 / top-k 64 (aligned to the serving distribution); text-only. > Fill in: replace `<VERIFIER>` above with the exact verifier model you used, and note the sampling seed. ## Usage ```python from datasets import load_dataset ds = load_dataset("<this-repo-id>", split="train") print(ds[0]["instruction"], ds[0]["output"]) ``` ## License / provenance **Apache 2.0**. Both the prompt-source dataset (Apache 2.0) and the response-generating model Gemma 4 (Apache 2.0) are Apache 2.0. The responses are **synthetic data** generated by Gemma 4; original attribution of the source dataset is retained. (Informational, not legal advice.)
Korean instruction/response pairs where the responses were regenerated on-policy by a Gemma 4 verifier. Originally built to retrain an EAGLE-3 speculator for Korean, but also usable for general Korean instruction-tuning / distillation. The dataset structure includes approximately 150,000 rows in Korean, with columns: instruction (string) for the question/instruction, output (string) for the verifier-generated response, and messages (list) in chat format [{"role":"user",...},{"role":"assistant",...}]. It was created by sampling instructions from a source dataset and discarding original answers, then generating responses using a specified verifier model under parameters like temperature 1.0, top-p 0.95, top-k 64. Only the train split is available, and it is licensed under Apache 2.0, with synthetic responses generated by Gemma 4.