legal-corpus-raw-batches
收藏资源简介:
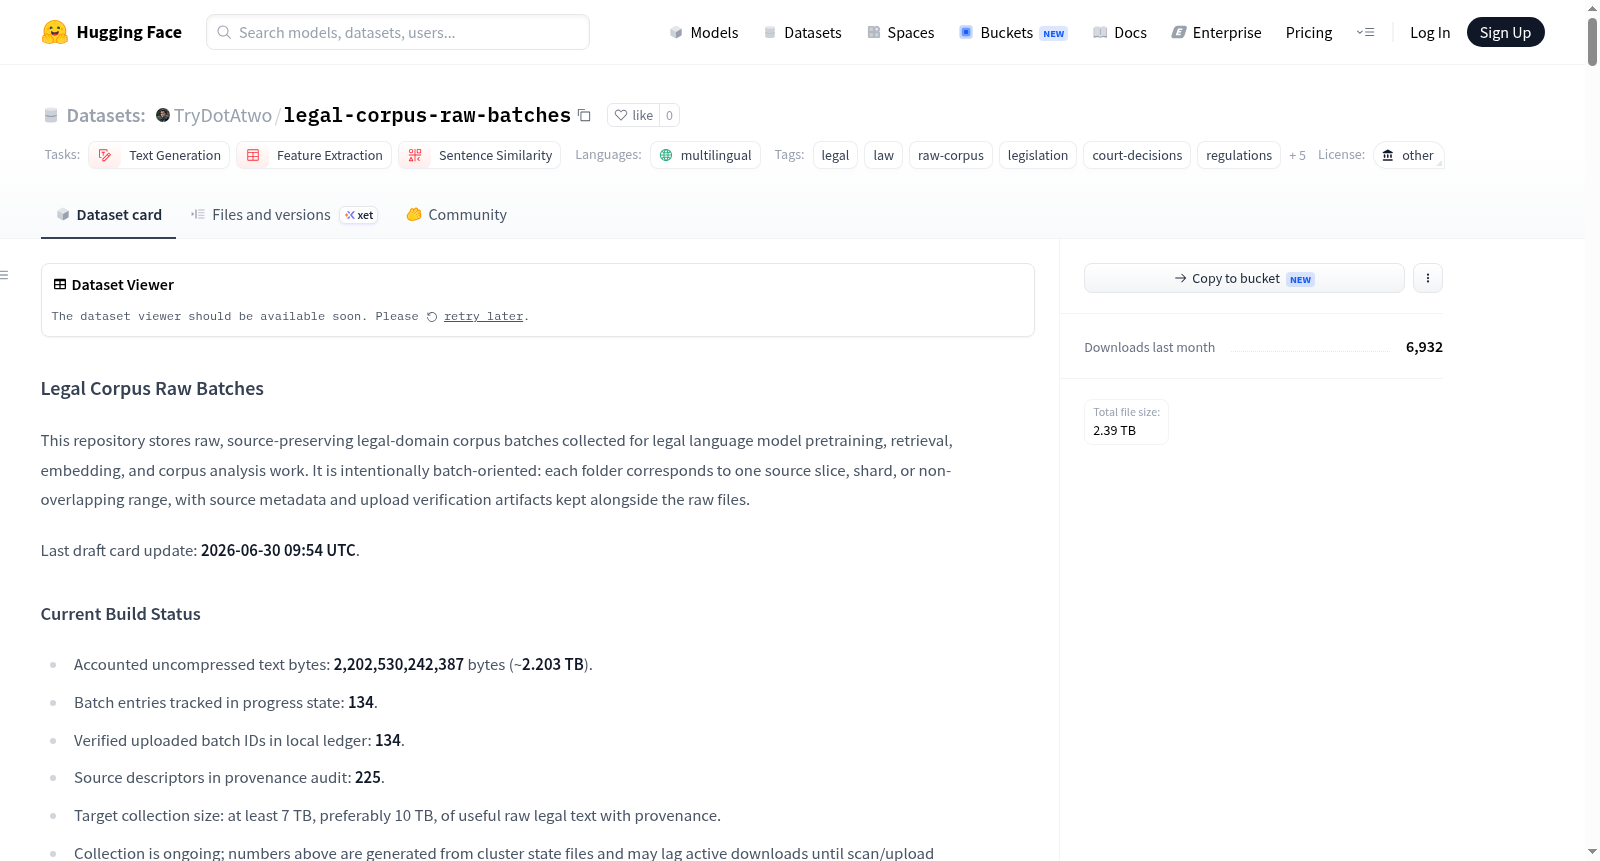
Legal Corpus Raw Batches 是一个大规模、多语言、专注于法律领域的原始语料库集合,旨在为法律语言模型预训练、信息检索、文本嵌入和语料分析提供基础数据。该数据集采用批次化组织方式,每个批次文件夹对应特定的数据源切片、分片或非重叠数据范围,并完整保留了来源元数据和上传验证信息以确保可追溯性。内容涵盖立法、法规、公共法律、法院判决、行政材料、法律文件、合同、专利/监管知识产权材料以及多语言/平行法律语料库等多种法律文本类型。数据收集避免了已知的重复源范围、纯嵌入数据集、仅分词/掩码数据、缺乏原始法律文本的纯问答数据集以及来源信息不足的数据。当前包含约2.203 TB的未压缩文本(约2,202,530,242,387字节),包含134个已追踪和验证的批次条目,涉及225个来源描述符,目标收集规模至少7 TB,理想情况下达到10 TB的有用原始法律文本。数据根据质量分为三个层级:核心法律文本(core_legal)、监管合同与知识产权(regulatory_contracts_ip)和法律网络候选文本(legal_web_candidate)。数据集包含来自多个主要来源家族的数据,例如美国联邦公报API、美国证券交易委员会EDGAR文件、西班牙官方国家公报(BOE)立法、法院记录档案、美国政府信息网站(govinfo)的联邦法规汇编(CFR)和公法(plaw)、CommonCrawl法律文本、案例法批量数据、平行立法、监管文件与合同、多语言法律语料库等,覆盖了包括英语、中文、西班牙语、法语、德语、荷兰语、捷克语、加泰罗尼亚语、哈萨克语、俄语在内的多种语言。每个批次都附有最小元数据规范,包括来源ID、URL、类型、质量等级、许可证、来源家族、去重键等,并尽可能保留源生元数据。
Legal Corpus Raw Batches is a large-scale, multilingual, and law-focused raw corpus collection designed to provide foundational data for legal language model pre-training, information retrieval, text embedding, and corpus analysis. The dataset is organized in batches, where each batch folder corresponds to a specific data source slice, shard, or non-overlapping data range, with complete retention of source metadata and upload verification information to ensure traceability. The content covers various legal text types, including legislation, regulations, public laws, court judgments, administrative materials, legal documents, contracts, patent/regulatory intellectual property materials, and multilingual/parallel legal corpora. The data collection process avoids known duplicate source ranges, pure embedding datasets, tokenized/masked-only data, pure Q&A datasets lacking original legal texts, and data with insufficient source information. It currently contains approximately 2.203 TB of uncompressed text (about 2,202,530,242,387 bytes), with 134 tracked and verified batch entries, involving 225 source descriptors, and aims to collect at least 7 TB, ideally reaching 10 TB of useful raw legal text. The data is divided into three quality tiers: core legal texts (core_legal), regulatory contracts and intellectual property (regulatory_contracts_ip), and legal web candidate texts (legal_web_candidate). The dataset includes data from multiple major source families, such as the U.S. Federal Register API, U.S. Securities and Exchange Commission EDGAR filings, Spanish Official State Gazette (BOE) legislation, court record archives, U.S. Government Information Website (govinfo) for the Code of Federal Regulations (CFR) and public laws (plaw), CommonCrawl legal texts, case law bulk data, parallel legislation, regulatory documents and contracts, and multilingual legal corpora, covering languages including English, Chinese, Spanish, French, German, Dutch, Czech, Catalan, Kazakh, and Russian. Each batch includes minimal metadata specifications, such as source ID, URL, type, quality level, license, source family, deduplication key, etc., and retains native metadata as much as possible.
数据集概述:Legal Corpus Raw Batches
- 数据集名称: Legal Corpus Raw Batches
- 数据集地址:
https://huggingface.co/datasets/TryDotAtwo/legal-corpus-raw-batches - 许可证: other
- 任务类别: text-generation, feature-extraction, sentence-similarity
- 语言: multilingual
- 标签: legal, law, raw-corpus, legislation, court-decisions, regulations, contracts, sec-filings, provenance, metadata, multilingual
- 数据集大小: 1T<n<10T
数据集内容与用途
该数据集是一个大规模、原始的、保留来源的法律领域语料库集合,旨在用于法律语言模型的预训练、检索、嵌入和语料库分析。数据集以批次(batch)为导向进行组织,每个文件夹对应一个特定的来源切片、分片或不重叠的范围。
包含内容:
- 立法文本、法规、公共法律
- 法院判决、行政材料、法律文件
- 合同、专利/监管知识产权材料
- 多语言/平行法律语料库(当上游来源和条款被保留时)
不包含内容:
- 已知的重复来源范围
- 仅嵌入的数据集
- 仅经过分词或掩码处理的数据
- 仅包含问答而不含原始法律文本的数据集
- 受限或失败的数据源
- 缺乏足够来源信息以进行后续审计的数据
数据规模与构建状态
- 当前未压缩文本字节数: 约 2.203 TB (2,202,530,242,387 bytes)
- 目标收集规模: 至少 7 TB,最佳目标为 10 TB
- 跟踪的批次条目: 134 个
- 已验证上传的批次: 134 个
- 来源描述符: 225 个
- 数据收集为进行中状态,上述数字基于集群状态文件生成
来源与元数据政策
每个接受的批次都会保留尽可能多的元数据。至少,批次规格和清单会追踪以下字段:
source_id,source_url,source_type,quality_tier,licensesource_family,dedupe_key, batch ID- 命令参数、上传状态、清理状态
当可用时,还会保留来源的原生元数据,例如:
- 联邦公报(Federal Register)文档元数据
- govinfo 的 URL/年份/标题/卷号/国会/公共法律元数据
- Hugging Face 数据集仓库元数据
- 文件清单、校验和、批次清单
用于生成当前状态的审计文件:
state/provenance_audit.jsonlstate/provenance_audit_summary.jsonstate/text_bytes_progress.jsonstate/hf_uploads.jsonl
质量等级
数据分为三个质量等级:
- core_legal: 173 个来源描述符
- regulatory_contracts_ip: 27 个来源描述符
- legal_web_candidate: 25 个来源描述符
主要来源家族
数据集包含多个主要来源家族,每个家族包含不同数量的来源描述符。以下为部分列举:
federal_register_api_recent: 24hf_sec_edgar_filings_parquet: 12spain_boe_consolidated_legislation: 12hf_court_records_split_archive: 9govinfo_cfr: 7govinfo_plaw: 7commoncrawl_legal_wet_text: 5hf_caselaw_bulk: 3parallel_legislation: 2regulatory_filings_contracts: 2court_bulk: 2hf_multilingual_legal_corpus: 2official_legislation_xml: 2hf_court_records_archive: 2legislation: 1legislation_court_tribunal: 1chinese_legal_benchmark_blocked: 1chinese_case_retrieval: 1official_legislation: 1patent_fulltext: 1hf_dataset: 1regulation_xml: 1official_bulk_legal_xml: 1official_france_legal_archives: 1lemur_eurlex_environment: 1openlegaldata_court_decisions_germany: 1hf_court_judgements: 1hf_regulatory_filings: 1openlegaldata_laws_germany: 1parallel_translation_memory: 1
上传与清理规则
原始数据在本地以限定批次收集,上传至 TryDotAtwo/legal-corpus-raw-batches 仓库,通过上传记录和远程文件列表进行验证,之后才进行本地清理。本地清理标记(如 .uploaded.ok 和 .cleanup.ok)用于避免删除未经验证的原始数据。
备注:哈萨克斯坦来源
哈萨克斯坦法律语料库的来源归属于 Any0ka/kazakhstan-laws-dataset。在该原始语料库中,它被追踪为 batch-205-kazakhstan-legal-corpus,并保留了批次元数据、文件清单和清单。其语言为哈萨克语和俄语(kk, ru)。
部分来源快照
以下为来源目录的部分快照,展示了批次名称、来源ID、质量等级、类型/来源家族、URL以及许可证条款:
| 批次 | 来源 ID | 等级 | 类型/来源家族 | URL | 许可证 |
|---|---|---|---|---|---|
batch-046-riksarkivet-court-records-aa-ad |
046_riksarkivet_court_records_aa_ad |
core_legal |
hf_court_records_split_archive |
https://huggingface.co/datasets/Riksarkivet/court_records |
source-specific terms; verify before redistribution |
batch-205-kazakhstan-legal-corpus |
any0ka_kazakhstan_laws_dataset |
core_legal |
kazakhstan_laws_any0ka |
https://huggingface.co/datasets/Any0ka/kazakhstan-laws-dataset |
odc-by / source-specific; verify upstream dataset card and source notices |
batch-058-australia-commonwealth-legislation |
australia_commonwealth_legislation |
core_legal |
hf_australia_legislation |
https://huggingface.co/datasets/workingmem/legislation-cth |
CC-BY-4.0 per HF tag; verify upstream card before public redistribution |
batch-227-govinfo-cfr-2020-2023 |
batch_227_govinfo_cfr_2020_2023 |
core_legal |
govinfo_cfr |
https://www.govinfo.gov/bulkdata |
US government public information; verify collection-specific reuse |
batch-060-cail2018-china |
cail2018_china |
core_legal |
hf_chinese_case_law_dataset |
https://huggingface.co/datasets/china-ai-law-challenge/cail2018 |
unknown per HF tag; private research collection, verify before redistribution/public release |
batch-216-catalan-spanish-legal-parallel |
catalan_spanish_legal_parallel |
core_legal |
catalan_spanish_legal_parallel |
https://huggingface.co/datasets/BSC-LT/Legal_Catalan_Spanish_Parallel_Corpus |
cc-by-4.0 |
batch-212-egypt-legal-corpus |
egypt_legal_corpus |
core_legal |
egypt_legal_corpus |
https://huggingface.co/datasets/dataflare/egypt-legal-corpus |
mit |
batch-208-czech-constitutional-court |
czech_constitutional_court_decisions |
core_legal |
czech_constitutional_court_decisions |
https://huggingface.co/datasets/roslein/CZE_constitutional_court_decisions |
eupl-1.1 |