terminal_bench_2_a1_nemo_prism_math_20260821_153041
收藏资源简介:
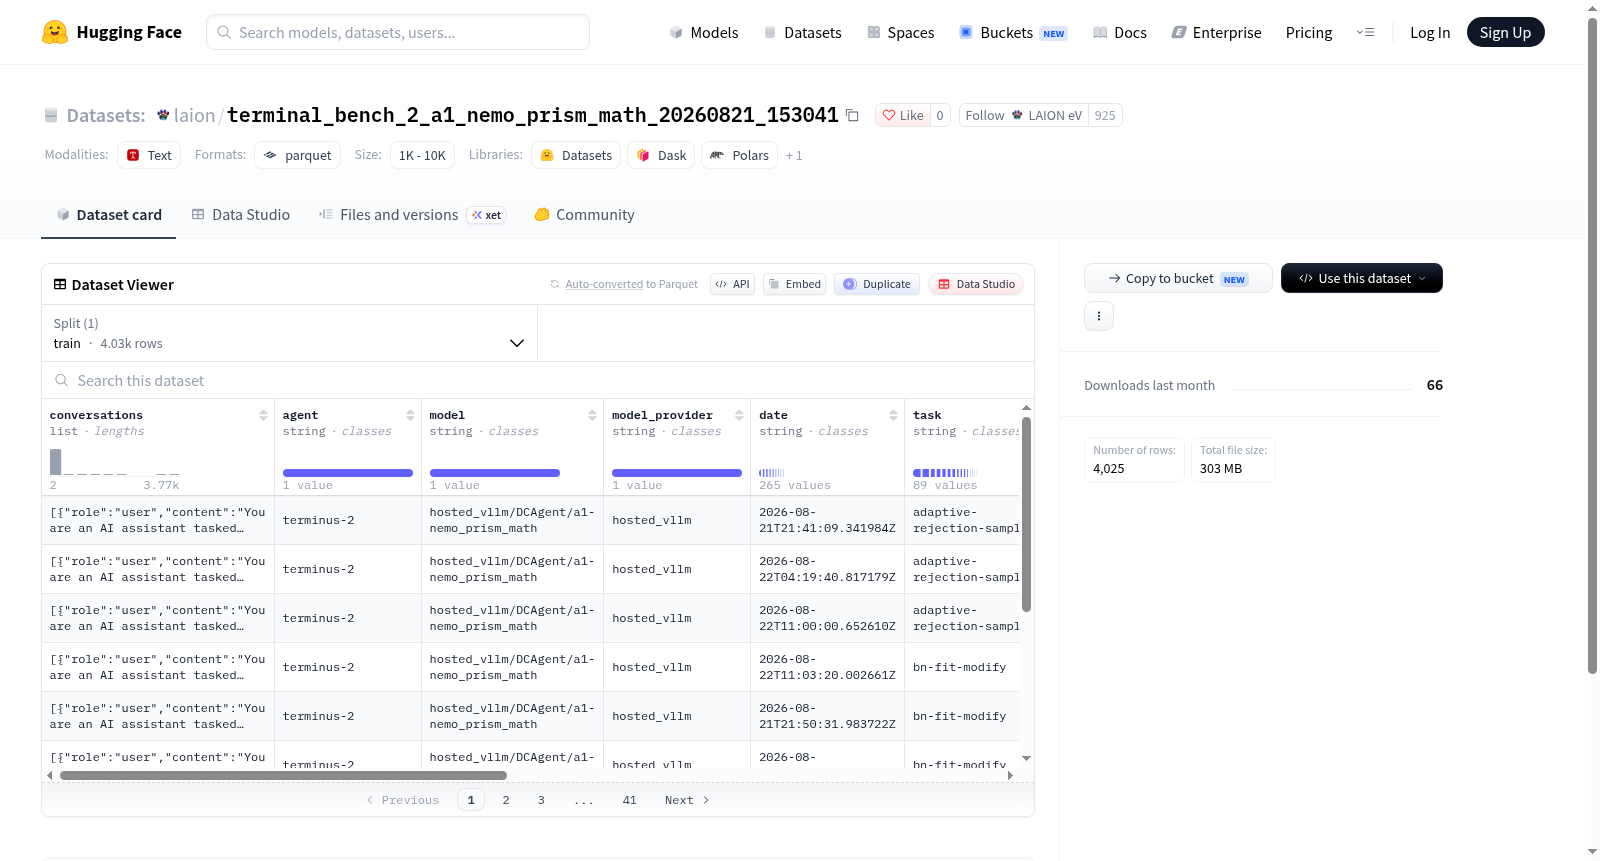
该数据集是一个多轮对话训练集,包含 4025 个样本,每个样本记录了一次完整的对话交互过程。数据集中每条样本包含以下字段:conversations(对话历史,每轮对话由角色 role 和内容 content 组成)、agent(代理或助手名称)、model(模型名称)、model_provider(模型提供商)、date(日期)、task(任务描述)、episode(轮次)、run_id(运行 ID)、trial_name(试验名称)、result(结果)、verifier_output(验证器输出)以及 trace_source(追踪来源)。该数据集适用于训练或评估对话代理、分析模型输出质量、验证对话结果等任务。数据仅提供训练集,格式为 Parquet 或类似结构,总大小约 543MB。
This dataset is a multi-turn dialogue training set containing 4025 samples, each recording a complete dialogue interaction process. Each sample in the dataset includes the following fields: conversations (dialogue history, each turn consisting of role and content), agent (agent or assistant name), model (model name), model_provider (model provider), date (date), task (task description), episode (episode), run_id (run ID), trial_name (trial name), result (result), verifier_output (verifier output), and trace_source (trace source). This dataset is suitable for training or evaluating dialogue agents, analyzing model output quality, verifying dialogue results, etc. The data only provides a training set in Parquet or similar format, with a total size of approximately 543MB.