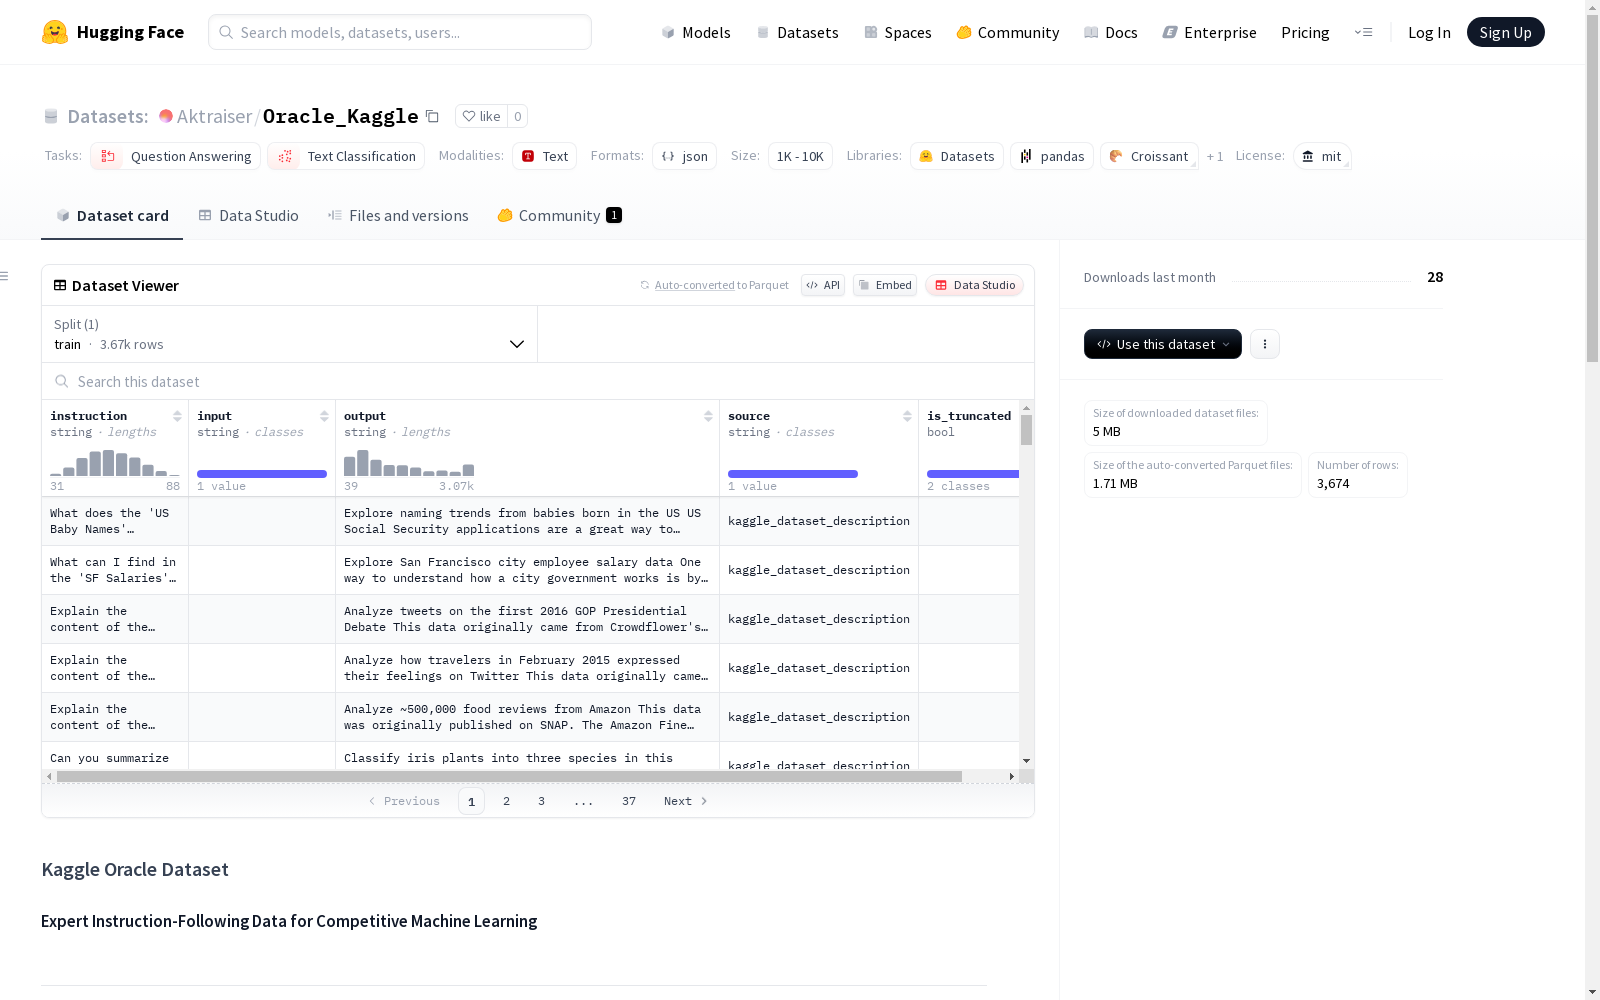
Oracle_Kaggle
收藏资源简介:
Kaggle Oracle数据集是一个为机器学习竞赛设计的,包含专家指导的指令-响应对的高质量数据集。该数据集由超过1490万个kernels和9700个竞赛中的真实内容构建而成,覆盖了NLP、ML、时间序列和计算机视觉等领域。它包含了175个专家策划的指令-响应对,专为指令遵循型LLM优化,并具有95/100的专业质量评分。
The Kaggle Oracle Dataset is a high-quality dataset of expert-curated instruction-response pairs designed for machine learning competitions. It is constructed from over 14.9 million kernels and real contest content from 9700 competitions, covering domains including NLP, ML, time series, and computer vision. The dataset contains 175 expert-curated instruction-response pairs, specifically optimized for instruction-following LLMs, and has a professional quality score of 95/100.
Kaggle Oracle 数据集概述
基本信息
- 许可证: MIT
- 任务类别: 问答、文本分类
- 数据规模: 10K<n<100K
数据集简介
Kaggle Oracle 数据集是一个高质量的数据集,包含指令-响应对,专为微调大型语言模型(LLMs)以在Kaggle竞赛中提供专家指导而设计。数据集基于14.9M+内核和9,700个竞赛构建,是竞争性机器学习策略的最全面数据集。
主要特点
- 175个专家精选的指令-响应对
- 100%真实Kaggle内容,无合成数据
- 广泛覆盖领域: NLP(43%)、ML(25%)、时间序列(21%)、计算机视觉(11%)
- 优化用于指令跟随的LLMs
- 基准质量: 95/100专业评分
数据集统计
| 指标 | 值 |
|---|---|
| 总训练对数 | 175 |
| 平均指令长度 | 93字符 |
| 平均响应长度 | 1,710字符 |
| 领域 | 4(NLP、ML、TS、CV) |
| 源质量评分 | 95/100 |
| 专业等级 | 95% |
竞争优势
- 最佳领域专业化(100%真实ML)
- 纯真实数据,无虚构策略
- 最高专业质量(95% vs. 行业平均70%)
数据格式
所有条目遵循Alpaca指令调优风格: json { "instruction": "What strategy would you recommend for a computer vision competition with 1,500 participating teams?", "input": "", "output": "Based on analysis of successful computer vision competitions, heres my recommended strategy: 1. Transfer Learning Foundation: Start with pre-trained models like EfficientNet or ResNet..." }