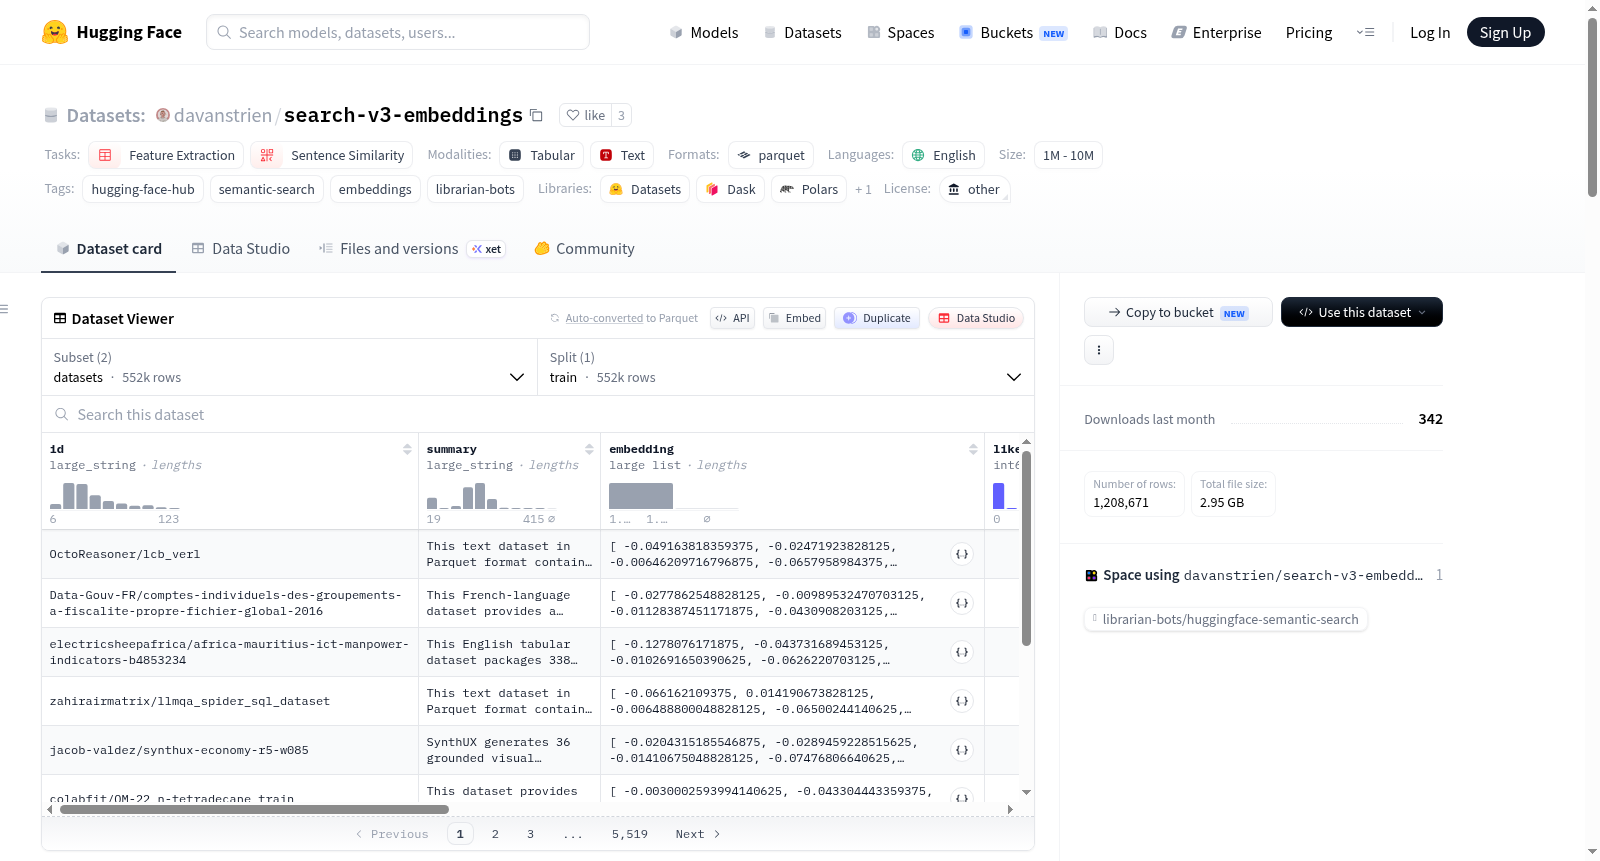
search-v3-embeddings
收藏资源简介:
Hub Card Search Embeddings (v3) 是一个专为语义搜索设计的数据集,包含Hugging Face Hub上1,173,030个公开数据集和模型卡片(536,870个数据集,636,160个模型)的机器生成单句摘要及其对应的1024维嵌入向量。该数据集源自每日更新的公共卡片转储(librarian-bots/dataset_cards_with_metadata和librarian-bots/model_cards_with_metadata),并过滤了无内容或内容极少的卡片。摘要由davanstrien/hub-tldr-v3-lfm25-350m模型生成,嵌入向量由Qwen/Qwen3-Embedding-0.6B模型计算,存储为fp16格式。数据集提供两个配置(datasets和models),包含id、摘要文本、嵌入向量、元数据(如点赞数、下载量、最后修改时间、任务类型、许可证、语言)、摘要来源(model/template/none)、置信度标记(low_confidence)和质量标志(flags)等字段,其中模型配置额外包含参数字段(param_count)。该数据集主要用作Hugging Face Hub语义搜索后端的基础索引,支持通过摘要嵌入进行高效检索,并提供了256维Matryoshka截断视图以优化存储和查询性能。需要注意的是,部分摘要可能因卡片内容稀疏而存在机器生成的误差,且617行数据的嵌入向量为null,构建索引前需过滤。
Hub Card Search Embeddings (v3) is a dataset specifically designed for semantic search, containing machine-generated single-sentence summaries and their corresponding 1024-dimensional embedding vectors for 1,173,030 public dataset and model cards (536,870 datasets, 636,160 models) on the Hugging Face Hub. The dataset is derived from daily updated public card dumps (librarian-bots/dataset_cards_with_metadata and librarian-bots/model_cards_with_metadata), with cards that have no content or minimal content filtered out. Summaries are generated by the davanstrien/hub-tldr-v3-lfm25-350m model, and embedding vectors are computed by the Qwen/Qwen3-Embedding-0.6B model, stored in fp16 format. The dataset provides two configurations (datasets and models), including fields such as id, summary text, embedding vector, metadata (e.g., likes, downloads, last modified time, task type, license, language), summary source (model/template/none), confidence marker (low_confidence), and quality flags (flags), with the model configuration additionally including a parameter field (param_count). This dataset is primarily used as the underlying index for the Hugging Face Hub semantic search backend, enabling efficient retrieval via summary embeddings, and offers a 256-dimensional Matryoshka truncated view to optimize storage and query performance. It should be noted that some summaries may contain machine-generated errors due to sparse card content, and 617 rows have null embedding vectors, which must be filtered before building the index.
数据集概述:Hub Card Search Embeddings (v3)
该数据集是 Hugging Face Hub 上 1,173,030 个数据集和模型卡片(536,870 个数据集 + 636,160 个模型)的单句摘要及其对应的 1024 维嵌入向量。它是 librarian-bots/huggingface-semantic-search 空间后端所使用的语义搜索索引。
数据来源与筛选
- 原始来源:来自每日刷新的公共卡片转储数据集
librarian-bots/dataset_cards_with_metadata和librarian-bots/model_cards_with_metadata。 - 筛选条件:丢弃内容为空或接近为空的卡片(要求
card非空,且字节数在 200 到 100,000 之间),因此最终数量低于原始转储总数。
构建流程
- 生成摘要:使用
davanstrien/hub-tldr-v3-lfm25-350m(一个 3.5 亿参数的 LFM2.5 微调模型,通过 vLLM 服务,temperature=0.3,max_tokens=120),为每张符合条件的卡片生成一句话摘要。 - 生成嵌入:使用
Qwen/Qwen3-Embedding-0.6B模型对上述摘要进行嵌入,存储为 fp16 格式、完整 1024 维的向量。
摘要质量与置信度
摘要由机器生成,主要用于检索,不适合直接引用。
- 来源分布:
model:模型生成(数据集 84.8%,模型 82.6%)。template:模板生成(数据集 15.1%,模型 17.4%),用于卡片内容过薄无法摘要的情况。none:模型返回“信息不足”(数据集 0.1%,模型 0.0%),摘要和嵌入均为 null。
- 置信度:
low_confidence列为 True 的数据占数据集 16.0%,模型 22.4%。包含所有模板行、拒绝行以及再生后仍未能通过筛查的模型摘要。 - 注意事项:对于内容单薄或自动生成的卡片,模型可能虚构准确但实际错误的细节。
flags列记录了具体的筛查或拒绝原因。
数据集配置与结构
数据集包含两个配置:datasets 和 models,除 param_count 列外列结构相同。
列说明:
| 列名 | 类型 | 说明 |
|---|---|---|
id |
string | 仓库 ID |
summary |
string | 一句话摘要;对于拒绝样本为 null |
embedding |
list<float16>[1024] | 嵌入向量;对于拒绝样本为 null;支持截断至 256 维以用于 Matryoshka Representation Learning (MRL) 视图 |
likes |
int64 | 源元数据(点赞数) |
downloads |
int64 | 源元数据(下载量) |
last_modified |
string | 源元数据(最后修改时间) |
task |
string | 模型为 pipeline_tag,数据集为 task_categories 标签;可为 null |
license |
string | 来自 license 标签;可为 null |
language |
string | 来自 language 标签,逗号连接;可为 null |
summary_source |
string | 摘要来源:model, template, 或 none |
low_confidence |
bool | 低置信度标志 |
flags |
list<string> | 筛查/门控原因列表 |
param_count |
int64 | 仅模型配置;来自 safetensors.total;不存在时为 null |
关键处理建议
- 空嵌入处理:共有 617 行(581 个数据集 + 36 个模型)嵌入向量为 null(拒绝样本)。在构建向量索引前必须过滤
embedding IS NOT NULL。 - MRL 截断使用:Qwen3-Embedding 支持 Matryoshka 截断,可仅使用前 256 维以降低存储和查询成本,同时保留大部分排名准确性。后端索引即使用 256 维视图。
许可与致谢
- 许可:数据集使用
other许可证。 - 语言:英语。
- 任务类别:特征提取、句子相似度。
- 致谢:由 Hugging Face 的 Daniel van Strien 构建。原始卡片来自 librarian-bots 转储,由各仓库作者编写;摘要由
hub-tldr-v3-lfm25-350m生成,嵌入由Qwen/Qwen3-Embedding-0.6B生成。此数据集不改变或取代原始卡片的许可证。