tner/wnut2017
收藏资源简介:
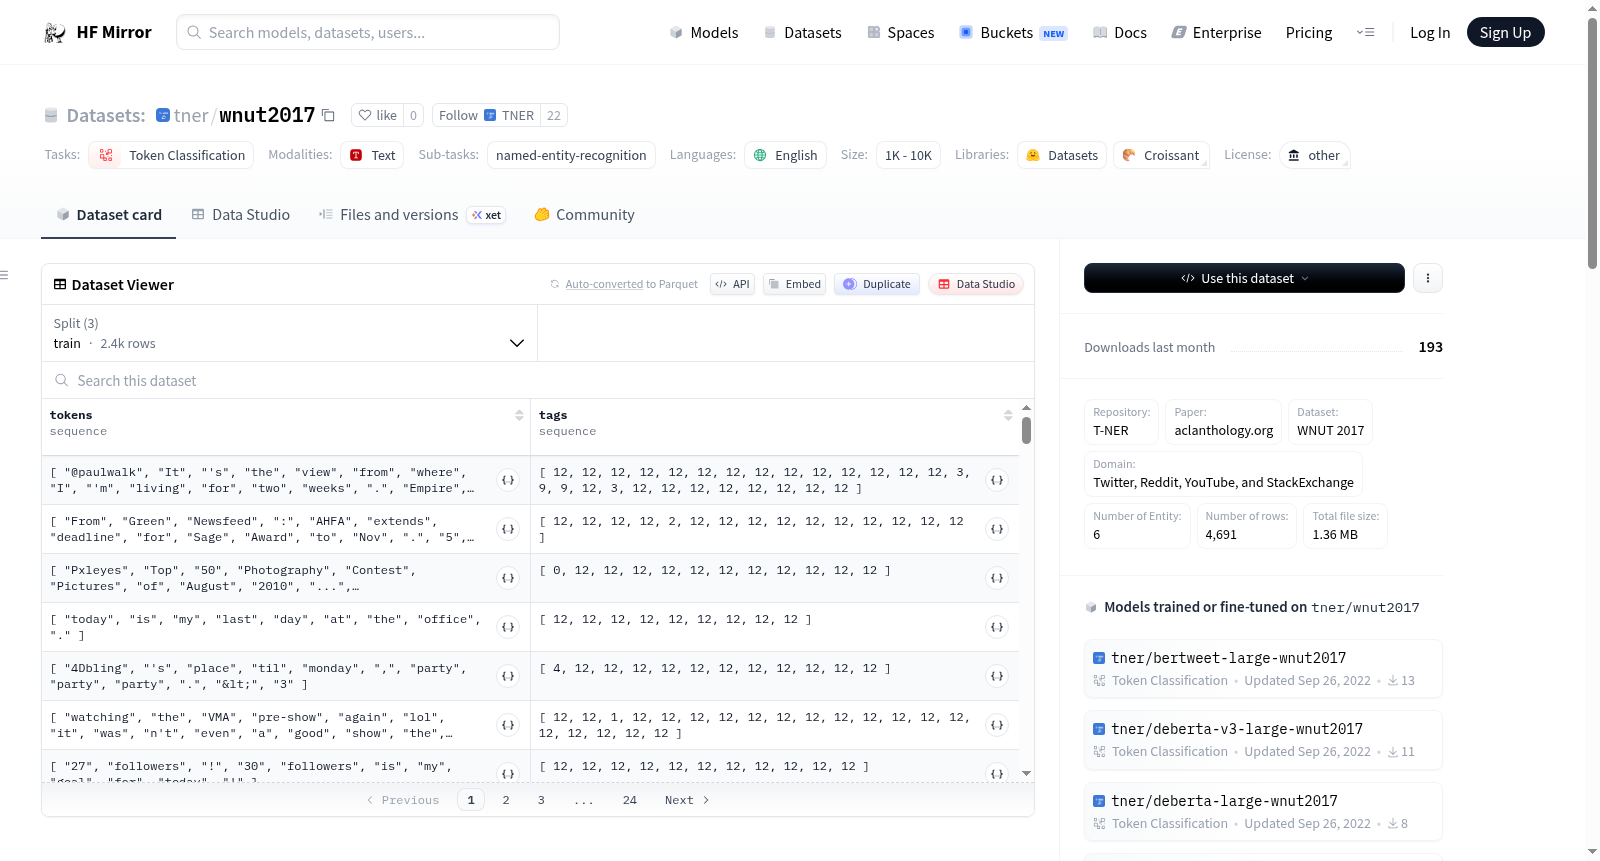
WNUT 2017数据集是一个用于命名实体识别(NER)任务的数据集,主要来源于社交媒体平台如Twitter、Reddit、YouTube和StackExchange。数据集中包含6种实体类型:creative-work、corporation、group、location、person和product。数据集的结构包括训练集、验证集和测试集,分别包含2395、1009和1287个样本。数据集的标签包括B-和I-前缀,分别表示实体的开始和内部。
The WNUT 2017 dataset is a benchmark dataset for named entity recognition (NER) tasks, primarily sourced from social media platforms including Twitter, Reddit, YouTube, and StackExchange. It covers six entity types: creative-work, corporation, group, location, person, and product. The dataset is split into training, validation, and test sets, which contain 2395, 1009, and 1287 samples respectively. It adopts the BIO labeling schema, where the B- and I- prefixes denote the beginning and internal parts of an entity respectively.
数据集概述
数据集描述
- 名称: WNUT 2017
- 领域: Twitter, Reddit, YouTube, StackExchange
- 实体数量: 6
- 实体类型:
creative-work,corporation,group,location,person,product
数据集结构
数据实例
- 示例: json { tokens: [@paulwalk, It, "s", the, view, from, where, I, "m", living, for, two, weeks, ., Empire, State, Building, =, ESB, ., Pretty, bad, storm, here, last, evening, .], tags: [12, 12, 12, 12, 12, 12, 12, 12, 12, 12, 12, 12, 12, 12, 3, 9, 9, 12, 3, 12, 12, 12, 12, 12, 12, 12, 12] }
标签ID
- 标签映射: python { "B-corporation": 0, "B-creative-work": 1, "B-group": 2, "B-location": 3, "B-person": 4, "B-product": 5, "I-corporation": 6, "I-creative-work": 7, "I-group": 8, "I-location": 9, "I-person": 10, "I-product": 11, "O": 12 }
数据分割
| 名称 | 训练 | 验证 | 测试 |
|---|---|---|---|
| wnut2017 | 2395 | 1009 | 1287 |