johnny-w/flower-named-reactions-hard
收藏资源简介:
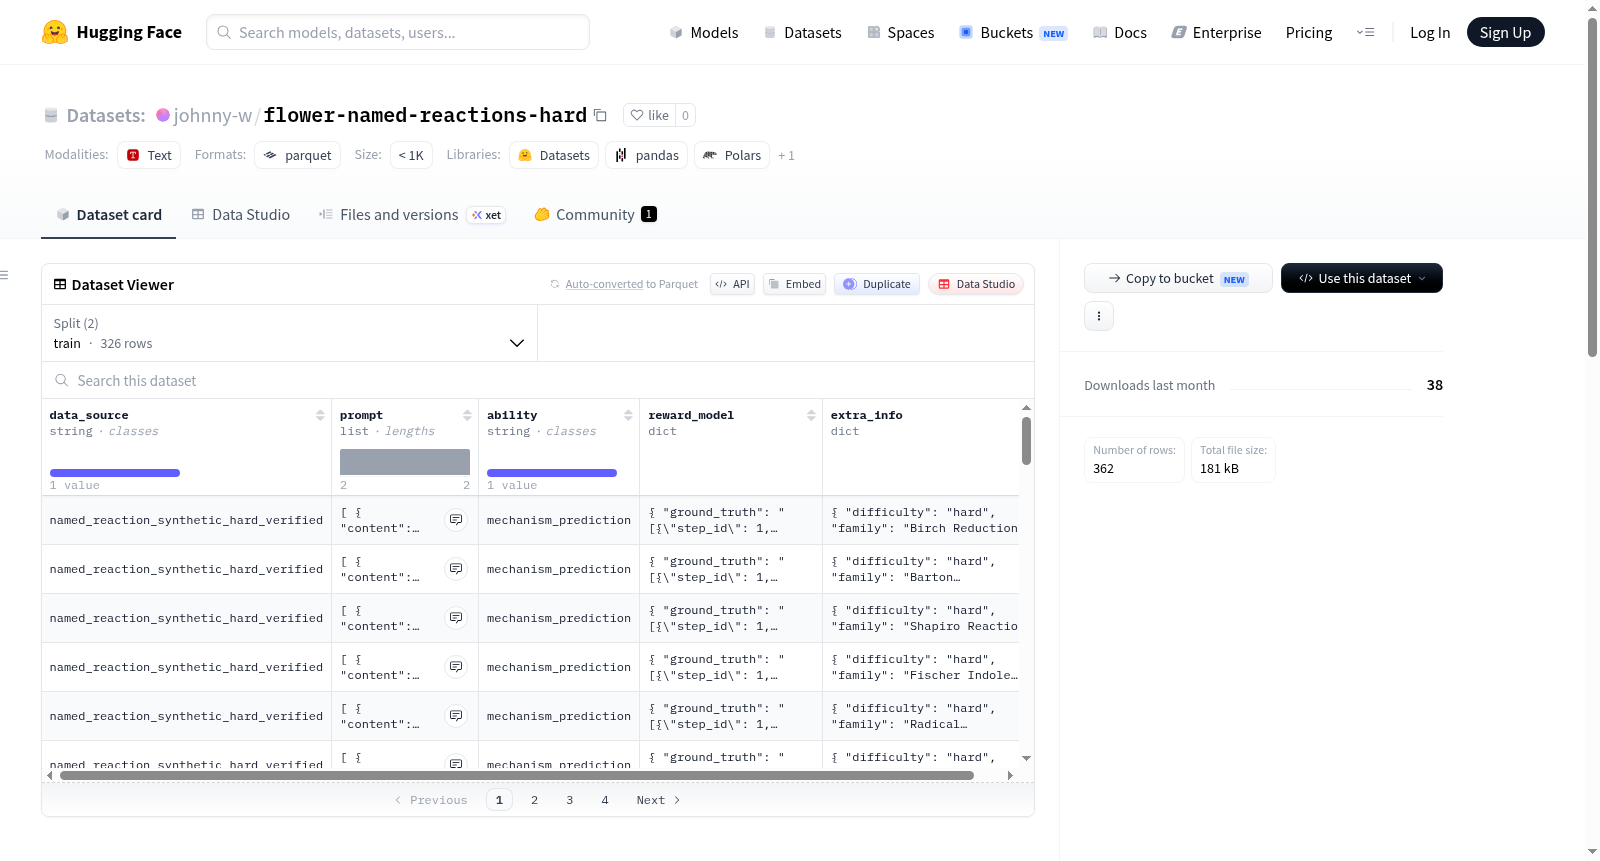
该数据集名为flower-named-reactions-hard,是一个以verl RL格式存储的困难命名反应机制数据集,由Gemini生成,作为数据集johnny-w/flower的伴生数据集。数据源标签为named_reaction_synthetic_hard_verified。数据集包含326个训练样本和36个验证样本,覆盖10个困难命名反应家族,如Fischer吲哚合成、Shapiro反应等。这些机制经过生成、原子映射和RDKit工具包验证流程(current_verified_toolkit_flash管道)。需要注意的是,这是一个负面结果数据集,未在最终模型中使用,因为在实验中发现它混合到强化学习训练中会降低Fukuyama性能(例如导致精确pass@1得分下降),并可能使模型偏离真实化学分布。数据集仅建议用于复现合成数据不匹配的发现,而非改进模型。模式结构包括data_source、prompt(verl提示格式的聊天消息列表)、ability(任务标签)、reward_model.ground_truth(真实机制轨迹,以FlowER风格原子映射SMILES表示)和extra_info(包含难度、家族和名称等信息)。
The dataset is named flower-named-reactions-hard, containing Gemini-generated hard named-reaction mechanisms in verl RL format, serving as a companion to the dataset johnny-w/flower. The data_source tag is named_reaction_synthetic_hard_verified. It includes 326 train and 36 validation mechanisms across 10 difficult named-reaction families, such as Fischer Indole Synthesis, Shapiro Reaction, etc. These mechanisms are generated, atom-mapped, and verified with an RDKit toolkit pass (the current_verified_toolkit_flash pipeline). Note that this is a negative result subset archived for completeness; it was mixed into RL training in abandoned experiments and degraded Fukuyama performance (e.g., reducing exact pass@1 scores), shifting the model away from the real-chemistry distribution. It is recommended only for reproducing the synthetic-data-mismatch finding, not for model improvement. The schema follows verl RL format with fields: data_source, prompt (list of chat messages), ability (task tag), reward_model.ground_truth (ground-truth mechanism trajectory in FlowER-style atom-mapped SMILES), and extra_info (containing difficulty, family, and name).