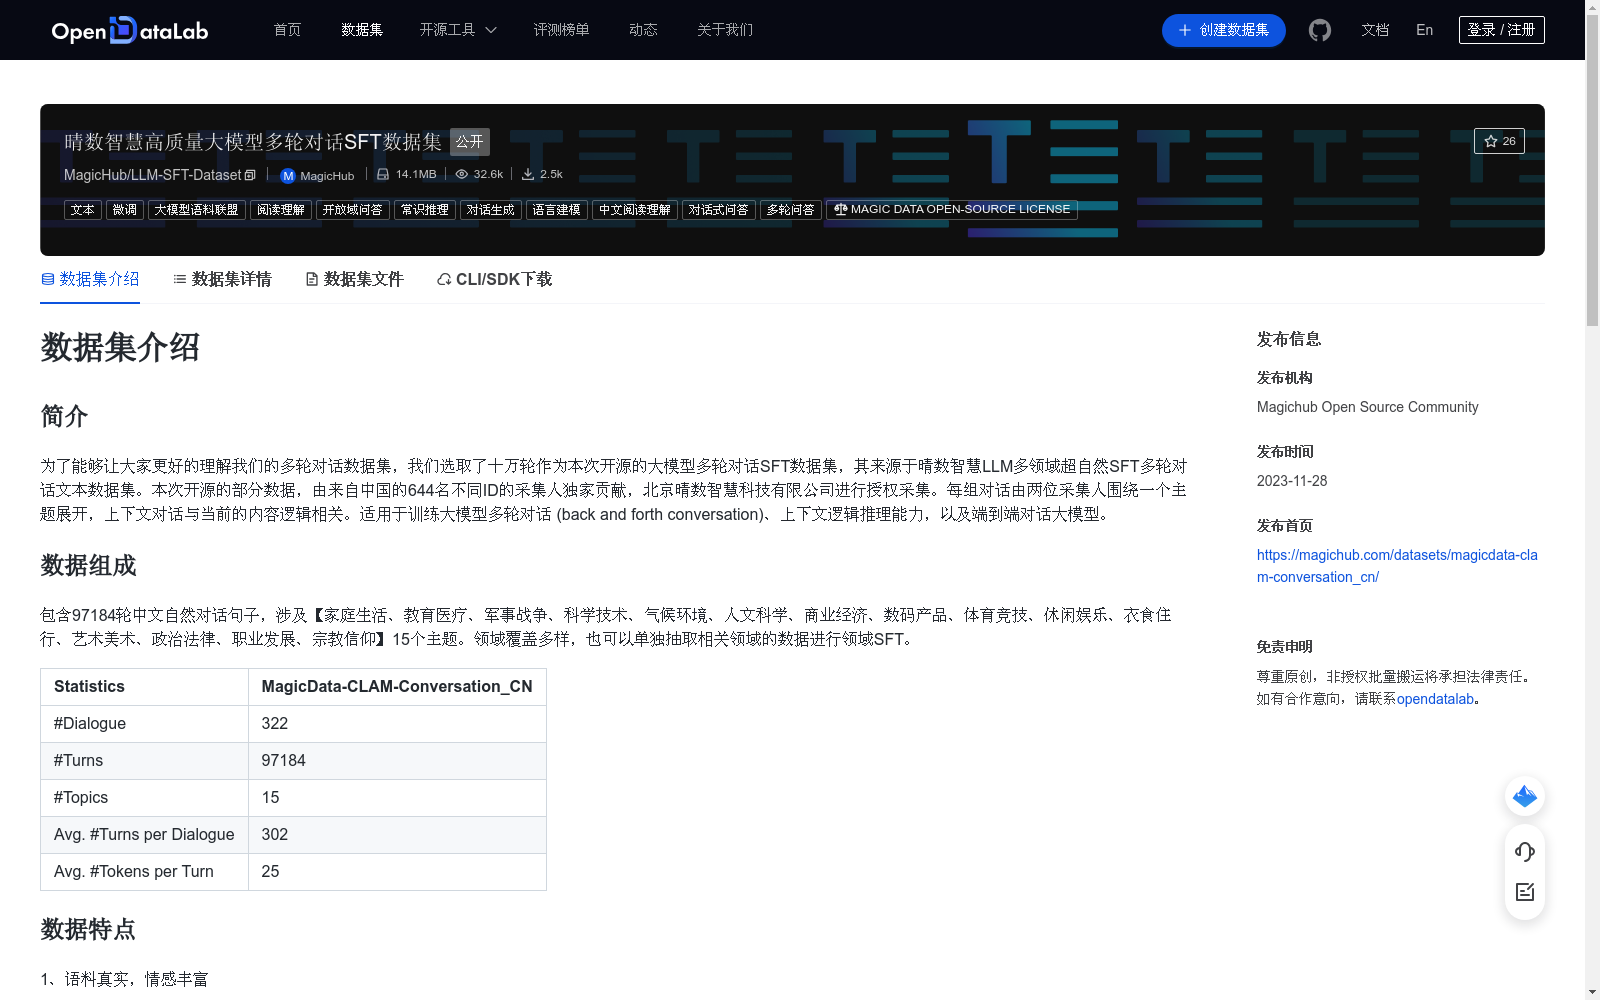
晴数智慧高质量大模型多轮对话SFT数据集
收藏资源简介:
此数据集包含15万轮中文自然对话句子,由来自中国7个省份 (江苏、四川、山东、山西、北京、广东、海南)的663名说话人贡献,其中男性368人,女性295人。每组对话由两名说话人围绕一个主题展开,历史的对话与当前的内容密切相关。适用于训练大模型多轮对话 (back and forth conversation)、上下文逻辑推理能力。
This dataset contains 150,000 rounds of Chinese natural dialogue sentences, contributed by 663 speakers from 7 provinces in China (Jiangsu, Sichuan, Shandong, Shanxi, Beijing, Guangdong, Hainan), including 368 male speakers and 295 female speakers. Each dialogue session involves two speakers conducting a conversation centered on a specific topic, where the historical dialogue context is closely correlated with the current conversation content. This dataset is suitable for training large language models (LLMs) in multi-turn back-and-forth conversation and contextual logical reasoning capabilities.