qwen-deepfashion-fused
收藏资源简介:
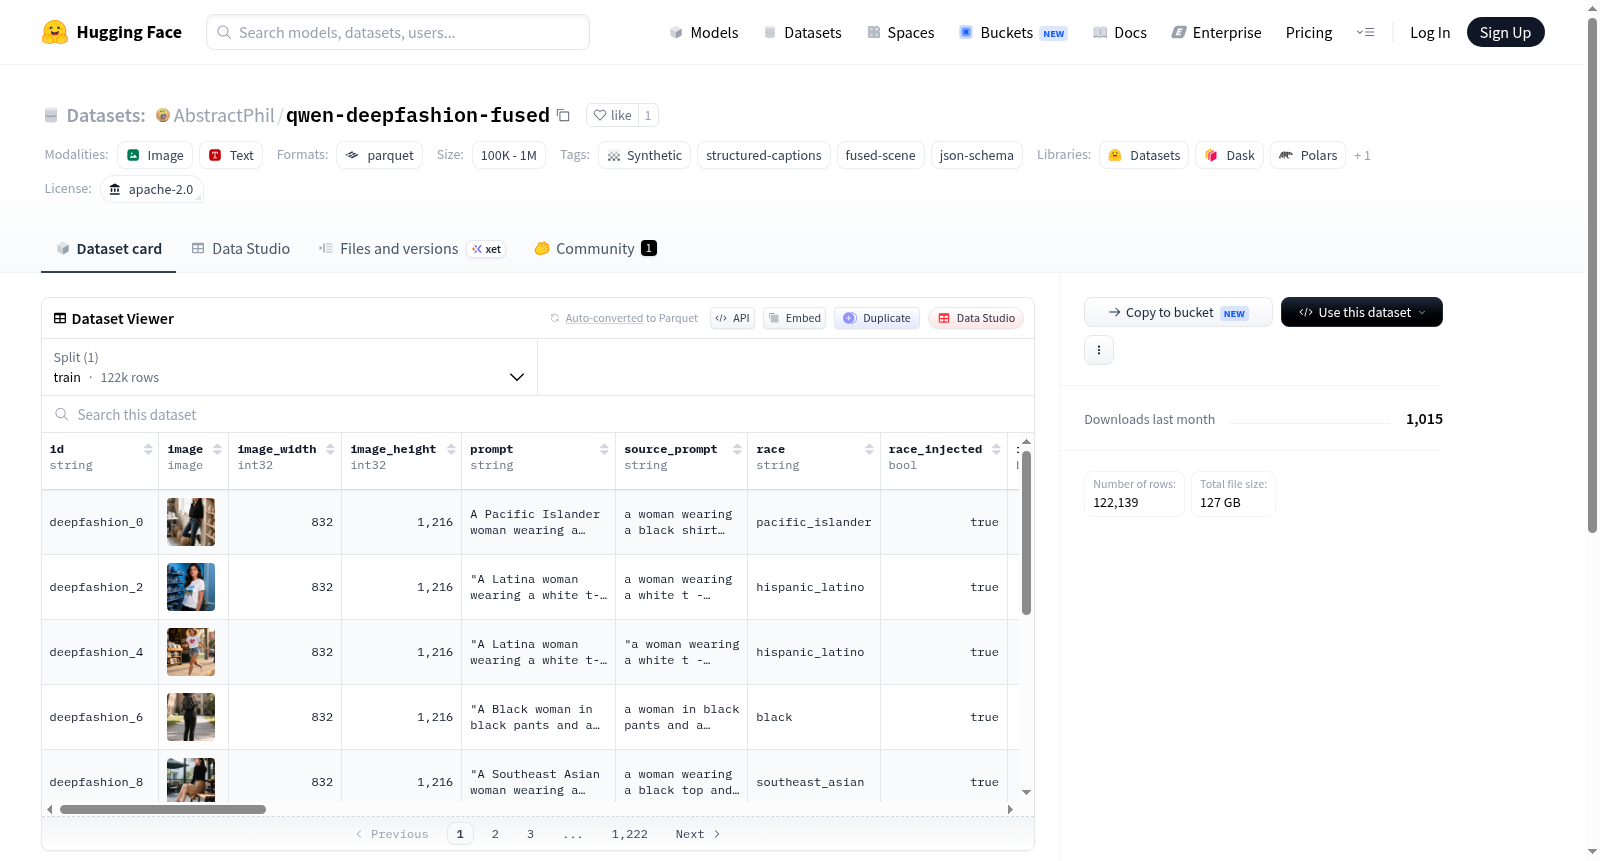
qwen-deepfashion-fused是一个合成数据集,专注于结构化标题和融合场景生成。它基于AbstractPhil/qwen-deepfashion数据集的SFW(适合工作场所)行,通过qwen-test-runner的12进程融合提取系统处理得到。处理流程包括严格的年龄门控、使用Qwen3.5-9B模型进行3次标题结构化、生成12个确定性视觉任务JSON、构建FusedScene(包含具有掩码包含分层属性的实体、连续偏移的关系、计数和共享基础),以及生成确定性融合提示。数据集规模为122139个保留行,年龄门控拒绝38076行,以parquet格式存储,分片严格小于350MB,并包含_manifests/目录记录处理状态。适用于结构化标题生成、多模态学习、视觉任务和场景理解等任务。提取模型使用Apache-2.0/MIT许可证,输出可再分发。
qwen-deepfashion-fused is a synthetic dataset focused on structured captions and fused scene generation. It is based on the SFW (Safe for Work) rows of the AbstractPhil/qwen-deepfashion dataset, processed through a 12-process fusion extraction system from qwen-test-runner. The processing pipeline includes strict age gating, 3 rounds of caption structuring using the Qwen3.5-9B model with slot registry mode, generation of 12 deterministic visual task JSONs, construction of FusedScene (fused_json) containing entities with mask-inclusive hierarchical attributes, relationships with continuous offsets, counts, and shared bases, and finally generation of deterministic fusion prompts. The dataset scale is 122139 retained rows, with 38076 rows rejected by age gating. It is stored in parquet format with shards strictly smaller than 350MB, and includes an _manifests/ directory recording the processing status of each source shard (rows input/retained/rejected and timing). It is suitable for tasks such as structured caption generation, multimodal learning, visual tasks, and scene understanding. The extraction model uses Apache-2.0/MIT license, and the output is redistributable.
数据集概述
- 数据集名称:qwen-deepfashion-fused
- 许可证:Apache-2.0
- 标签:synthetic, structured-captions, fused-scene, json-schema
数据来源与处理流程
该数据集基于 AbstractPhil/qwen-deepfashion 数据集中所有 SFW(Safe for Work)行,经过 qwen-test-runner 12 进程融合提取系统处理,具体流程如下:
- 年龄门控(严格模式):过滤掉不安全内容。
- 3× 标题结构化:使用 Qwen3.5-9B 模型,基于 slot-registry 模式进行三次标题结构化处理。
- 12 个确定性视觉任务 JSON:生成
tasks_json。 - FusedScene 融合:生成
fused_json,包含实体(具有掩码包含、归属、分层属性)、关系(连续偏移量、计数、共享流域)等。 - 确定性融合提示:生成
prompt_fused。
数据集规模
- 保留行数:122,139 行
- 年龄门控拒绝行数:38,076 行
数据格式
- 配置名称:default
- 数据文件:训练集位于
data/*.parquet - 分片限制:每个分片严格低于 350MB
- 元数据:
_manifests/目录包含每个源分片的完成标记(行数入/保留/拒绝 + 耗时)
模型与许可
- 所有提取模型均采用 Apache-2.0 或 MIT 许可证,输出结果可再分发。
- 方法论详见
qwen-test-runner仓库中的docs/VISION_PIPELINE.md。