lightonai/Dolci-Think-SFT-32B-Multilingual
收藏资源简介:
--- license: odc-by task_categories: - text-generation language: - en - fr - de - es - zh - sw tags: - reasoning - chain-of-thought - multilingual - sft pretty_name: Dolci-Think-SFT-32B-Multilingual size_categories: - 1M<n<10M --- # Dolci-Think-SFT-32B-Multilingual `Dolci-Think-SFT-32B-Multilingual` is a large-scale **multilingual long chain-of-thought (CoT) reasoning corpus** spanning **six languages**: English, French, German, Spanish, Chinese, and Swahili. Each sample includes a question, a long-form reasoning trace, and a final answer, **all translated into the target language**, with sequences up to **32,768 tokens**. It is released alongside the paper [**Rethinking the Multilingual Reasoning Gap with Layer Swap**](https://arxiv.org/abs/2605.26735). ## Dataset details - **Source corpus:** [`allenai/Dolci-Think-SFT-32B`](https://huggingface.co/datasets/allenai/Dolci-Think-SFT-32B). - **Languages:** English (source) + 5 translated languages (French, German, Spanish, Chinese, Swahili). - **Samples per language:** ~500k - **Max sequence length:** 32,768 tokens. - **Translation model:** [`google/gemma-3-27b-it`](https://huggingface.co/google/gemma-3-27b-it). ## Per-language statistics The table below reports sample counts and token volumes for each of the six languages. | Language | Samples | Mean tokens / sample | Total tokens | |---|:---:|:---:|:---:| | English | 485,873 | 10,848 | 5.27B | | Chinese | 484,078 | 10,890 | 5.27B | | Spanish | 479,748 | 13,400 | 6.43B | | French | 483,588 | 13,702 | 6.63B | | German | 480,529 | 13,846 | 6.65B | | Swahili | 473,582 | 16,208 | 7.68B | ## Category distribution (English source) The English source mixes seven task categories, dominated by math and code. | Category | % | Mean tokens | |---|:---:|:---:| | Math | 37.93% | 19,369 | | Code | 34.80% | 7,340 | | Instruction-following | 14.31% | 2,310 | | Science | 5.21% | 9,089 | | Safety | 3.98% | 739 | | General chat | 3.55% | 3,076 | | Structured data | 0.21% | 2,228 | ## Models trained on this dataset | Language | Native specialist | English-pivoted specialist | Layer Swap model | |---|---|---|---| | English | [`Qwen3-8B-EN`](https://huggingface.co/lightonai/Qwen3-8B-EN) | — | — | | French | [`Qwen3-8B-FR`](https://huggingface.co/lightonai/Qwen3-8B-FR) | [`Qwen3-8B-FR-Pivot-EN`](https://huggingface.co/lightonai/Qwen3-8B-FR-Pivot-EN) | [`Qwen3-8B-FR-Swap`](https://huggingface.co/lightonai/Qwen3-8B-FR-Swap) | | German | [`Qwen3-8B-DE`](https://huggingface.co/lightonai/Qwen3-8B-DE) | [`Qwen3-8B-DE-Pivot-EN`](https://huggingface.co/lightonai/Qwen3-8B-DE-Pivot-EN) | [`Qwen3-8B-DE-Swap`](https://huggingface.co/lightonai/Qwen3-8B-DE-Swap) | | Spanish | [`Qwen3-8B-ES`](https://huggingface.co/lightonai/Qwen3-8B-ES) | [`Qwen3-8B-ES-Pivot-EN`](https://huggingface.co/lightonai/Qwen3-8B-ES-Pivot-EN) | [`Qwen3-8B-ES-Swap`](https://huggingface.co/lightonai/Qwen3-8B-ES-Swap) | | Chinese | [`Qwen3-8B-ZH`](https://huggingface.co/lightonai/Qwen3-8B-ZH) | [`Qwen3-8B-ZH-Pivot-EN`](https://huggingface.co/lightonai/Qwen3-8B-ZH-Pivot-EN) | [`Qwen3-8B-ZH-Swap`](https://huggingface.co/lightonai/Qwen3-8B-ZH-Swap) | | Swahili | [`Qwen3-8B-SW`](https://huggingface.co/lightonai/Qwen3-8B-SW) | [`Qwen3-8B-SW-Pivot-EN`](https://huggingface.co/lightonai/Qwen3-8B-SW-Pivot-EN) | [`Qwen3-8B-SW-Swap`](https://huggingface.co/lightonai/Qwen3-8B-SW-Swap) | ## Citation If you find our work helpful, feel free to give us a cite. ```bibtex @misc{lasbordes2026rethinking, title = {Rethinking the Multilingual Reasoning Gap with Layer Swap}, author = {Lasbordes, Maxence and Chatelain, Amélie and Seddah, Djamé}, year = {2026}, eprint = {2605.26735}, archivePrefix= {arXiv}, primaryClass = {cs.CL} } ```
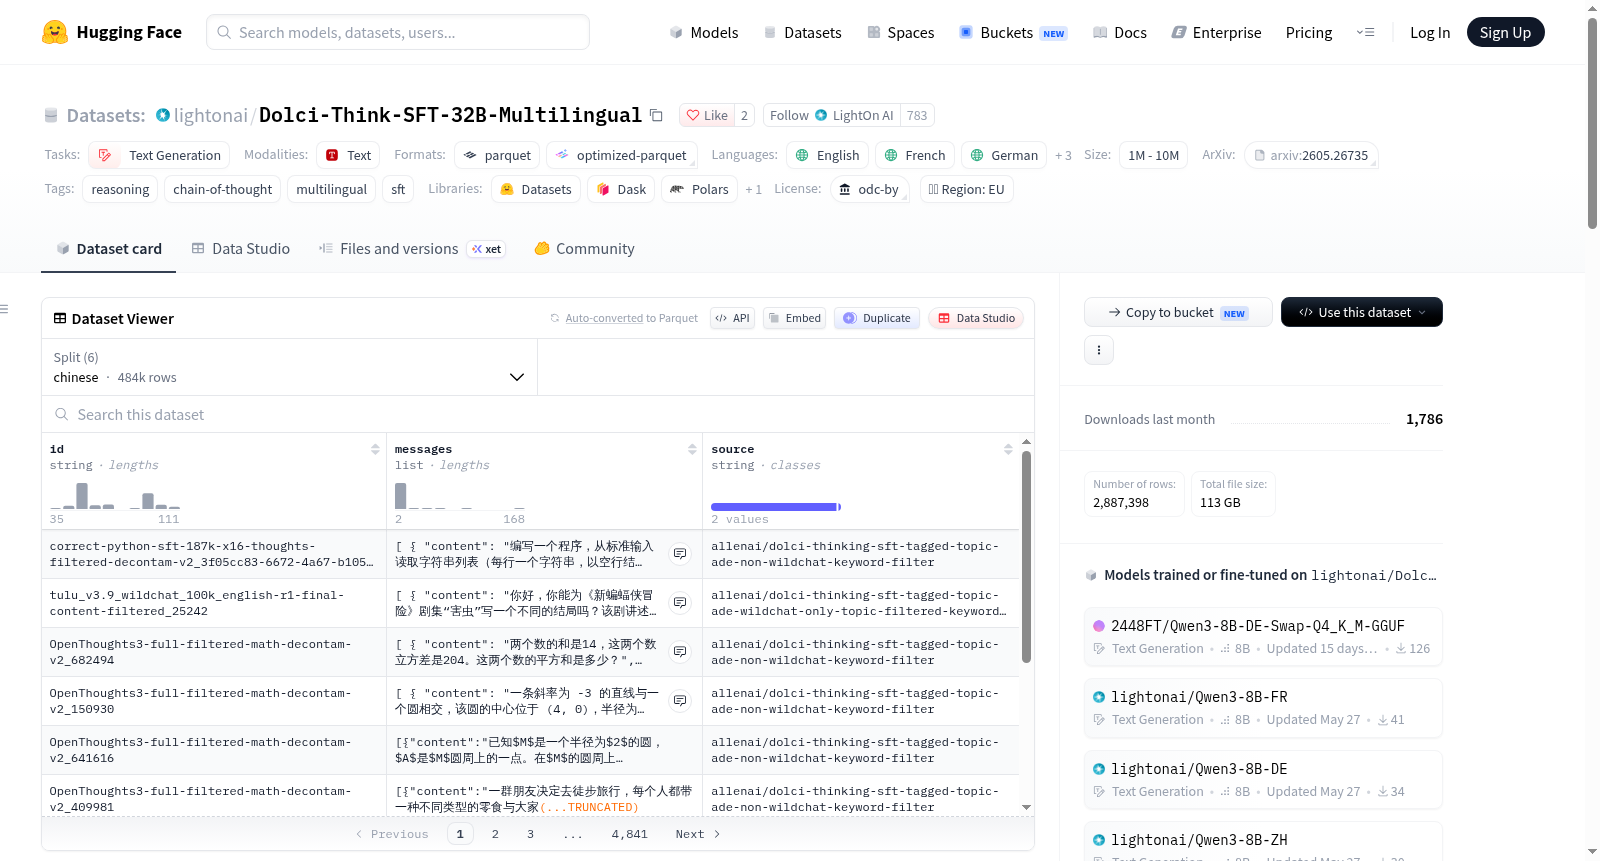
Dolci-Think-SFT-32B-Multilingual is a large-scale multilingual long chain-of-thought (CoT) reasoning corpus spanning six languages: English, French, German, Spanish, Chinese, and Swahili. Each sample includes a question, a long-form reasoning trace, and a final answer, all translated into the target language, with sequences up to 32,768 tokens. It is released alongside the paper Rethinking the Multilingual Reasoning Gap with Layer Swap. The source corpus is allenai/Dolci-Think-SFT-32B, with languages including English (source) plus five translated languages, approximately 500k samples per language, max sequence length of 32,768 tokens, and translation model google/gemma-3-27b-it. The English source mixes seven task categories dominated by math and code, with per-language statistics provided (e.g., English: 485,873 samples, mean tokens 10,848, total tokens 5.27B). Models trained on this dataset include native specialists, English-pivoted specialists, and Layer Swap models for each language.