FineLAP-100k
收藏资源简介:
FineLAP-100k是由上海交通大学与香港中文大学联合构建的大规模合成声音事件检测数据集,旨在解决时序标注数据稀缺的瓶颈问题。该数据集包含10万条合成音频样本,通过从FSD50K精选19,775个单事件音频片段,与1,765段环境背景音进行随机混合生成,每段音频时长10秒并包含1-5个重叠事件。数据集采用自动化流水线构建,首先通过能量阈值检测提取纯净事件片段,再结合随机信号噪比控制实现逼真合成,主要应用于开放词汇声音事件检测、音频-文本对齐等细粒度音频理解任务。
FineLAP-100k is a large-scale synthetic sound event detection dataset jointly constructed by Shanghai Jiao Tong University and The Chinese University of Hong Kong, aiming to address the bottleneck issue caused by the scarcity of temporally annotated data. This dataset contains 100,000 synthetic audio samples, generated by randomly mixing 19,775 single-event audio clips curated from FSD50K with 1,765 environmental background audio tracks. Each audio clip has a duration of 10 seconds and includes 1 to 5 overlapping sound events. The dataset is built via an automated pipeline: firstly, pure event segments are extracted through energy threshold detection, and then realistic synthesis is achieved by controlling random signal-to-noise ratio (SNR). It is mainly applied to fine-grained audio understanding tasks such as open-vocabulary sound event detection and audio-text alignment.
FineLAP-100k 数据集概述
数据集基本信息
- 数据集名称:FineLAP-100k
- 发布平台:Hugging Face Datasets
- 数据总量:100,000 个样本
- 数据集大小:57,166,176,827 字节(约 57.2 GB)
- 下载大小:57,197,822,960 字节(约 57.2 GB)
- 数据划分:仅包含训练集(train)
数据结构与特征
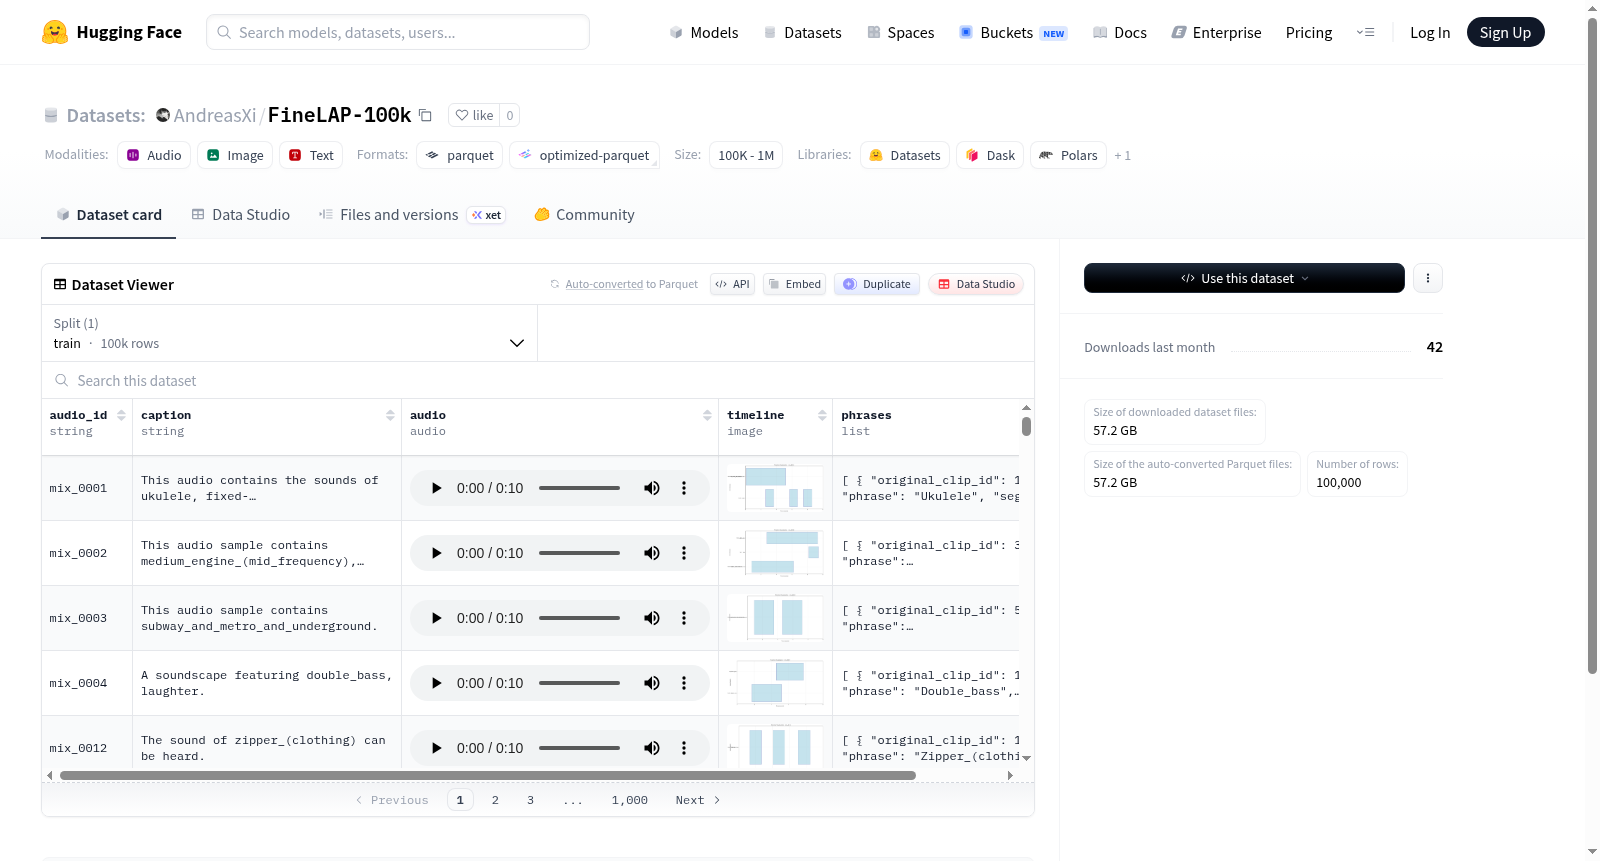
数据集包含以下字段:
核心字段
- audio_id:音频标识符(字符串类型)
- caption:音频描述文本(字符串类型)
- audio:音频数据(音频类型)
- timeline:时间线图像(图像类型)
结构化字段
- phrases:短语级标注列表
- original_clip_id:原始片段标识符(整型)
- phrase:短语文本(字符串类型)
- segments:时间片段列表
- end:结束时间(浮点型)
- start:开始时间(浮点型)
数据配置
- 配置名称:default
- 数据文件路径:
data/train-*
数据规模
- 训练集样本数:100,000
- 训练集大小:57,166,176,827 字节
适用场景
该数据集适用于音频描述生成、音频-文本对齐、细粒度音频理解等任务。