brandburner/encanto-s01-narrative-kg
收藏资源简介:
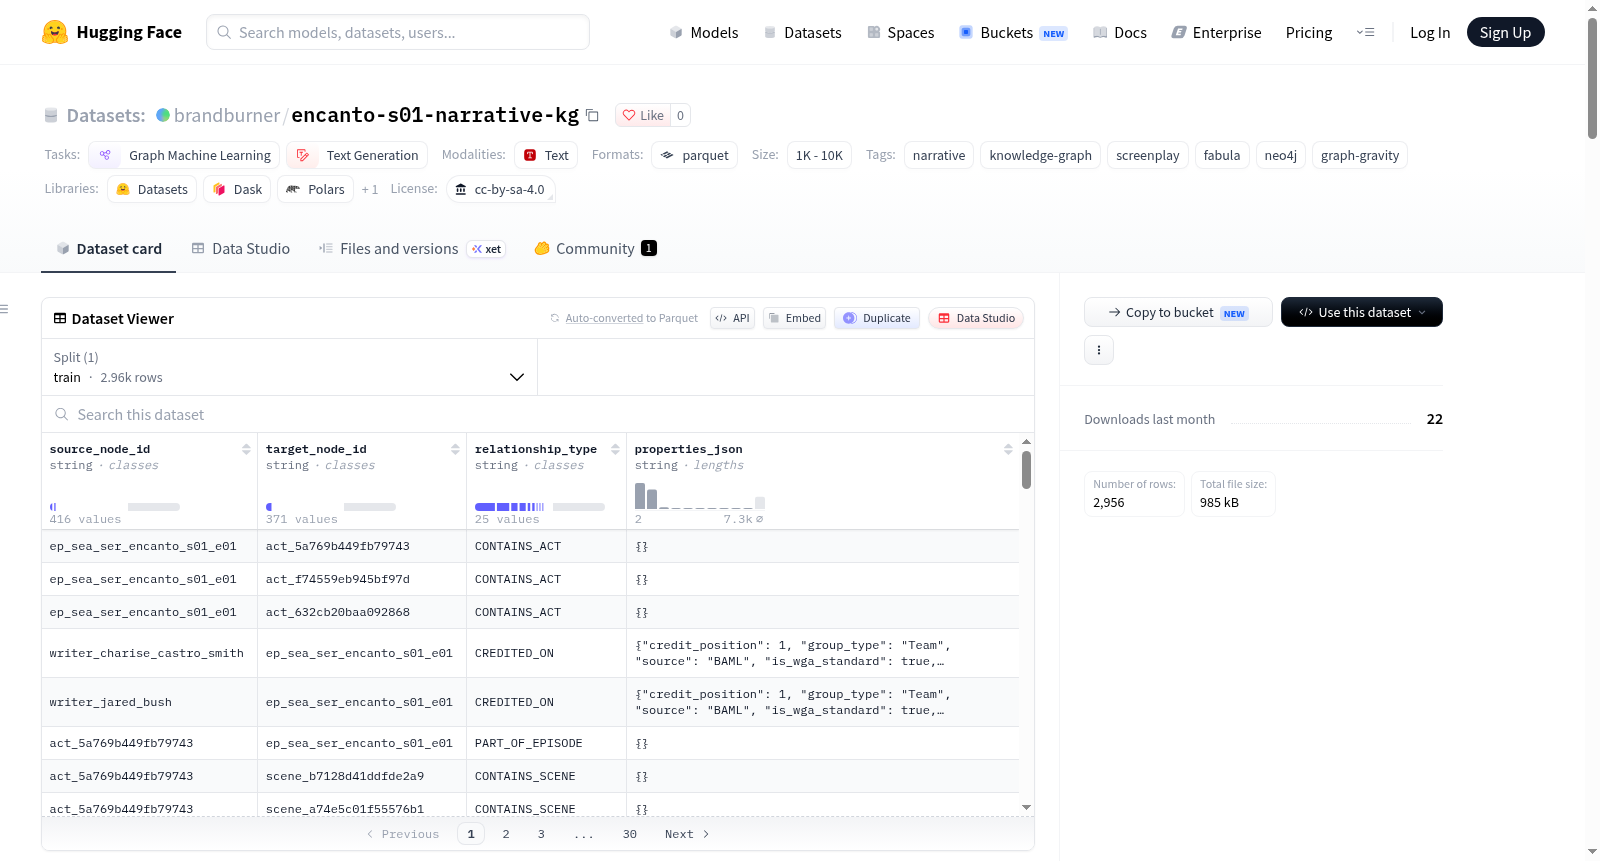
--- license: cc-by-sa-4.0 task_categories: - graph-ml - text-generation tags: - narrative - knowledge-graph - screenplay - fabula - neo4j - graph-gravity size_categories: - 1K<n<10K --- # Encanto - Narrative Knowledge Graph A rich narrative knowledge graph extracted from *Encanto* screenplays using the [Fabula](https://fabula.productions) pipeline. Contains characters, locations, objects, organizations, events, themes, and conflict arcs with full participation semantics and Graph Gravity importance tiers. ## Dataset Overview | Metric | Value | |--------|-------| | Source database | `encanto.s01` | | Type | Season database | | Episodes | 1 | | Total nodes | 605 | | Total edges | 1,746 | | Schema version | 1.1.0 | | Exported | 2026-05-27 | ### Entity Breakdown | Type | Count | |------|-------| | Act | 3 | | Agent | 50 | | ConflictArc | 11 | | Episode | 1 | | Event | 98 | | Location | 57 | | Object | 128 | | Organization | 3 | | PlotBeat | 183 | | SceneBoundary | 65 | | Theme | 4 | | Writer | 2 | ### Graph Gravity Tiers | Tier | Count | Description | |------|-------|-------------| | anchor | 0 | Main characters / key locations | | planet | 0 | Recurring entities | | asteroid | 238 | Minor / one-off entities | ### Relationship Types `AFFILIATED_WITH`, `BELONGS_TO_EPISODE`, `CALLBACK`, `CAUSAL`, `CHARACTER_CONTINUITY`, `CONTAINS_ACT`, `CONTAINS_BEAT`, `CONTAINS_SCENE`, `CREDITED_ON`, `EMOTIONAL_ECHO`, `ESCALATION`, `EXEMPLIFIES_THEME`, `FORESHADOWING`, `INVOLVED_IN_ARC`, `INVOLVED_WITH`, `IN_EVENT`, `OCCURS_IN`, `PARTICIPATED_AS`, `PART_OF`, `PART_OF_ACT` ... and 5 more ## Related Datasets This is a **single-season** dataset containing entities and events as extracted from Season 1 screenplays. - **Megagraph** (all seasons unified): [brandburner/encanto-mega-narrative-kg](https://huggingface.co/datasets/brandburner/encanto-mega-narrative-kg) > **Note:** The megagraph is *not* a simple union of season datasets. Cross-season entities are reconciled through a Global Entity Registry (GER), receiving new canonical UUIDs and distilled descriptions. Graph Gravity tiers are recalculated across all episodes. Use individual season datasets for single-season analysis; use the megagraph for cross-season analysis. ## Files | File | Description | |------|-------------| | `nodes.parquet` | All graph nodes with properties | | `edges.parquet` | All relationships with properties | | `positions.parquet` | 3D layout coordinates for visualization | | `meta.json` | Dataset metadata and entity counts | ## Schema ### Nodes (`nodes.parquet`) | Column | Type | Description | |--------|------|-------------| | `node_id` | string | Unique node identifier (UUID) | | `primary_label` | string | Node type (Agent, Location, Event, etc.) | | `name` | string | Display name | | `description` | string | Foundational description | | `tier` | string (nullable) | Graph Gravity tier: anchor / planet / asteroid | | `episode_count` | int (nullable) | Number of distinct episodes entity appears in | | `first_episode_seq` | int (nullable) | First appearance episode | | `last_episode_seq` | int (nullable) | Last appearance episode | | `properties_json` | string | Full node properties as JSON | ### Edges (`edges.parquet`) | Column | Type | Description | |--------|------|-------------| | `source_node_id` | string | Source node UUID | | `target_node_id` | string | Target node UUID | | `relationship_type` | string | Relationship type (e.g., PARTICIPATED_AS) | | `properties_json` | string | Edge properties as JSON | ### Positions (`positions.parquet`) | Column | Type | Description | |--------|------|-------------| | `node_id` | string | Node UUID | | `x`, `y`, `z` | float | 3D coordinates | | `size` | float | Node size (Graph Gravity weighted) | | `r`, `g`, `b` | int | RGB color by entity type | | `community` | int | Louvain community index | | `tier` | string (nullable) | Graph Gravity tier | ## Usage ```python from datasets import load_dataset import pandas as pd # Load from HuggingFace ds = load_dataset("brandburner/encanto-s01-narrative-kg") # Or load parquet directly nodes = pd.read_parquet("nodes.parquet") edges = pd.read_parquet("edges.parquet") # Filter to anchor characters anchors = nodes[(nodes['primary_label'] == 'Agent') & (nodes['tier'] == 'anchor')] # Build a NetworkX graph import networkx as nx G = nx.DiGraph() for _, n in nodes.iterrows(): G.add_node(n['node_id'], label=n['primary_label'], name=n['name']) for _, e in edges.iterrows(): G.add_edge(e['source_node_id'], e['target_node_id'], type=e['relationship_type']) ``` ## Citation ```bibtex @misc{fabula_encanto_s01, title = {Encanto Narrative Knowledge Graph}, author = {Fabula Pipeline}, year = {2026}, publisher = {HuggingFace}, howpublished = {\url{https://huggingface.co/datasets/brandburner/encanto-s01-narrative-kg}} } ``` ## License CC BY-SA 4.0
Encanto Narrative Knowledge Graph is a rich narrative knowledge graph extracted from Disneys Encanto screenplays using the Fabula pipeline. It contains characters, locations, objects, organizations, events, themes, and conflict arcs with full participation semantics and Graph Gravity importance tiers. The dataset includes 605 nodes and 1,746 edges, covering entity types such as 50 agents, 57 locations, 128 objects, 98 events, and relationship types like AFFILIATED_WITH, CAUSAL, and PARTICIPATED_AS. It is suitable for graph machine learning and text generation tasks, and can be used for narrative analysis, knowledge graph visualization, and story understanding applications.