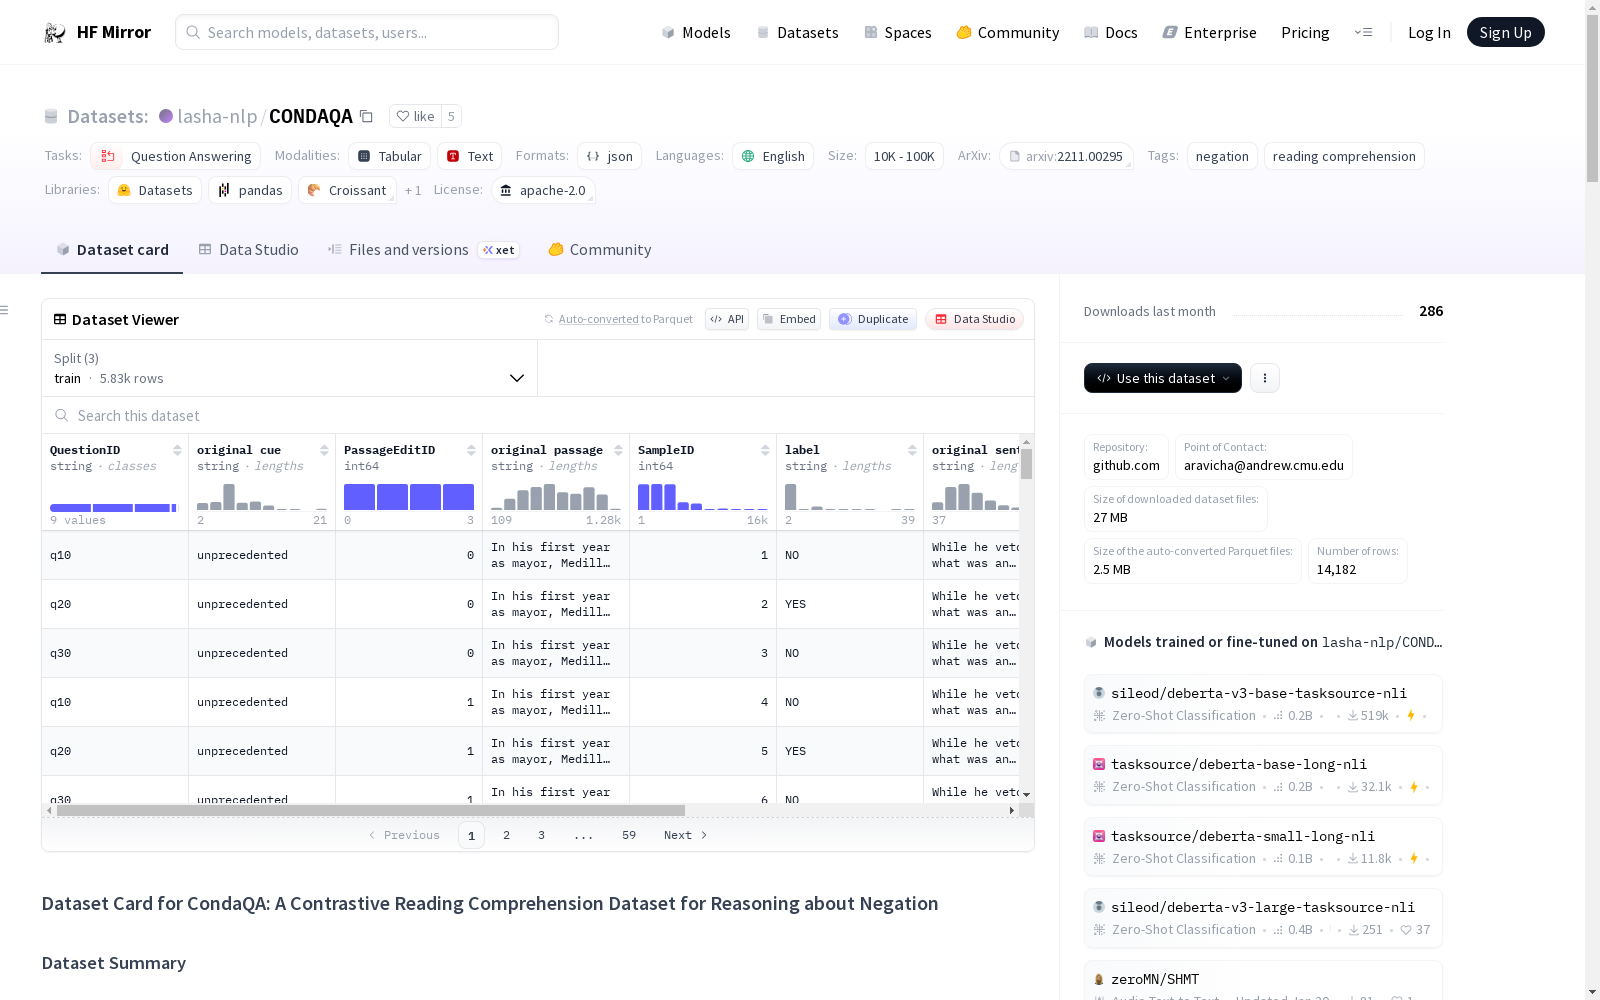
lasha-nlp/CONDAQA
收藏资源简介:
CondaQA是一个用于推理否定语句的对比阅读理解数据集,旨在促进未来模型在处理否定语句方面的有效发展。这是第一个需要推理段落中否定语句含义的英文阅读理解数据集。数据集包含14,182个问答对,涵盖了200多种独特的否定提示。通过众包方式,数据集的段落经过了三种编辑:否定语句的改写、否定范围的修改以及否定语句的反转,从而形成了一组难以通过虚假线索回答的问答对。数据集的结构包括原始段落、编辑后的段落、问题及其答案,数据字段包括QuestionID、original cue、PassageEditID、original passage、SampleID、label、original sentence、sentence2、PassageID和sentence1。数据集的任务是回答包含否定语句的维基百科段落中的问题,目前没有官方排行榜。
CondaQA is a contrastive reading comprehension dataset designed for reasoning over negated statements, with the goal of advancing the effective development of future models in handling negated linguistic expressions. This is the first English reading comprehension dataset that necessitates reasoning over the meaning of negated statements within textual passages. The dataset comprises 14,182 question-answer pairs, covering more than 200 distinct negation cues. Through crowdsourcing, the passages in the dataset have been subjected to three types of editorial modifications: paraphrasing of negated statements, adjustment of negation scopes, and reversal of negated statements, resulting in question-answer pairs that are challenging to solve via spurious cues. The dataset structure encompasses original passages, edited passages, questions and their corresponding answers, with the data fields including QuestionID, original cue, PassageEditID, original passage, SampleID, label, original sentence, sentence2, PassageID, and sentence1. The task of this dataset is to answer questions based on Wikipedia passages that contain negated statements, and there is currently no official leaderboard available for it.
数据集概述
名称: CondaQA
描述: CondaQA是一个英语阅读理解数据集,专注于推理关于否定句的含义。它是首个要求对段落中否定句的含义进行推理的英语阅读理解数据集。数据集包含14,182个问答对,涵盖超过200种独特的否定提示。
语言: 英语
许可证: Apache-2.0
大小: 10K<n<100K
任务: 问答
特点: 数据集通过对比阅读理解任务,评估模型处理否定句含义的能力。每个实例包括一个问题和相关的段落,其中包含否定句。
数据集结构
数据实例: 每个实例包含问题ID、原始提示、段落编辑ID、原始段落、样本ID、标签、原始句子、问题、段落ID和段落。
数据字段:
QuestionID: 问题唯一IDoriginal cue: 用于从维基百科中选择段落的否定提示PassageEditID: 段落编辑类型标识original passage: 原始维基百科段落SampleID: 段落-问题对唯一IDlabel: 答案original sentence: 包含否定句的句子sentence2: 问题PassageID: 维基百科段落唯一IDsentence1: 段落
数据分割: 数据集分为训练集、开发集和测试集。
数据集创建
来源数据: 数据集基于2021年7月的英语维基百科段落,包含各种否定提示。
注释过程: 通过众包工作者进行,他们首先对原始段落进行三种类型的编辑(重述否定句、改变否定范围、反转否定),然后提出关于否定句含义的挑战性问题,并回答这些问题。
注释者: 通过资格考试筛选的众包工作者。
使用数据集的考虑
社会影响: 模型解决此数据集的能力可能被误解为对英语语言全面理解的能力,可能影响模型的部署和应用。
已知限制: 数据集目前是最大的评估模型处理否定句含义能力的数据集,但仍有可能构建更大的数据集,并扩展到其他语言。