perona-lab/CompoSET
收藏资源简介:
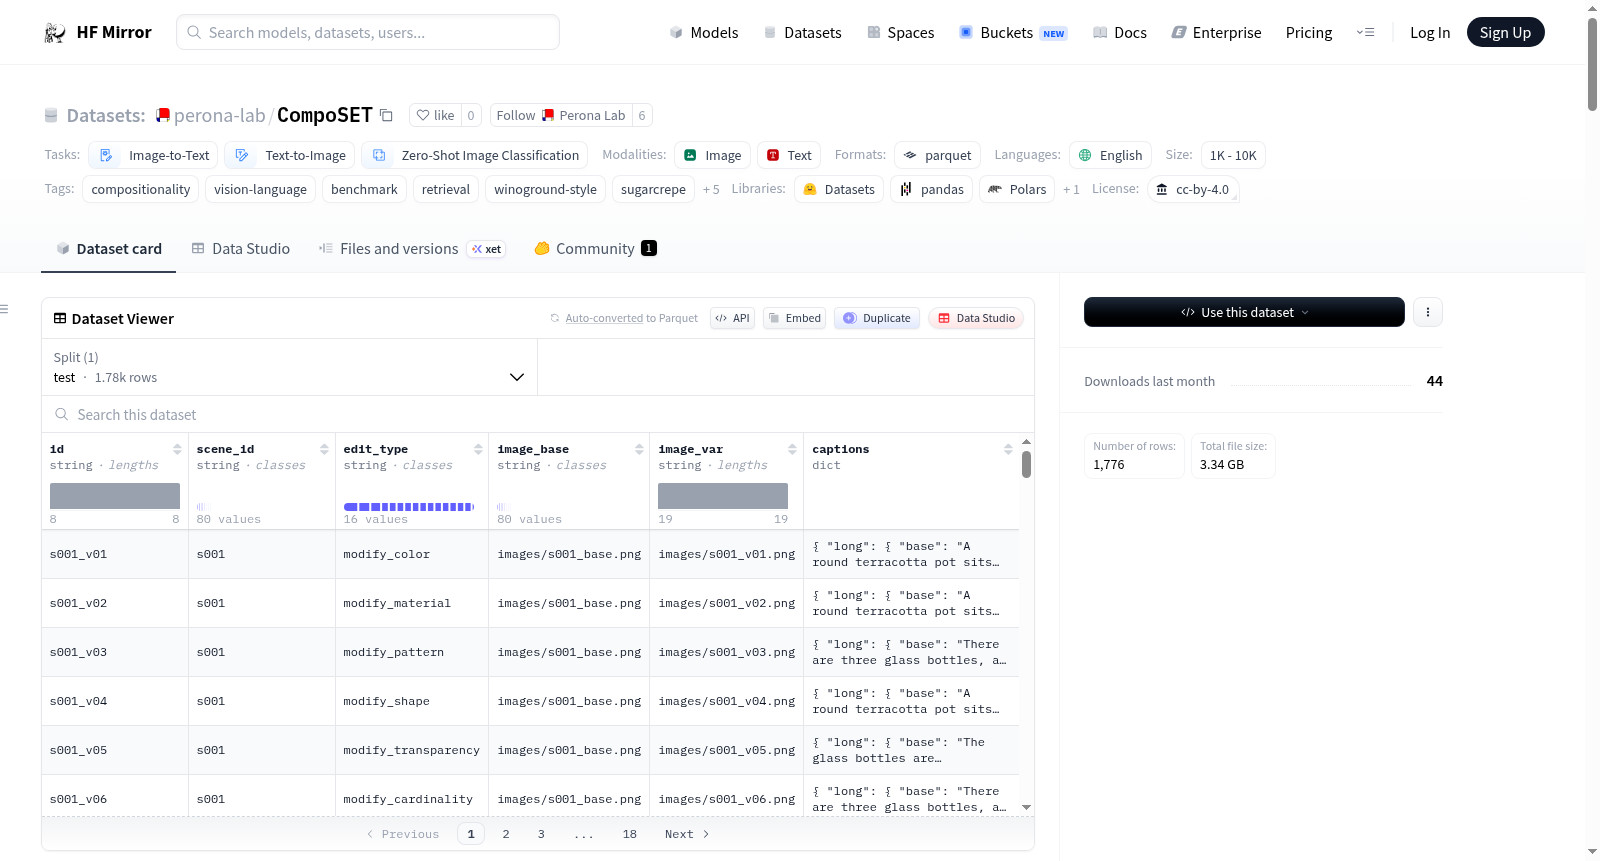
CompoSET是一个视觉语言组合性基准测试数据集,基于同一场景,单一编辑的原则构建。每对图像(基础图像和变化图像)仅在一个局部属性上有所不同,如颜色、材质、图案、姿势、空间排列等,而场景的其他部分保持不变。这种设计使得评估者能够将模型错误归因于特定的组合编辑,避免了之前基准测试中存在的更广泛场景组合混淆问题。数据集包含80个场景,1,776个有效变化,16种编辑类型,每种变化提供三种不同密度的标题(短、中、长)。数据集结构包括三个parquet文件和一个图像目录,主要用于评估视觉语言模型的组合绑定能力。
CompoSET is a vision-language compositionality benchmark built on the principle of same scene, one edit. Each pair of images (base, var) differs by exactly one localized attribute change — e.g. color, material, pattern, pose, spatial arrangement — while the rest of the scene is held constant. This lets evaluators attribute model errors to the specific compositional edit, isolated from broader scene-composition confounds that plague prior benchmarks. The dataset contains 80 scenes, 1,776 live variations, and 16 edit types, with three caption density tiers (short, medium, long) per variation. The dataset structure includes three parquet files and an image directory, primarily used for evaluating compositional binding in vision-language models.