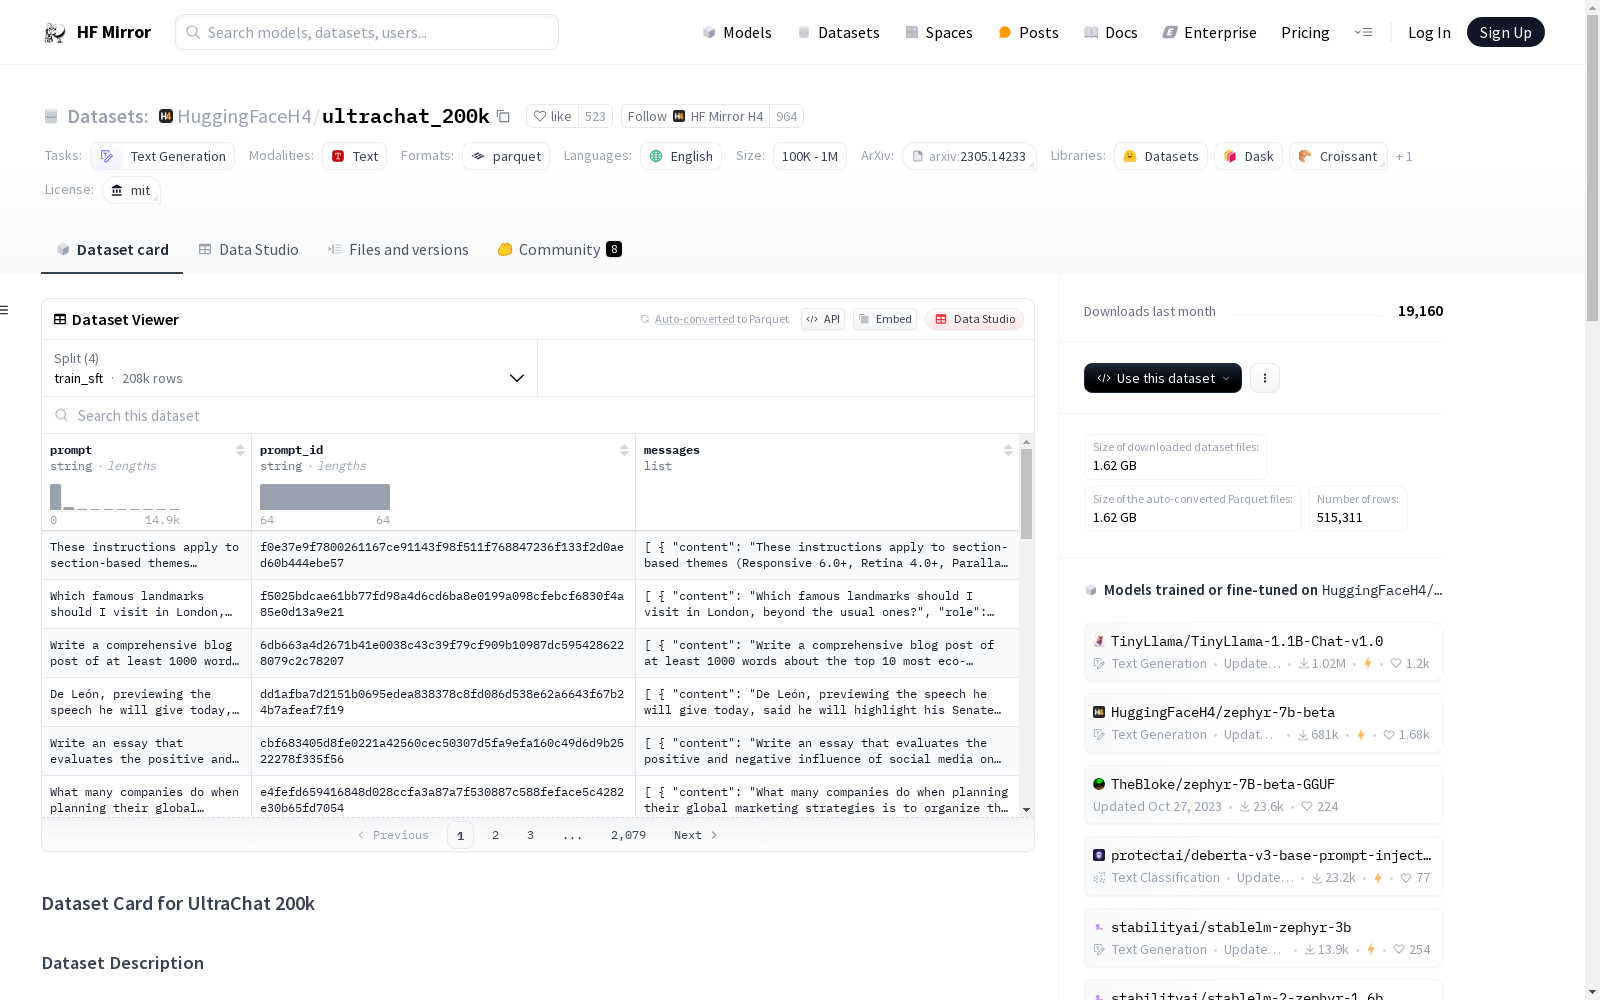
HuggingFaceH4/ultrachat_200k
收藏资源简介:
UltraChat 200k数据集是从UltraChat数据集中经过严格筛选得到的,用于训练Zephyr-7B-β模型。处理过程包括数据子集选择、语法错误修正和删除不合适的对话内容。数据集分为四个部分,适用于监督微调和生成排名。每个部分的数据量和存储格式也进行了详细说明。
The UltraChat 200k dataset is rigorously curated from the original UltraChat dataset for training the Zephyr-7B-β model. The data processing procedures include subset selection, grammatical error correction, and the removal of inappropriate conversational content. This dataset is divided into four partitions, which are suitable for supervised fine-tuning and generation ranking tasks. Detailed descriptions of the data volume and storage format for each partition are also provided.
数据集概述
基本信息
- 名称: UltraChat 200k
- 语言: 英语
- 许可证: MIT
- 大小: 100K<n<1M
- 任务类型: 文本生成
数据集结构
-
配置:
- 默认配置
- 训练数据:
train_sft,train_gen- 路径:
data/train_sft-*,data/train_gen-*
- 路径:
- 测试数据:
test_sft,test_gen- 路径:
data/test_sft-*,data/test_gen-*
- 路径:
- 训练数据:
- 默认配置
-
特征:
- prompt: 字符串类型
- prompt_id: 字符串类型
- messages: 列表类型
- content: 字符串类型
- role: 字符串类型
-
数据分割:
- train_sft: 207865个样本, 1397058554字节
- test_sft: 23110个样本, 154695659字节
- train_gen: 256032个样本, 1347396812字节
- test_gen: 28304个样本, 148276089字节
-
下载大小: 1624049723字节
-
数据集大小: 3047427114字节
使用场景
- 监督微调 (
sft) - 生成排名 (
gen) 使用技术如拒绝采样或PPO
数据示例
json { "prompt": "...", "messages": [ { "content": "...", "role": "user" }, { "content": "...", "role": "assistant" } ], "prompt_id": "..." }