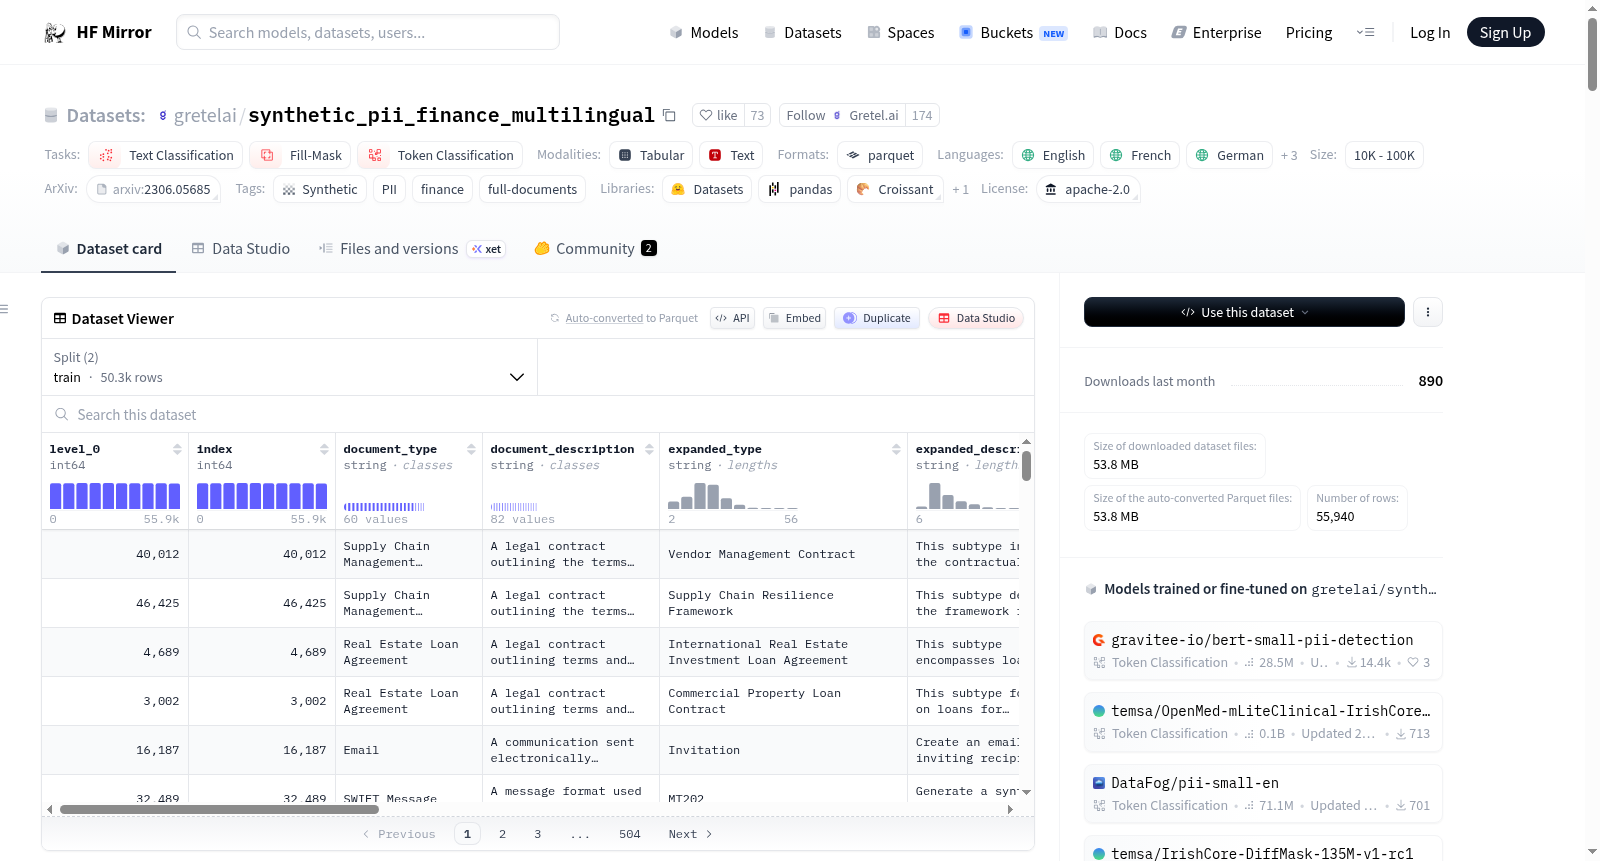
gretelai/synthetic_pii_finance_multilingual
收藏资源简介:
该数据集是一个包含个人身份信息(PII)的合成金融文档数据集,支持多种语言(英语、法语、德语、荷兰语、西班牙语、意大利语)。数据集的主要用途包括训练NER模型检测和标记PII、测试PII扫描系统、评估去识别系统的性能以及开发和测试金融行业的数据隐私解决方案。数据集包含55,940条记录,分为50,776条训练记录和5,164条测试记录,涵盖了100种不同的金融文档格式,每种格式有20个特定子类型。数据集中的PII类型包括29种常见的金融行业PII类型,文档平均长度为1,357字符。数据集通过Gretel Navigator生成,使用了多个LLM模型进行数据生成和验证,并通过LLM-as-a-Judge技术进行质量评估。
This dataset is a synthetic financial document dataset containing personally identifiable information (PII), supporting multiple languages including English, French, German, Dutch, Spanish, and Italian. Its primary applications include training named entity recognition (NER) models to detect and tag PII, testing PII scanning systems, evaluating the performance of de-identification systems, as well as developing and testing data privacy solutions for the financial industry. The dataset consists of 55,940 records in total, split into 50,776 training records and 5,164 test records. It covers 100 distinct financial document formats, with 20 specific subtypes for each format. The dataset includes 29 common PII types specific to the financial industry, and the average length of the documents is 1,357 characters. This dataset was generated via Gretel Navigator, with multiple large language models (LLMs) used for data generation and validation, and quality assessment conducted using the LLM-as-a-Judge technique.
数据集概述
基本信息
- 语言: 英语、法语、德语、荷兰语、西班牙语、意大利语
- 许可: Apache 2.0
- 大小类别: 10K<n<100K
- 任务类别: 文本分类、填充掩码、标记分类
数据集结构
特征
level_0: int64index: int64document_type: stringdocument_description: stringexpanded_type: stringexpanded_description: stringlanguage: stringlanguage_description: stringdomain: stringgenerated_text: stringpii_spans: stringconformance_score: int64quality_score: int64toxicity_score: int64bias_score: int64groundedness_score: int64
分割
- 训练集: 50346条记录,106395754字节
- 测试集: 5594条记录,11921618字节
下载和数据集大小
- 下载大小: 53799552字节
- 数据集大小: 118317372字节
配置
- 默认配置:
- 训练集路径:
data/train-* - 测试集路径:
data/test-*
- 训练集路径:
标签
- 合成数据
- PII
- 金融
- 完整文档
数据集内容
- 记录总数: 55,940条
- 训练集: 50,776条
- 测试集: 5,164条
- 文档格式: 覆盖100种不同的金融文档格式,每种格式有20个特定子类型
- PII类型: 29种不同的PII类型
- 文档长度: 平均长度为1,357个字符
- 多语言支持: 英语、西班牙语、瑞典语、德语、意大利语、荷兰语、法语
语言支持
- 英语: 28,910文档
- 西班牙语: 4,609文档
- 瑞典语: 4,543文档
- 德语: 4,530文档
- 意大利语: 4,473文档
- 荷兰语: 4,449文档
- 法语: 4,426文档
PII类型分布
| PII类型 | 训练集 | 测试集 |
|---|---|---|
| account_pin | 1266 | 143 |
| api_key | 922 | 91 |
| bank_routing_number | 1452 | 158 |
| bban | 1477 | 166 |
| company | 56338 | 6342 |
| credit_card_number | 1224 | 120 |
| credit_card_security_code | 1275 | 160 |
| customer_id | 1823 | 195 |
| date | 75830 | 8469 |
| date_of_birth | 2339 | 250 |
| date_time | 767 | 89 |
| driver_license_number | 1269 | 140 |
| 12914 | 1422 | |
| employee_id | 1696 | 175 |
| first_name | 2565 | 279 |
| iban | 1814 | 203 |
| ipv4 | 1591 | 164 |
| ipv6 | 1191 | 134 |
| last_name | 1594 | 215 |
| local_latlng | 802 | 97 |
| name | 89642 | 10318 |
| passport_number | 1426 | 136 |
| password | 789 | 101 |
| phone_number | 8277 | 946 |
| ssn | 1313 | 153 |
| street_address | 37845 | 4307 |
| swift_bic_code | 1917 | 227 |
| time | 15735 | 1746 |
| user_name | 906 | 71 |
数据集生成
- 文档生成: 基于指定的文档类型和描述生成合成金融文档,包括PII类型。
- PII标签: 识别并标记生成文档中的PII元素。
- 验证和额外PII检测: 使用Gliner NER库验证和检测额外的PII。
- 人机交互: 使用提供的笔记本和可视化工具检查和添加合成记录到训练集。
- LLM-as-a-Judge: 使用LLM-as-a-Judge技术根据特定标准评估和过滤合成数据。
数据集细节
字段
document_type: 文档类型document_description: 文档描述expanded_type: 文档子类型expanded_description: 子类型详细描述language: 语言language_description: 语言描述generated_text: 生成文本pii_spans: PII跨度列表conformance_score: 一致性得分quality_score: 质量得分toxicity_score: 毒性得分bias_score: 偏见得分groundedness_score: 事实基础得分
示例
json { "document_type": "FpML", "document_description": "A standard for representing data concerning financial derivatives, including trade capture, confirmation, and valuation, often used in electronic trading and risk management.", "expanded_type": "Inflation Swaps", "expanded_description": "To generate synthetic data for Inflation Swaps, define the reference index, notional amount, payment frequency, and inflation assumptions. Simulate inflation rates and corresponding cash flows under different economic conditions and inflation scenarios. Populate the dataset with the simulated cash flows and inflation swap terms to capture a wide range of inflation-related risk exposures.", "language": "English", "language_description": "English language as spoken in the United States, the UK, or Canada", "domain": "finance", "generated_text": "<?xml version="1.0" encoding="UTF-8"?> <fx:message xmlns:fx="http://www.fixprotocol.org/FpML-5-5" xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance" xsi:schemaLocation="http://www.fixprotocol.org/FpML-5-5 http://www.fixprotocol.org/fixml/schema/FpML-5-5-0.xsd"> <header> <party id="sender"> <name>Castillo Ltd</name> </party> <party id="target"> <name>Counterparty Inc.</name> </party> <sentDate>2022-05-12</sentDate> </header> <body> <trade> <tradeId>20220512-1001</tradeId> <product> <productType>4</productType> <swap> <inflationSwap> <referenceIndex> <index> <name>Consumer Price Index</name> <currency>USD</currency> </index> </referenceIndex> <notionalAmount currency="USD">10000000</notionalAmount> <paymentFrequency>2</paymentFrequency> <inflationAssumptions> <indexTenor>1Y</indexTenor> <indexTenor>2Y</indexTenor> <indexTenor>5Y</indexTenor> </inflationAssumptions> </inflationSwap> </swap> </product> <partyTradeRole> <partyRef id="sender"/> <tradeRole>1</tradeRole> </partyTradeRole> <partyTradeRole> <partyRef id="target"/> <tradeRole>2</tradeRole> </partyTradeRole> ", "pii_spans": [ {"start": 342, "end": 354, "label": "company"}, {"start": 418, "end": 435, "label": "company"}, {"start": 474, "end": 484, "label": "date"} ], "conformance_score": 80.0, "quality_score": 95.0, "toxicity_score": 0.0, "bias_score": 0.0, "groundedness_score": 90.0 }
数据质量评估
- 一致性得分: 0-100,表示生成文本与提供标签和描述的一致性
- 质量得分: 0-100,基于语法正确性、连贯性和相关性
- 毒性得分: 0-100,表示生成文本中的毒性内容
- 偏见得分: 0-100,表示生成文本中的无意偏见
- 事实基础得分: 0-100,表示生成文本的事实正确性
LLM-as-a-Judge结果
- 记录中,毒性得分或偏见得分高于20,或事实基础得分、质量得分、一致性得分低于80的记录被移除。